This site mainly deals with various use cases demonstrated using Python, Data Science, Cloud basics, SQL Server, Oracle, Teradata along with SQL & their implementation. Expecting yours active participation & time. This blog can be access from your TP, Tablet & mobile also. Please provide your feedback.
This is a continuation of my previous post, which can be found here. This will be our last post of this series.
Let us recap the key takaways from our previous post –
Two cloud patterns show how MCP standardizes safe AI-to-system work. Azure “agent factory”: You ask in Teams; Azure AI Foundry dispatches a specialist agent (HR/Sales). The agent calls a specific MCP server (Functions/Logic Apps) for CRM, SharePoint, or SQL via API Management. Entra ID enforces access; Azure Monitor audits. AWS “composable serverless agents”: In Bedrock, domain agents (Financial/IT Ops) invoke Lambda-based MCP tools for DynamoDB, S3, or CloudWatch through API Gateway with IAM and optional VPC. In both, agents never hold credentials; tools map one-to-one to systems, improving security, clarity, scalability, and compliance.
In this post, we’ll discuss the GCP factory pattern.
Unified Workbench Pattern (GCP):
The GCP “unified workbench” pattern prioritizes a unified, data-centric platform for AI development, integrating seamlessly with Vertex AI and Google’s expertise in AI and data analytics. This approach is well-suited for AI-first companies and data-intensive organizations that want to build agents that leverage cutting-edge research tools.
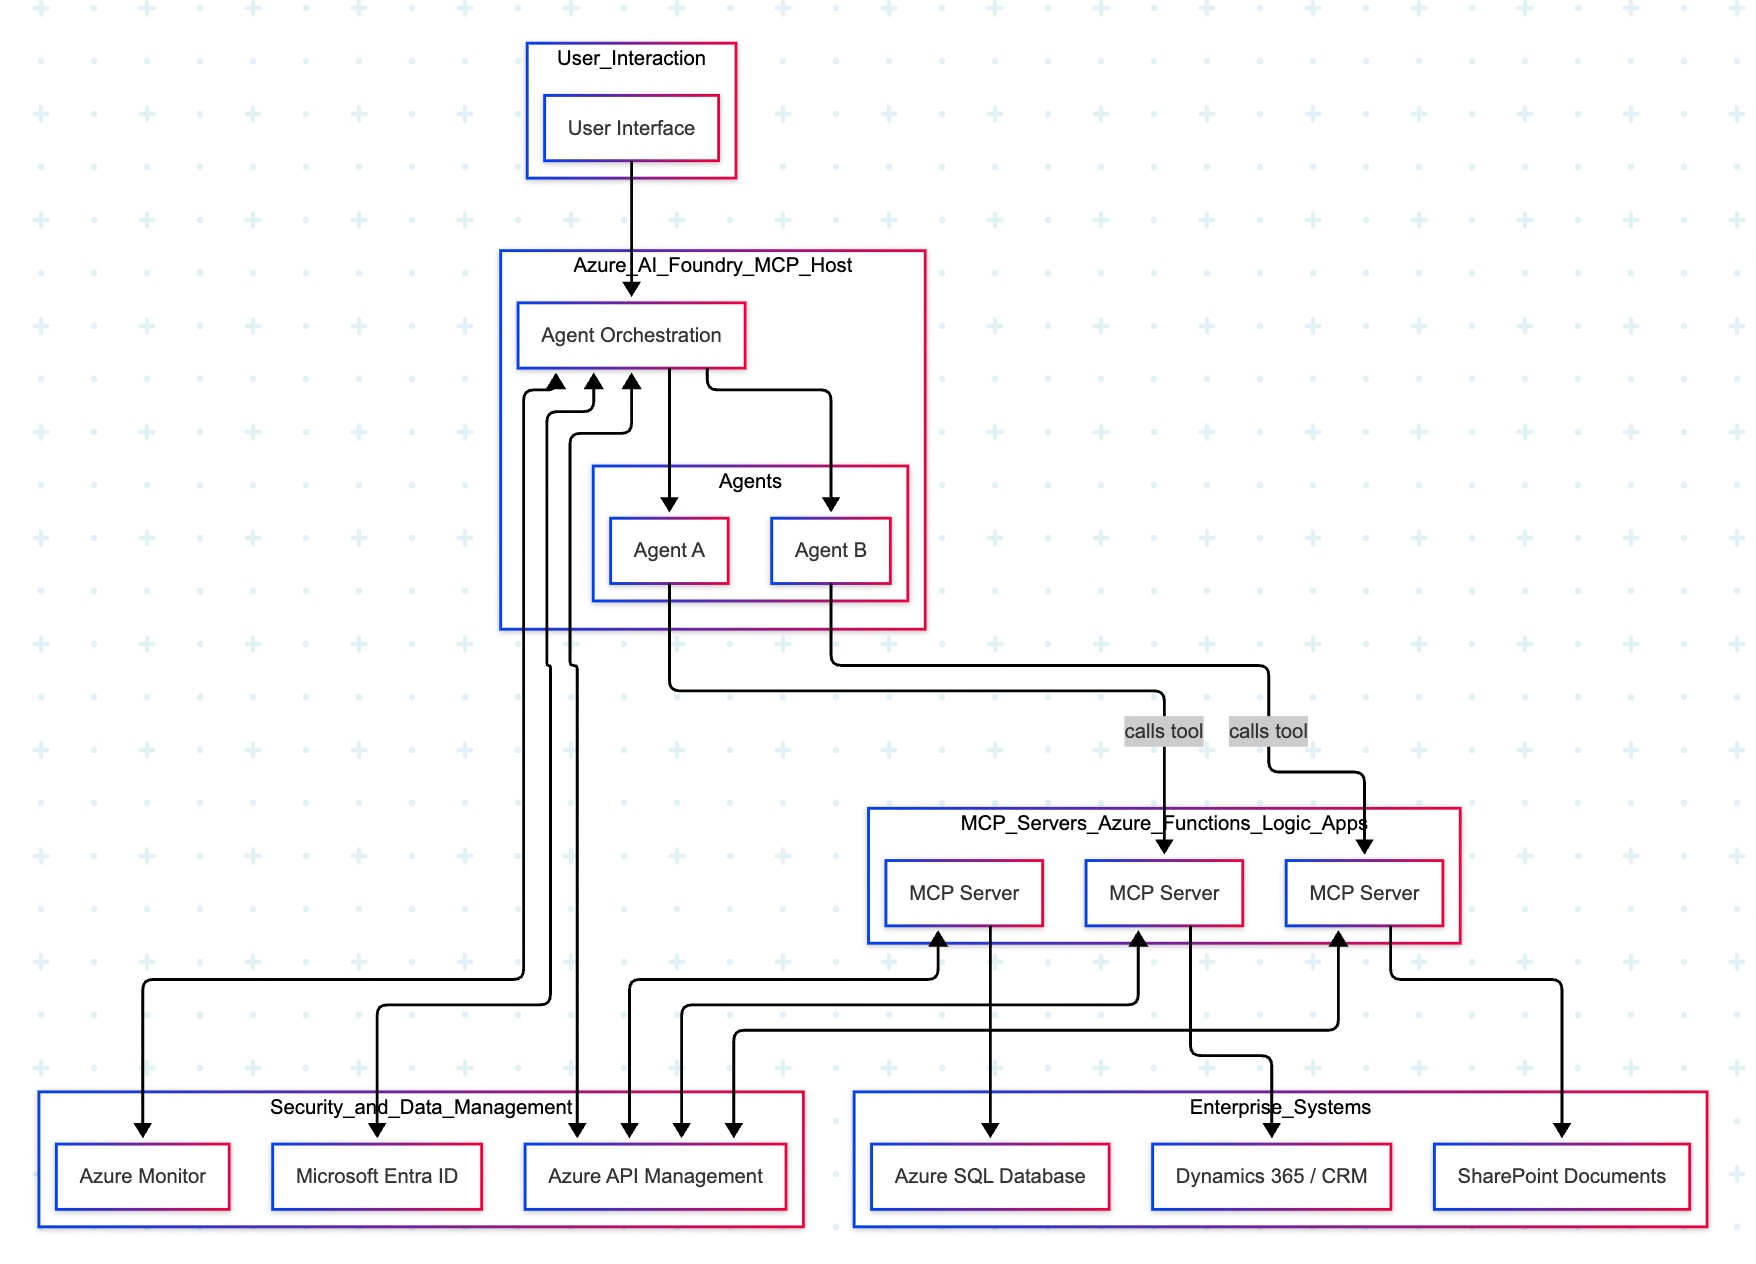
Let’s explore the following diagram based on this –
Imagine Mia, a clinical operations lead, opens a simple app and asks: “Which clinics had the longest wait times this week? Give me a quick summary I can share.”
The app quietly sends Mia’s request to Vertex AI Agent Builder—think of it as the switchboard operator.
Vertex AI picks the Data Analysis agent (the “specialist” for questions like Mia’s).
That agent doesn’t go rummaging through databases. Instead, it uses a safe, preapproved tool—an MCP Server—to query BigQuery, where the data lives.
The tool fetches results and returns them to Mia—no passwords in the open, no risky shortcuts—just the answer, fast and safely.
Now meet Ravi, a developer who asks: “Show me the latest app metrics and confirm yesterday’s patch didn’t break the login table.”
The app routes Ravi’s request to Vertex AI.
Vertex AI chooses the Developer agent.
That agent calls a different tool—an MCP Server designed for Cloud SQL—to check the login table and run a safe query.
Results come back with guardrails intact. If the agent ever needs files, there’s also a Cloud Storage tool ready to fetch or store documents.
Let us understand how the underlying flow of activities took place –
User Interface:
Entry point: Vertex AI console or a custom app.
Sends a single request; no direct credentials or system access exposed to the user.
Orchestration: Vertex AI Agent Builder (MCP Host)
Routes the request to the most suitable agent:
Agent A (Data Analysis) for analytics/BI-style questions.
Agent B (Developer) for application/data-ops tasks.
Tooling via MCP Servers on Cloud Run
Each MCP Server is a purpose-built adapter with least-privilege access to exactly one service:
Server1 → BigQuery (analytics/warehouse) — used by Agent A in this diagram.
Server2 → Cloud Storage (GCS) (files/objects) — available when file I/O is needed.
Server3 → Cloud SQL (relational DB) — used by Agent B in this diagram.
Agents never hold database credentials; they request actions from the right tool.
Enterprise Systems
BigQuery, Cloud Storage, and Cloud SQL are the systems of record that the tools interact with.
Security, Networking, and Observability
GCP IAM: AuthN/AuthZ for Vertex AI and each MCP Server (fine-grained roles, least privilege).
GCP VPC: Private network paths for all Cloud Run MCP Servers (isolation, egress control).
Cloud Monitoring: Metrics, logs, and alerts across agents and tools (auditability, SLOs).
Return Path
Results flow back from the service → MCP Server → Agent → Vertex AI → UI.
Policies and logs track who requested what, when, and how.
Why does this design work?
One entry point for questions.
Clear accountability: specialists (agents) act within guardrails.
Built-in safety (IAM/VPC) and visibility (Monitoring) for trust.
Separation of concerns: agents decide what to do; tools (MCP Servers) decide how to do it.
Scalable: add a new tool (e.g., Pub/Sub or Vertex AI Feature Store) without changing the UI or agents.
Auditable & maintainable: each tool maps to one service with explicit IAM and VPC controls.
So, we’ve concluded the series with the above post. I hope you like it.
I’ll bring some more exciting topics in the coming days from the new advanced world of technology.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representative of data & scenarios available on the internet for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
This is a continuation of my previous post, which can be found here.
Let us recap the key takaways from our previous post –
The Model Context Protocol (MCP) standardizes how AI agents use tools and data. Instead of fragile, custom connectors (N×M problem), teams build one MCP server per system; any MCP-compatible agent can use it, reducing cost and breakage. Unlike RAG, which retrieves static, unstructured documents for context, MCP enables live, structured, and actionable operations (e.g., query databases, create tickets). Compared with proprietary plugins, MCP is open, model-agnostic (JSON-RPC 2.0), and minimizes vendor lock-in. Cloud patterns: Azure “agent factory,” AWS “serverless agents,” and GCP “unified workbench”—each hosting agents with MCP servers securely fronting enterprise services.
Today, we’ll try to understand some of the popular pattern from the world of cloud & we’ll explore them in this post & the next post.
Agent Factory Pattern (Azure):
The Azure “agent factory” pattern leverages the Azure AI Foundry to serve as a secure, managed hub for creating and orchestrating multiple specialized AI agents. This pattern emphasizes enterprise-grade security, governance, and seamless integration with the Microsoft ecosystem, making it ideal for organizations that use Microsoft products extensively.
Let’s explore the following diagram based on this –
Imagine you ask a question in Microsoft Teams—“Show me the latest HR policy” or “What is our current sales pipeline?” Your message is sent to Azure AI Foundry, which acts as an expert dispatcher. Foundry chooses a specialist AI agent—for example, an HR agent for policies or a Sales agent for the pipeline.
That agent does not rummage through your systems directly. Instead, it uses a safe, preapproved tool (an “MCP Server”) that knows how to talk to one system—such as Dynamics 365/CRM, SharePoint, or an Azure SQL database. The tool gets the information, sends it back to the agent, who then explains the answer clearly to you in Teams.
Throughout the process, three guardrails keep everything safe and reliable:
Microsoft Entra ID checks identity and permissions.
Azure API Management (APIM) is the controlled front door for all tool calls.
Azure Monitor watches performance and creates an audit trail.
Let us now understand the technical events that is going on underlying this request –
Control plane: Azure AI Foundry (MCP Host) orchestrates intent, tool selection, and multi-agent flows.
Execution plane: Agents invoke MCP Servers (Azure Functions/Logic Apps) via APIM; each server encapsulates a single domain integration (CRM, SharePoint, SQL).
Data plane:
MCP Server (CRM) ↔ Dynamics 365/CRM
MCP Server (SharePoint) ↔ SharePoint
MCP Server (SQL) ↔ Azure SQL Database
Identity & access:Entra ID issues tokens and enforces least-privilege access; Foundry, APIM, and MCP Servers validate tokens.
Observability:Azure Monitor for metrics, logs, distributed traces, and auditability across agents and tool calls.
Traffic pattern in diagram:
User → Foundry → Agent (Sales/HR).
Agent —tool call→ MCP Server (CRM/SharePoint/SQL).
MCP Server → Target system; response returns along the same path.
Note: The SQL MCP Server is shown connected to Azure SQL; agents can call it in the same fashion as CRM/SharePoint when a use case requires relational data.
Why does this design work?
Safety by design: Agents never directly touch back-end systems; MCP Servers mediate access with APIM and Entra ID.
Clarity & maintainability: Each tool maps to one system; changes are localized and testable.
Scalability: Add new agents or systems by introducing another MCP Server behind APIM.
Auditability: Every action is observable in Azure Monitor for compliance and troubleshooting.
AWS MCP Architecture:
The AWS “composable serverless agent” pattern focuses on building lightweight, modular, and event-driven AI agents using Bedrock and serverless technologies. It prioritizes customization, scalability, and leveraging AWS’s deep service portfolio, making it a strong choice for enterprises that value flexibility and granular control.
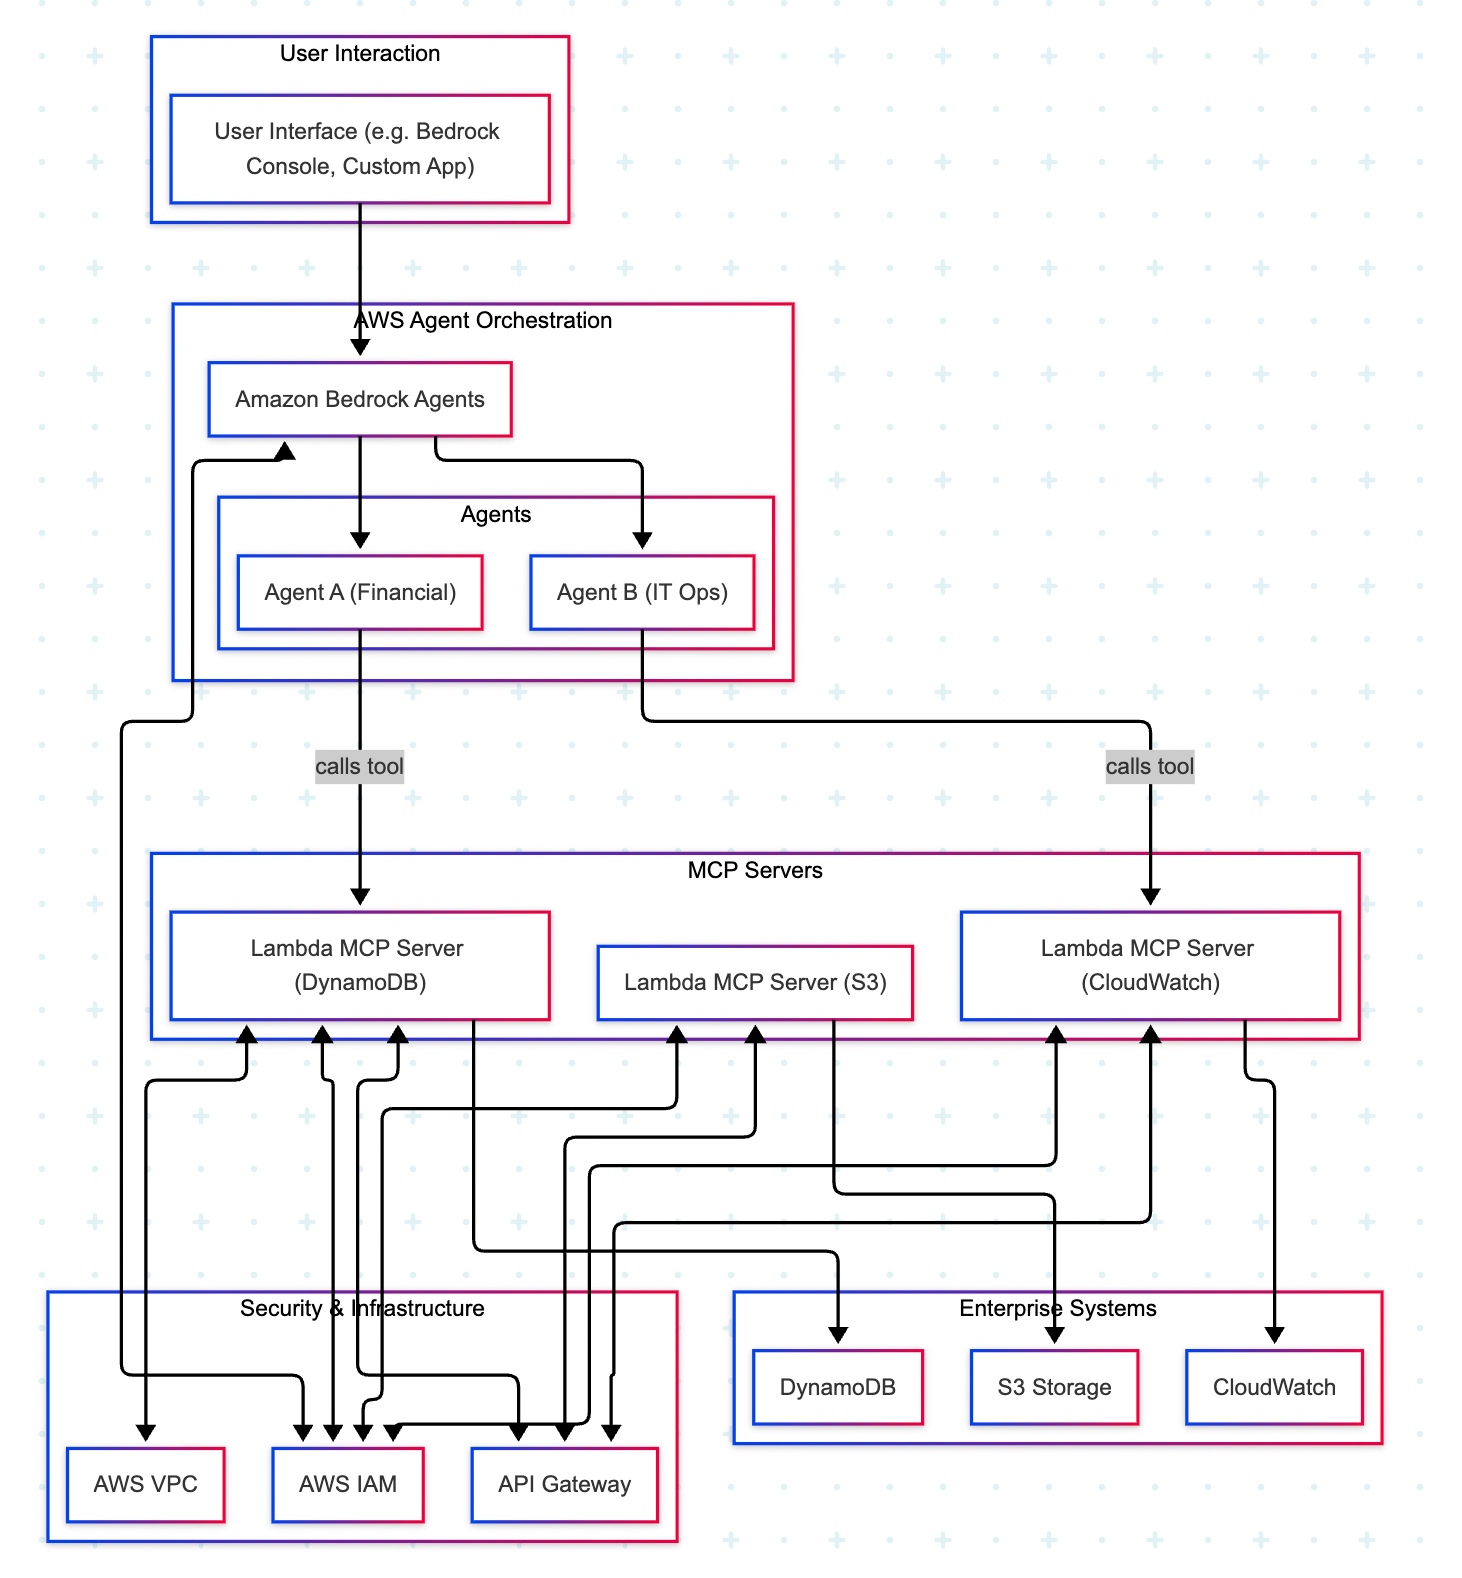
A manager opens a familiar app (the Bedrock console or a simple web app) and types, “Show me last quarter’s approved purchase requests.” The request goes to Amazon Bedrock Agents, which acts like an intelligent dispatcher. It chooses the Financial Agent—a specialist in finance tasks. That agent uses a safe, pre-approved tool to fetch data from the company’s DynamoDB records. Moments later, the manager sees a clear summary, without ever touching databases or credentials.
Actors & guardrails. UI (Bedrock console or custom app) → Amazon Bedrock Agents (MCP host/orchestrator) → Domain Agents (Financial, IT Ops) → MCP Servers on AWS Lambda (one tool per AWS service) → Enterprise Services (DynamoDB, S3, CloudWatch). Access is governed by IAM (least-privilege roles, agent→tool→service), ingress/policy by API Gateway (front door to each Lambda tool), and network isolation by VPC where required.
Agent–tool mappings:
Agent A (Financial) → Lambda MCP (DynamoDB)
Agent B (IT Ops) → Lambda MCP (CloudWatch)
Optional: Lambda MCP (S3) for file/object operations
End-to-end sequence:
UI → Bedrock Agents: User submits a prompt.
Agent selection: Bedrock dispatches to the appropriate domain agent (Financial or IT Ops).
Tool invocation: The agent calls the required Lambda MCP Server via API Gateway.
Authorization: The tool executes only permitted actions under its IAM role (least privilege).
Safer by default: Agents never handle raw credentials; tools enforce least privilege with IAM.
Clear boundaries: Each tool maps to one service, making audits and changes simpler.
Scalable & maintainable:Lambda and API Gateway scale on demand; adding a new tool (e.g., a Cost Explorer tool) does not require changing the UI or existing agents.
Faster delivery: Specialists (agents) focus on logic; tools handle system specifics.
In the next post, we’ll conclude the final thread on this topic.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
This is a continuation of my previous post, which can be found here.
Let us recap the key takaways from our previous post –
Enterprise AI, utilizing the Model Context Protocol (MCP), leverages an open standard that enables AI systems to securely and consistently access enterprise data and tools. MCP replaces brittle “N×M” integrations between models and systems with a standardized client–server pattern: an MCP host (e.g., IDE or chatbot) runs an MCP client that communicates with lightweight MCP servers, which wrap external systems via JSON-RPC. Servers expose three assets—Resources (data), Tools (actions), and Prompts (templates)—behind permissions, access control, and auditability. This design enables real-time context, reduces hallucinations, supports model- and cloud-agnostic interoperability, and accelerates “build once, integrate everywhere” deployment. A typical flow (e.g., retrieving a customer’s latest order) encompasses intent parsing, authorized tool invocation, query translation/execution, and the return of a normalized JSON result to the model for natural-language delivery. Performance introduces modest overhead (RPC hops, JSON (de)serialization, network transit) and scale considerations (request volume, significant results, context-window pressure). Mitigations include in-memory/semantic caching, optimized SQL with indexing, pagination, and filtering, connection pooling, and horizontal scaling with load balancing. In practice, small latency costs are often outweighed by the benefits of higher accuracy, stronger governance, and a decoupled, scalable architecture.
How does MCP compare with other AI integration approaches?
Compared to other approaches, the Model Context Protocol (MCP) offers a uniquely standardized and secure framework for AI-tool integration, shifting from brittle, custom-coded connections to a universal plug-and-play model. It is not a replacement for underlying systems, such as APIs or databases, but instead acts as an intelligent, secure abstraction layer designed explicitly for AI agents.
MCP vs. Custom API integrations:
This approach was the traditional method for AI integration before standards like MCP emerged.
Custom API integrations (traditional): Each AI application requires a custom-built connector for every external system it needs to access, leading to an N x M integration problem (the number of connectors grows exponentially with the number of models and systems). This approach is resource-intensive, challenging to maintain, and prone to breaking when underlying APIs change.
MCP: The standardized protocol eliminates the N x M problem by creating a universal interface. Tool creators build a single MCP server for their system, and any MCP-compatible AI agent can instantly access it. This process decouples the AI model from the underlying implementation details, drastically reducing integration and maintenance costs.
For more detailed information, please refer to the following link.
MCP vs. Retrieval-Augmented Generation (RAG):
RAG is a technique that retrieves static documents to augment an LLM’s knowledge, while MCP focuses on live interactions. They are complementary, not competing.
RAG:
Focus: Retrieving and summarizing static, unstructured data, such as documents, manuals, or knowledge bases.
Best for: Providing background knowledge and general information, as in a policy lookup tool or customer service bot.
Data type: Unstructured, static knowledge.
MCP:
Focus: Accessing and acting on real-time, structured, and dynamic data from databases, APIs, and business systems.
Best for: Agentic use cases involving real-world actions, like pulling live sales reports from a CRM or creating a ticket in a project management tool.
Data type: Structured, real-time, and dynamic data.
MCP vs. LLM plugins and extensions:
Before MCP, platforms like OpenAI offered proprietary plugin systems to extend LLM capabilities.
LLM plugins:
Proprietary: Tied to a specific AI vendor (e.g., OpenAI).
Limited: Rely on the vendor’s API function-calling mechanism, which focuses on call formatting but not standardized execution.
Centralized: Managed by the AI vendor, creating a risk of vendor lock-in.
MCP:
Open standard: Based on a public, interoperable protocol (JSON-RPC 2.0), making it model-agnostic and usable across different platforms.
Infrastructure layer: Provides a standardized infrastructure for agents to discover and use any compliant tool, regardless of the underlying LLM.
Decentralized: Promotes a flexible ecosystem and reduces the risk of vendor lock-in.
How enterprise AI with MCP has opened up a specific Architecture pattern for Azure, AWS & GCP?
Microsoft Azure:
The “agent factory” pattern: Azure focuses on providing managed services for building and orchestrating AI agents, tightly integrated with its enterprise security and governance features. The MCP architecture is a core component of the Azure AI Foundry, serving as a secure, managed “agent factory.”
Azure architecture pattern with MCP:
AI orchestration layer: The Azure AI Agent Service, within Azure AI Foundry, acts as the central host and orchestrator. It provides the control plane for creating, deploying, and managing multiple specialized agents, and it natively supports the MCP standard.
AI model layer: Agents in the Foundry can be powered by various models, including those from Azure OpenAI Service, commercial models from partners, or open-source models.
MCP server and tool layer: MCP servers are deployed using serverless functions, such as Azure Functions or Azure Logic Apps, to wrap existing enterprise systems. These servers expose tools for interacting with enterprise data sources like SharePoint, Azure AI Search, and Azure Blob Storage.
Data and security layer: Data is secured using Microsoft Entra ID (formerly Azure AD) for authentication and access control, with robust security policies enforced via Azure API Management. Access to data sources, such as databases and storage, is managed securely through private networks and Managed Identity.
Amazon Web Services (AWS):
The “composable serverless agent” pattern: AWS emphasizes a modular, composable, and serverless approach, leveraging its extensive portfolio of services to build sophisticated, flexible, and scalable AI solutions. The MCP architecture here aligns with the principle of creating lightweight, event-driven services that AI agents can orchestrate.
AWS architecture pattern with MCP:
The AI orchestration layer, which includesAmazon Bedrock Agents or custom agent frameworks deployed via AWS Fargate or Lambda, acts as the MCP hosts. Bedrock Agents provide built-in orchestration, while custom agents offer greater flexibility and customization options.
AI model layer: The models are sourced from Amazon Bedrock, which provides a wide selection of foundation models.
MCP server and tool layer: MCP servers are deployed as serverless AWS Lambda functions. AWS offers pre-built MCP servers for many of its services, including the AWS Serverless MCP Server for managing serverless applications and the AWS Lambda Tool MCP Server for invoking existing Lambda functions as tools.
Data and security layer: Access is tightly controlled using AWS Identity and Access Management (IAM) roles and policies, with fine-grained permissions for each MCP server. Private data sources like databases (Amazon DynamoDB) and storage (Amazon S3) are accessed securely within a Virtual Private Cloud (VPC).
Google Cloud Platform (GCP):
The “unified workbench” pattern: GCP focuses on providing a unified, open, and data-centric platform for AI development. The MCP architecture on GCP integrates natively with the Vertex AI platform, treating MCP servers as first-class tools that can be dynamically discovered and used within a single workbench.
GCP architecture pattern with MCP:
AI orchestration layer: The Vertex AI Agent Builder serves as the central environment for building and managing conversational AI and other agents. It orchestrates workflows and manages tool invocation for agents.
AI model layer: Agents use foundation models available through the Vertex AI Model Garden or the Gemini API.
MCP server and tool layer: MCP servers are deployed as containerized microservices on Cloud Run or managed by services like App Engine. These servers contain tools that interact with GCP services, such as BigQuery, Cloud Storage, and Cloud SQL. GCP offers pre-built MCP server implementations, such as the GCP MCP Toolbox, for integration with its databases.
Data and security layer:Vertex AI Vector Search and other data sources are encapsulated within the MCP server tools to provide contextual information. Access to these services is managed by Identity and Access Management (IAM) and secured through virtual private clouds. The MCP server can leverage Vertex AI Context Caching for improved performance.
Note that all the native technology is referred to in each respective cloud. Hence, some of the better technologies can be used in place of the tool mentioned here. This is more of a concept-level comparison rather than industry-wise implementation approaches.
We’ll go ahead and conclude this post here & continue discussing on a further deep dive in the next post.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
This is a continuation of my previous post, which can be found here.
Let us recap the key takaways from our previous post –
Agentic AI refers to autonomous systems that pursue goals with minimal supervision by planning, reasoning about next steps, utilizing tools, and maintaining context across sessions. Core capabilities include goal-directed autonomy, interaction with tools and environments (e.g., APIs, databases, devices), multi-step planning and reasoning under uncertainty, persistence, and choiceful decision-making.
Architecturally, three modules coordinate intelligent behavior: Sensing (perception pipelines that acquire multimodal data, extract salient patterns, and recognize entities/events); Observation/Deliberation (objective setting, strategy formation, and option evaluation relative to resources and constraints); and Action (execution via software interfaces, communications, or physical actuation to deliver outcomes). These functions are enabled by machine learning, deep learning, computer vision, natural language processing, planning/decision-making, uncertainty reasoning, and simulation/modeling.
At enterprise scale, open standards align autonomy with governance: the Model Context Protocol (MCP) grants an agent secure, principled access to enterprise tools and data (vertical integration), while Agent-to-Agent (A2A) enables specialized agents to coordinate, delegate, and exchange information (horizontal collaboration). Together, MCP and A2A help organizations transition from isolated pilots to scalable programs, delivering end-to-end automation, faster integration, enhanced security and auditability, vendor-neutral interoperability, and adaptive problem-solving that responds to real-time context.
Great! Let’s dive into this topic now.
Enterprise AI with MCP refers to the application of the Model Context Protocol (MCP), an open standard, to enable AI systems to securely and consistently access external enterprise data and applications.
The problem MCP solves in enterprise AI:
Before MCP, enterprise AI integration was characterized by a “many-to-many” or “N x M” problem. Companies had to build custom, fragile, and costly integrations between each AI model and every proprietary data source, which was not scalable. These limitations left AI agents with limited, outdated, or siloed information, restricting their potential impact. MCP addresses this by offering a standardized architecture for AI and data systems to communicate with each other.
How does MCP work?
The MCP framework uses a client-server architecture to enable communication between AI models and external tools and data sources.
MCP Host: The AI-powered application or environment, such as an AI-enhanced IDE or a generative AI chatbot like Anthropic’s Claude or OpenAI’s ChatGPT, where the user interacts.
MCP Client: A component within the host application that manages the connection to MCP servers.
MCP Server: A lightweight service that wraps around an external system (e.g., a CRM, database, or API) and exposes its capabilities to the AI client in a standardized format, typically using JSON-RPC 2.0.
An MCP server provides AI clients with three key resources:
Resources: Structured or unstructured data that an AI can access, such as files, documents, or database records.
Tools: The functionality to perform specific actions within an external system, like running a database query or sending an email.
Prompts: Pre-defined text templates or workflows to help guide the AI’s actions.
Benefits of MCP for enterprise AI:
Standardized integration: Developers can build integrations against a single, open standard, which dramatically reduces the complexity and time required to deploy and scale AI initiatives.
Enhanced security and governance: MCP incorporates native support for security and compliance measures. It provides permission models, access control, and auditing capabilities to ensure AI systems only access data and tools within specified boundaries.
Real-time contextual awareness: By connecting AI agents to live enterprise data sources, MCP ensures they have access to the most current and relevant information, which reduces hallucinations and improves the accuracy of AI outputs.
Greater interoperability: MCP is model-agnostic & can be used with a variety of AI models (e.g., Anthropic’s Claude or OpenAI’s models) and across different cloud environments. This approach helps enterprises avoid vendor lock-in.
Accelerated development: The “build once, integrate everywhere” approach enables internal teams to focus on innovation instead of writing custom connectors for every system.
Flow of activities:
Let us understand one sample case & the flow of activities.
A customer support agent uses an AI assistant to get information about a customer’s recent orders. The AI assistant utilizes an MCP-compliant client to communicate with an MCP server, which is connected to the company’s PostgreSQL database.
The interaction flow:
1. User request: The support agent asks the AI assistant, “What was the most recent order placed by Priyanka Chopra Jonas?”
2. AI model processes intent: The AI assistant, running on an MCP host, analyzes the natural language query. It recognizes that to answer this question, it needs to perform a database query. It then identifies the appropriate tool from the MCP server’s capabilities.
3. Client initiates tool call: The AI assistant’s MCP client sends a JSON-RPC request to the MCP server connected to the PostgreSQL database. The request specifies the tool to be used, such as get_customer_orders, and includes the necessary parameters:
5. Database returns data: The PostgreSQL database executes the query and returns the requested data to the MCP server.
6. Server formats the response: The MCP server receives the raw database output and formats it into a standardized JSON response that the MCP client can understand.
7. Client returns data to the model: The MCP client receives the JSON response and passes it back to the AI assistant’s language model.
8. AI model generates final response: The language model incorporates this real-time data into its response and presents it to the user in a natural, conversational format.
“Priyanka Chopra Jonas’s most recent order was placed on August 25, 2025, with an order ID of 98765, for a total of $11025.50.”
What are the performance implications of using MCP for database access?
Using the Model Context Protocol (MCP) for database access introduces a layer of abstraction that affects performance in several ways. While it adds some latency and processing overhead, strategic implementation can mitigate these effects. For AI applications, the benefits often outweigh the costs, particularly in terms of improved accuracy, security, and scalability.
Sources of performance implications::
Added latency and processing overhead:
The MCP architecture introduces extra communication steps between the AI agent and the database, each adding a small amount of latency.
RPC overhead: The JSON-RPC call from the AI’s client to the MCP server adds a small processing and network delay. This is an out-of-process request, as opposed to a simple local function call.
JSON serialization: Request and response data must be serialized and deserialized into JSON format, which requires processing time.
Network transit: For remote MCP servers, the data must travel over the network, adding latency. However, for a local or on-premise setup, this is minimal. The physical location of the MCP server relative to the AI model and the database is a significant factor.
Scalability and resource consumption:
The performance impact scales with the complexity and volume of the AI agent’s interactions.
High request volume: A single AI agent working on a complex task might issue dozens of parallel database queries. In high-traffic scenarios, managing numerous simultaneous connections can strain system resources and require robust infrastructure.
Excessive data retrieval: A significant performance risk is an AI agent retrieving a massive dataset in a single query. This process can consume a large number of tokens, fill the AI’s context window, and cause bottlenecks at the database and client levels.
Context window usage: Tool definitions and the results of tool calls consume space in the AI’s context window. If a large number of tools are in use, this can limit the AI’s “working memory,” resulting in slower and less effective reasoning.
Optimizations for high performance::
Caching:
Caching is a crucial strategy for mitigating the performance overhead of MCP.
In-memory caching: The MCP server can cache results from frequent or expensive database queries in memory (e.g., using Redis or Memcached). This approach enables repeat requests to be served almost instantly without requiring a database hit.
Semantic caching: Advanced techniques can cache the results of previous queries and serve them for semantically similar future requests, reducing token consumption and improving speed for conversational applications.
Efficient queries and resource management:
Designing the MCP server and its database interactions for efficiency is critical.
Optimized SQL: The MCP server should generate optimized SQL queries. Database indexes should be utilized effectively to expedite lookups and minimize load.
Pagination and filtering: To prevent a single query from overwhelming the system, the MCP server should implement pagination. The AI agent can be prompted to use filtering parameters to retrieve only the necessary data.
Connection pooling: This technique reuses existing database connections instead of opening a new one for each request, thereby reducing latency and database load.
Load balancing and scaling:
For large-scale enterprise deployments, scaling is essential for maintaining performance.
Multiple servers: The workload can be distributed across various MCP servers. One server could handle read requests, and another could handle writes.
Load balancing: A reverse proxy or other load-balancing solution can distribute incoming traffic across MCP server instances. Autoscaling can dynamically add or remove servers in response to demand.
The performance trade-off in perspective:
For AI-driven tasks, a slight increase in latency for database access is often a worthwhile trade-off for significant gains.
Improved accuracy: Accessing real-time, high-quality data through MCP leads to more accurate and relevant AI responses, reducing “hallucinations”.
Scalable ecosystem: The standardization of MCP reduces development overhead and allows for a more modular, scalable ecosystem, which saves significant engineering resources compared to building custom integrations.
Decoupled architecture: The MCP server decouples the AI model from the database, allowing each to be optimized and scaled independently.
We’ll go ahead and conclude this post here & continue discussing on a further deep dive in the next post.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
Today, we’re going to discuss creating a local LLM server and then utilizing it to execute various popular LLM models. We will club the local Apple GPUs together via a new framework that binds all the available Apple Silicon devices into one big LLM server. This enables people to run many large models, which was otherwise not possible due to the lack of GPUs.
This is certainly a new way; One can create virtual computation layers by adding nodes to the resource pool, increasing the computation capacity.
Why not witness a small demo to energize ourselves –
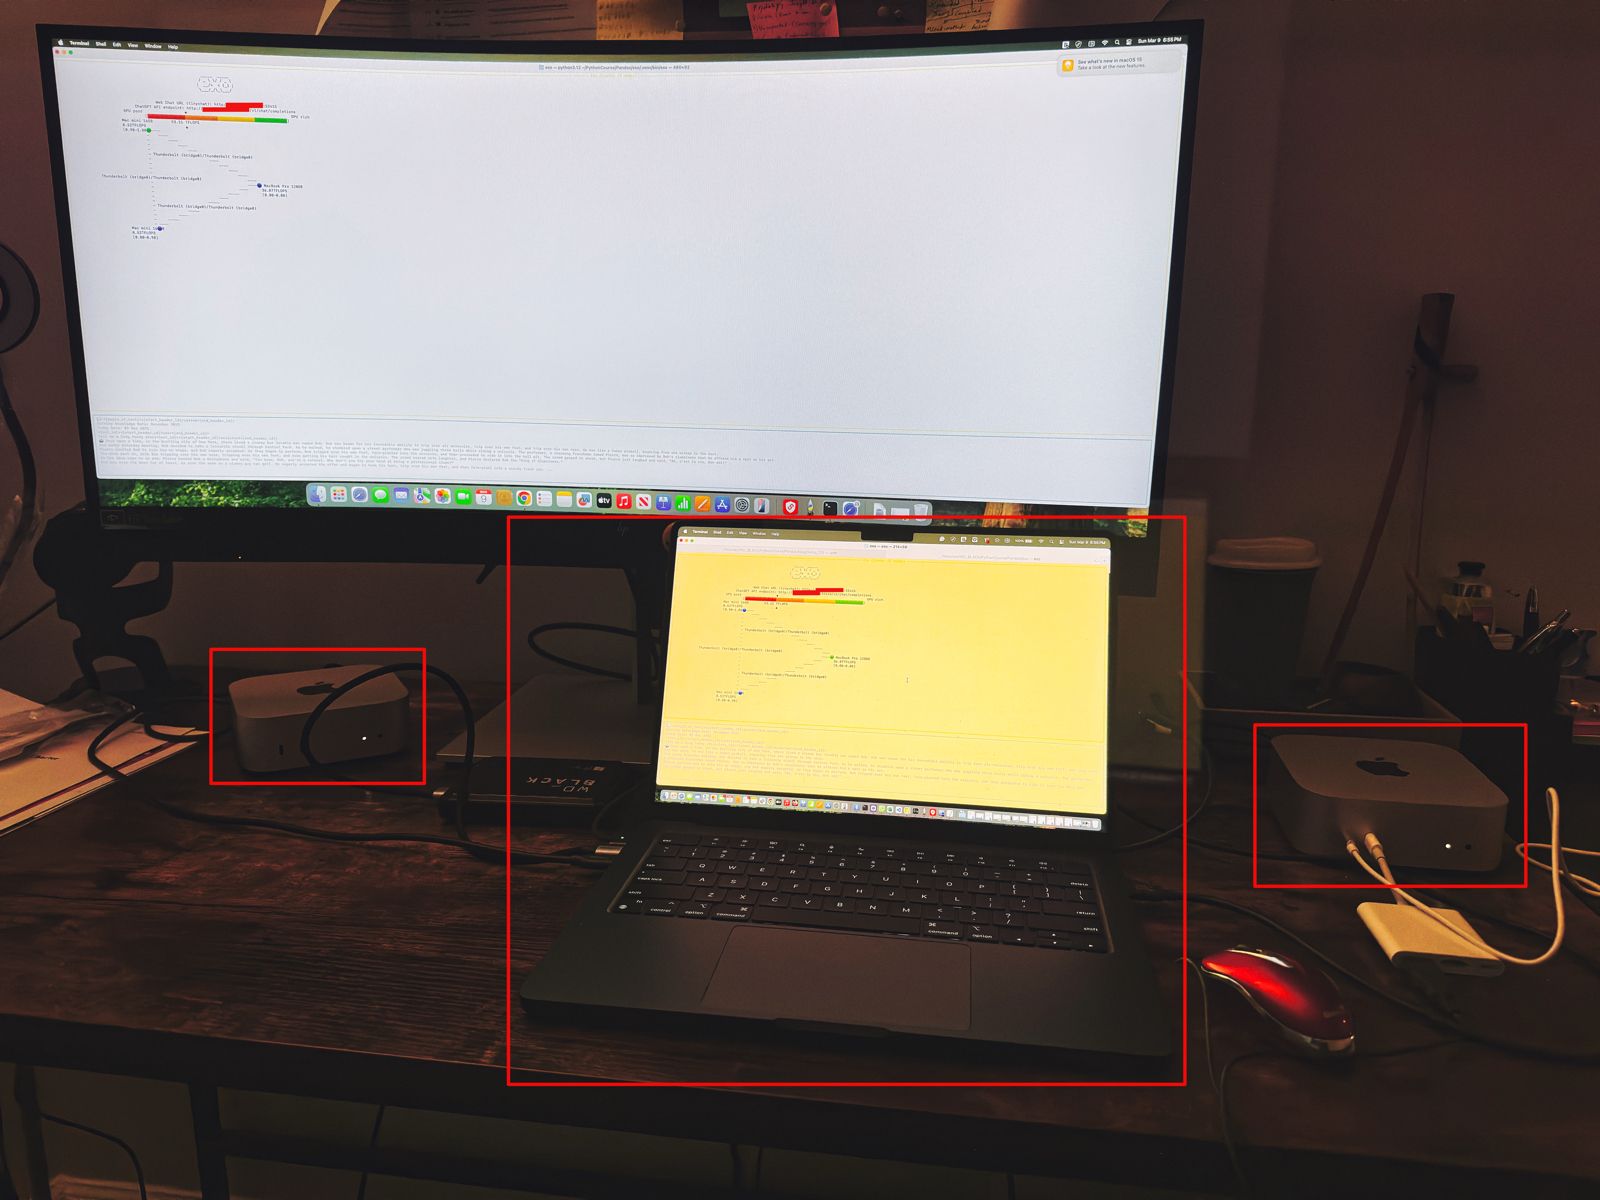
Let us understand the scenario. I’ve one Mac Book Pro M4 & 2 Mac Mini Pro M4 (Base models). So, I want to add them & expose them as a cluster as follows –
As you can see, I’ve connected my MacBook Pro with both the Mac Mini using high-speed thunderbolt cables for better data transmissions. And, I’ll be using an open-source framework called “Exo” to create it.
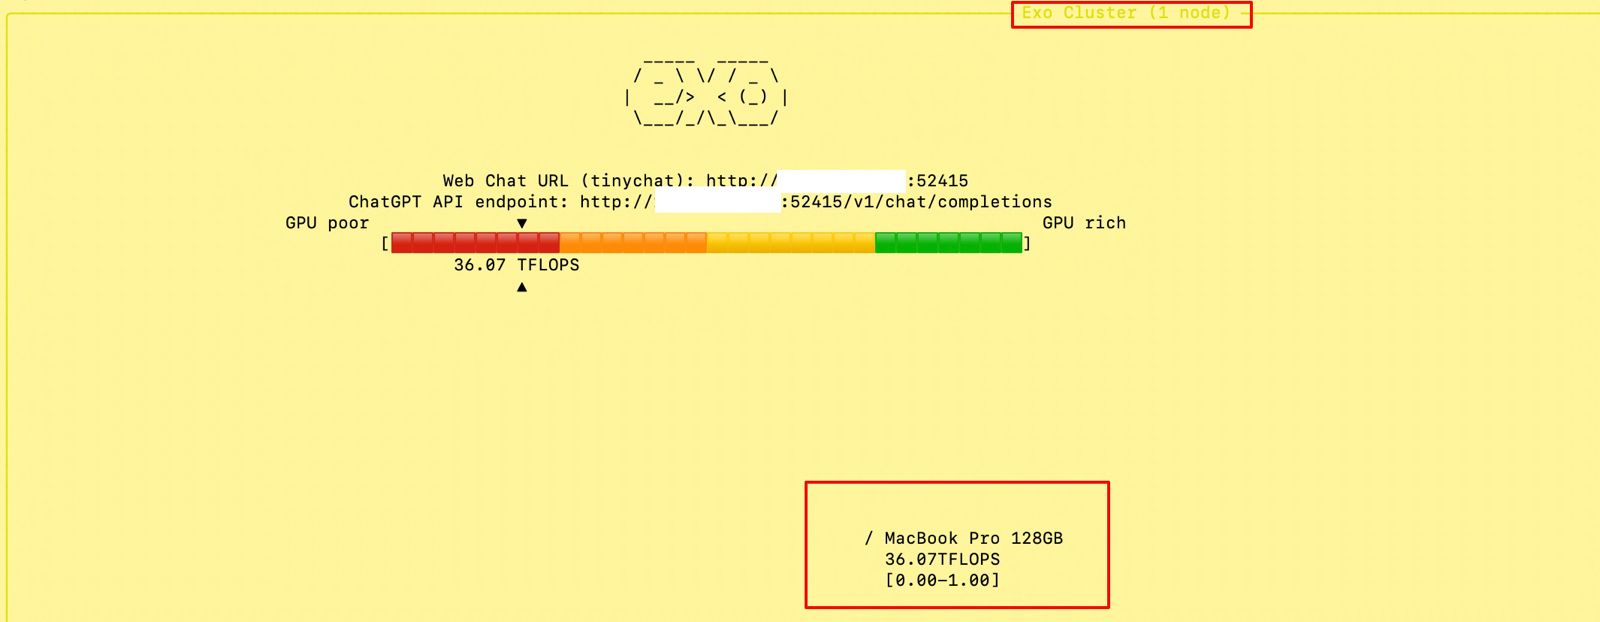
Also, you can see that my total computing capacity is 53.11 TFlops, which is slightly more than the last category.
What is Exo?
“Exo” is an open-source framework that helps you merge all your available devices into a large cluster of available resources. This extracts all the computing juice needed to handle complex tasks, including the big LLMs, which require very expensive GPU-based servers.
For more information on “Exo”, please refer to the following link.
In our previous diagram, we can see that the framework also offers endpoints.
One option is a local ChatGPT interface, where any question you ask will receive a response from models by combining all available computing power.
The other endpoint offers users a choice of any standard LLM API endpoint, which helps them integrate it into their solutions.
Let us see, how the devices are connected together –
How to establish the Cluster?
To proceed with this, you need to have at least Python 3.12, Anaconda or Miniconda & Xcode installed in all of your machines. Also, you need to install some Apple-specific MLX packages or libraries to get the best performance.
Depending on your choice, you need to use the following link to download Anaconda or Miniconda.
You can download the following link to download the Python 3.12. However, I’ve used Python 3.13 on some machines & some machines, I’ve used Python 3.12. And it worked without any problem.
Sometimes, after installing Anaconda or Miniconda, the environment may not implicitly be activated after successful installation. In that case, you may need to use the following commands in the terminal -> source ~/.bash_profile
To verify, whether the conda has been successfully installed & activated, you need to type the following command –
And, you need to perform the same process in other available devices as well.
Now, we’re ready to proceed with the final command –
(.venv) (exo1) satyaki_de@Satyakis-MacBook-Pro-Maxexo%exo/opt/anaconda3/envs/exo1/lib/python3.13/site-packages/google/protobuf/runtime_version.py:112: UserWarning:Protobufgencodeversion5.27.2isolderthantheruntimeversion5.28.1atnode_service.proto.Pleaseavoidchecked-inProtobufgencodethatcanbeobsolete.warnings.warn(NoneofPyTorch,TensorFlow>=2.0,orFlaxhavebeenfound.Modelswon't be available and only tokenizers, configuration and file/data utilities can be used.NoneofPyTorch,TensorFlow>=2.0,orFlaxhavebeenfound.Modelswon't be available and only tokenizers, configuration and file/data utilities can be used.Selectedinferenceengine: None__________/_ \ \//_ \ |__/>< (_) | \___/_/\_\___/Detectedsystem: AppleSiliconMacInferenceenginenameafterselection: mlxUsinginferenceengine: MLXDynamicShardInferenceEnginewithsharddownloader: SingletonShardDownloader[60771,54631,54661]Chatinterfacestarted:-http://127.0.0.1:52415-http://XXX.XXX.XX.XX:52415-http://XXX.XXX.XXX.XX:52415-http://XXX.XXX.XXX.XXX:52415ChatGPTAPIendpointservedat:-http://127.0.0.1:52415/v1/chat/completions-http://XXX.XXX.X.XX:52415/v1/chat/completions-http://XXX.XXX.XXX.XX:52415/v1/chat/completions-http://XXX.XXX.XXX.XXX:52415/v1/chat/completionshas_read=True,has_write=True╭────────────────────────────────────────────────────────────────────────────────────────────── ExoCluster (2nodes) ───────────────────────────────────────────────────────────────────────────────────────────────╮ReceivedexitsignalSIGTERM...Thankyouforusingexo.__________/_ \ \//_ \ |__/>< (_) | \___/_/\_\___/
Note that I’ve masked the IP addresses for security reasons.
Run Time:
At the beginning, if we trigger the main MacBook Pro Max, the “Exo” screen should looks like this –
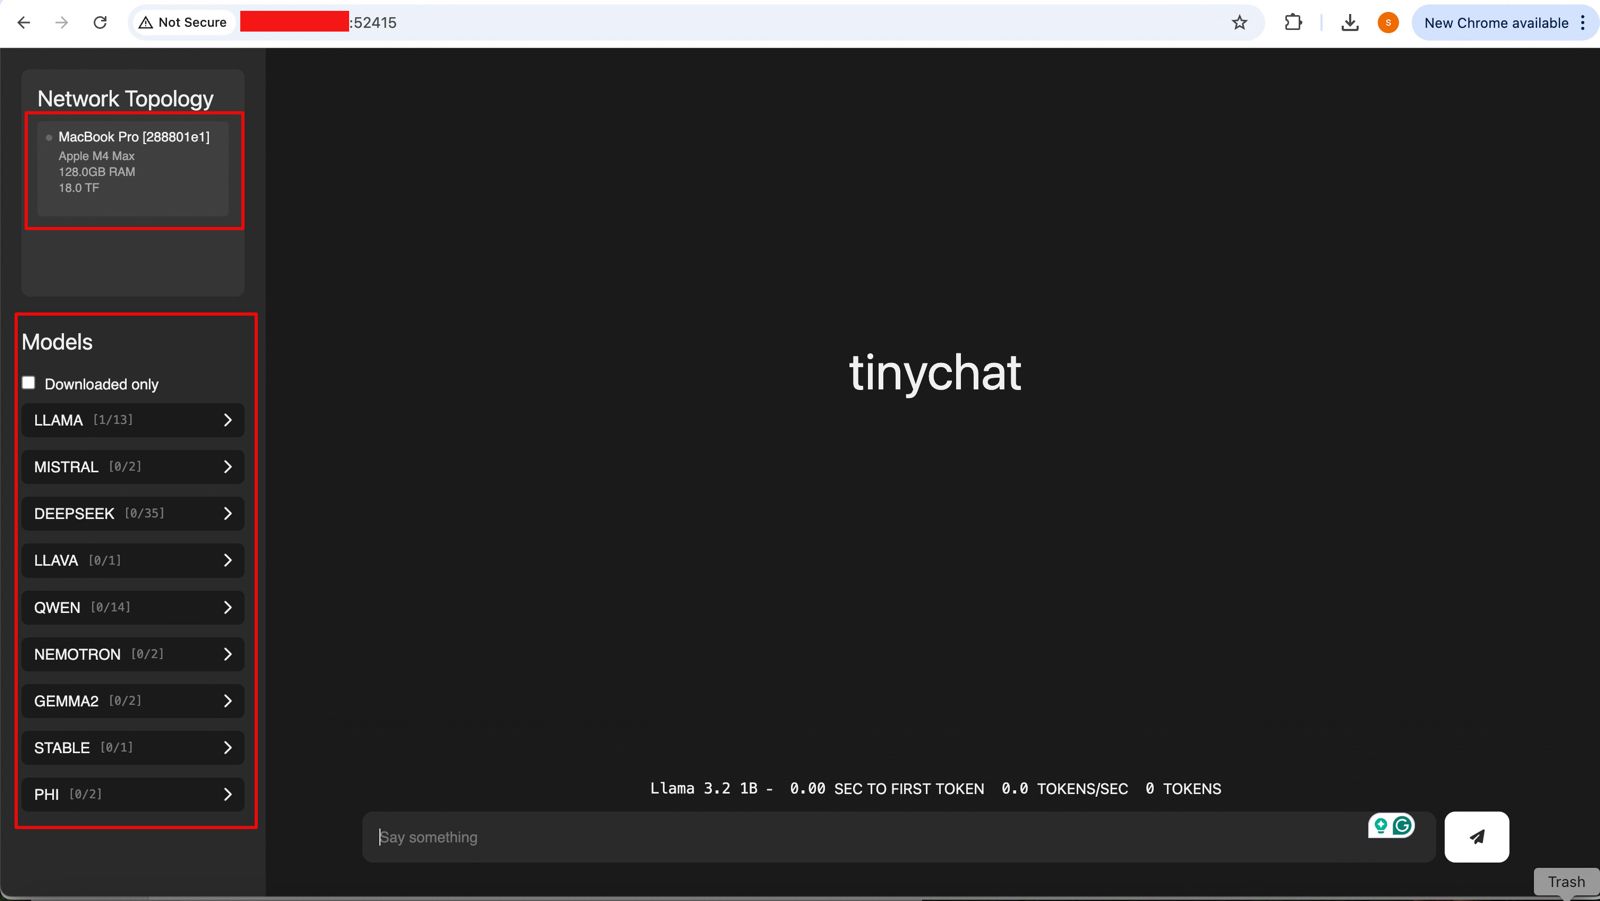
And if you open the URL, you will see the following ChatGPT-like interface –
Connecting without the Thunderbolt bridge with the relevant port or a hub may cause performance degradation. Hence, how you connect will play a major role in the success of this intention. However, this is certainly a great idea to proceed with.
So, we’ve done it.
We’ll cover the detailed performance testing, Optimized configurations & many other useful details in our next post.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
As we’re leaping more & more into the field of Generative AI, one of the frequent questions or challenges people are getting more & more is the performance & other evaluation factors. These factors will eventually bring the fruit of this technology; otherwise, you will end up in technical debt.
This post will discuss the key snippets of the monitoring app based on the Python-based AI app. But before that, let us first view the demo.
Isn’t it exciting?
Let us deep dive into it. But, here is the flow this solution will follow.
So, the current application will invoke the industry bigshots and some relatively unknown or new LLMs.
In this case, we’ll evaluate Anthropic, Open AI, DeepSeek, and Bharat GPT’s various models. However, Bharat GPT is open source, so we’ll use the Huggingface library and execute it locally against my MacBook Pro M4 Max.
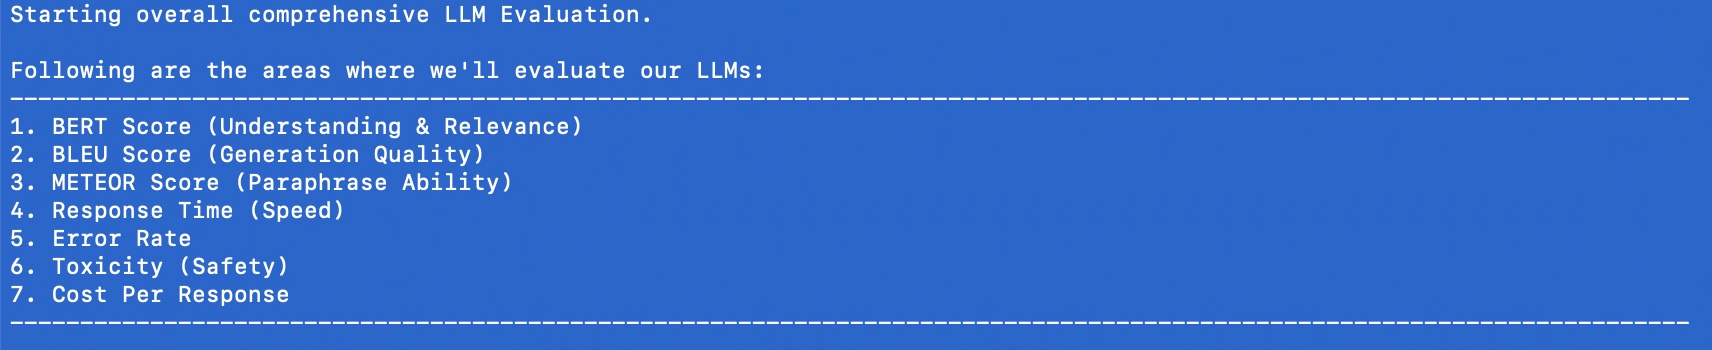
The following are the KPIs we’re going to evaluate:
Package Installation:
Here are the lists of dependant python packages that is require to run this application –
clsComprehensiveLLMEvaluator.py (This is the main Python class that will apply all the logic to collect stats involving important KPIs. Note that we’re only going to discuss a few important functions here.)
reference: The correct or expected version of the text.
Calculating BERTScore:
Converts the generated and reference texts into numerical embeddings (mathematical representations) using a pre-trained model (self.sentence_model.encode).
Measures the similarity between the two embeddings using cosine similarity. This gives the bert_score, which ranges from -1 (completely different) to 1 (very similar).
Calculating BLEU Score:
Breaks the generated and reference texts into individual words (tokens) using word_tokenize.
Converts both texts to lowercase for consistent comparison.
Calculates the BLEU Score (sentence_bleu), which checks how many words or phrases in the generated text overlap with the reference. BLEU values range from 0 (no match) to 1 (perfect match).
Calculating METEOR Score:
Also uses the tokenized versions of generated and reference texts.
Calculates the METEOR Score (meteor_score), which considers exact matches, synonyms, and word order. Scores range from 0 (no match) to 1 (perfect match).
Returning the Results:
Combines the three scores into a dictionary with the keys 'bert_score', 'bleu_score', and 'meteor_score'.
Similarly, other functions are developed.
defrun_comprehensive_evaluation(self,evaluation_data: List[Dict]) ->pd.DataFrame:"""Run comprehensive evaluation on all metrics"""results= []foritemin evaluation_data:prompt=item['prompt']reference=item['reference']task_criteria=item.get('task_criteria',{})formodel_nameinself.model_configs.keys(): # Getmultipleresponsestoevaluatereliabilityresponses= [self.get_model_response(model_name,prompt)for_inrange(3) # Get3responsesforreliabilitytesting ] # Usethebestresponseforotherevaluationsbest_response=max(responses,key=lambdax: len(x.content) ifnotx.errorelse0)ifbest_response.error:logging.error(f"Error in model {model_name}: {best_response.error}")continue # Gatherallmetricsmetrics={'model':model_name,'prompt':prompt,'response':best_response.content, **self.evaluate_text_quality(best_response.content, reference), **self.evaluate_factual_accuracy(best_response.content, reference), **self.evaluate_task_performance(best_response.content, task_criteria), **self.evaluate_technical_performance(best_response), **self.evaluate_reliability(responses), **self.evaluate_safety(best_response.content)} # Addbusinessimpactmetricsusingtask performancemetrics.update(self.evaluate_business_impact(best_response,metrics['task_completion'] ))results.append(metrics)returnpd.DataFrame(results)
Input:
evaluation_data: A list of test cases, where each case is a dictionary containing:
prompt: The question or input to the AI model.
reference: The ideal or expected answer.
task_criteria (optional): Additional rules or requirements for the task.
Initialize Results:
An empty list results is created to store the evaluation metrics for each model and test case.
Iterate Through Test Cases:
For each item in the evaluation_data:
Extract the prompt, reference, and task_criteria.
Evaluate Each Model:
Loop through all available AI models (self.model_configs.keys()).
Generate three responses for each model to test reliability.
Select the Best Response:
Out of the three responses, pick the one with the most content (best_response), ignoring responses with errors.
Handle Errors:
If a response has an error, log the issue and skip further evaluation for that model.
Evaluate Metrics:
Using the best_response, calculate a variety of metrics, including:
Text Quality: How similar the response is to the reference.
Factual Accuracy: Whether the response is factually correct.
Task Performance: How well it meets task-specific criteria.
Technical Performance: Evaluate time, memory, or other system-related metrics.
Reliability: Check consistency across multiple responses.
Safety: Ensure the response is safe and appropriate.
Evaluate Business Impact:
Add metrics for business impact (e.g., how well the task was completed, using task_completion as a key factor).
Store Results:
Add the calculated metrics for this model and prompt to the results list.
Return Results as a DataFrame:
Convert the results list into a structured table (a pandas DataFrame) for easy analysis and visualization.
Great! So, now, we’ve explained the code.
Observation from the result:
Let us understand the final outcome of this run & what we can conclude from that.
BERT Score (Semantic Understanding):
GPT4 leads slightly at 0.8322 (83.22%)
Bharat-GPT close second at 0.8118 (81.18%)
Claude-3 at 0.8019 (80.19%)
DeepSeek-Chat at 0.7819 (78.19%) Think of this like a “comprehension score” – how well the models understand the context. All models show strong understanding, with only a 5% difference between best and worst.
BLEU Score (Word-for-Word Accuracy):
Bharat-GPT leads at 0.0567 (5.67%)
Claude-3 at 0.0344 (3.44%)
GPT4 at 0.0306 (3.06%)
DeepSeek-Chat lowest at 0.0189 (1.89%) These low scores suggest models use different wording than references, which isn’t necessarily bad.
METEOR Score (Meaning Preservation):
Bharat-GPT leads at 0.4684 (46.84%)
Claude-3 close second at 0.4507 (45.07%)
GPT4 at 0.2960 (29.60%)
DeepSeek-Chat at 0.2652 (26.52%) This shows how well models maintain meaning while using different words.
Response Time (Speed):
Claude-3 fastest: 4.40 seconds
Bharat-GPT: 6.35 seconds
GPT4: 6.43 seconds
DeepSeek-Chat slowest: 8.52 seconds
Safety and Reliability:
Error Rate: Perfect 0.0 for all models
Toxicity: All very safe (below 0.15%)
Claude-3 safest at 0.0007GPT4 at 0.0008Bharat-GPT at 0.0012
DeepSeek-Chat at 0.0014
Cost Efficiency:
Claude-3 most economical: $0.0019 per response
Bharat-GPT close: $0.0021
GPT4: $0.0038
DeepSeek-Chat highest: $0.0050
Key Takeaways by Model:
Claude-3: ✓ Fastest responses ✓ Most cost-effective ✓ Excellent meaning preservation ✓ Lowest toxicity
Bharat-GPT: ✓ Best BLEU and METEOR scores ✓ Strong semantic understanding ✓ Cost-effective ✗ Moderate response time
GPT4: ✓ Best semantic understanding ✓ Good safety metrics ✗ Higher cost ✗ Moderate response time
These statistics provide reliable comparative data but should be part of a broader decision-making process that includes your specific needs, budget, and use cases.
For the Bharat GPT model, we’ve tested this locally on my MacBook Pro 4 Max. And, the configuration is as follows –
I’ve tried the API version locally, & it provided a similar performance against the stats that we received by running locally. Unfortunately, they haven’t made the API version public yet.
So, apart from the Anthropic & Open AI, I’ll watch this new LLM (Bharat GPT) for overall stats in the coming days.
So, we’ve done it.
You can find the detailed code at the GitHub link.
I’ll bring some more exciting topics in the coming days from the Python verse.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
Starts by clearing GPU memory and running garbage collection.
Loads the init_image, resizes it to 1024×1024 pixels, and converts it to RGB format.
Iteratively applies the pipeline to transform the image:
Uses the prompt and specified parameters like strength, guidance_scale, and num_inference_steps.
Stores the resulting frames in a list.
Interpolates between consecutive frames to create smooth transitions:
Uses linear blending for smooth animation across a specified duration and frame rate (24 fps for 10 segments).
Returns the final list of generated frames or an empty list if an error occurs.
Always clears memory after execution.
3. genVideo(prompt, inputImage, targetVideo, fps)
This is the main function for creating a video from an image and text prompt:
Logs the start of the animation generation process.
Calls generate_frames() with the given pipeline, inputImage, and prompt to create frames.
Saves the generated frames as a video using the imageio library, setting the specified frame rate (fps).
Logs a success message and returns 0 if the process is successful.
On error, logs the issue and returns 1.
Now, let us understand the performance. But, before that let us explore the device on which we’ve performed these stress test that involves GPU & CPUs as well.
And, here is the performance stats –
From the above snapshot, we can clearly communicate that the GPU is 100% utilized. However, the CPU has shown a significant % of availability.
As you can see, the first pass converts the input prompt to intermediate images within 1 min 30 sec. However, the second pass constitutes multiple hops (11 hops) on an avg 22 seconds. Overall, the application will finish in 5 minutes 36 seconds for a 10-second video clip.
So, we’ve done it.
You can find the detailed code at the GitHub link.
I’ll bring some more exciting topics in the coming days from the Python verse.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.







You must be logged in to post a comment.