Anything not like your other LLM Stack with Custom Wrapper Layer & Multi-nodes – Part 4

Today, I’ll be sharing the fourth & final installment of the Colibri LLM framework with a bit of custom twists to get a stunning result at the end of this post.

In case, if you want read the previous posts from this series, then do visit the following links –

ANYTHING NOT LIKE YOUR OTHER LLM STACK – PART 1

ANYTHING NOT LIKE YOUR OTHER LLM STACK – PART 2

ANYTHING NOT LIKE YOUR OTHER LLM STACK – PART 3

The primary goal of this post is to optimize overall LLM response performance by finding the right balance between hardware capabilities and the optimization techniques offered by the Colibri framework. The objective is to achieve the best possible performance when running large language models (LLMs) locally, without relying on massive AI infrastructure or expensive cloud-based premium models.

But, before that let us watch the demo first.

Great! Based on the tests conducted across the use cases shown above, we observed significant differences in the total time required to generate a complete LLM response. The following summarizes the performance of each configuration using the same prompt and a response length of approximately 400 words:

  • Option 1 – Direct Execution Using the Colibri Framework (Command Line): Running the Colibri framework directly from the command line took between 16 and 22 minutes to generate the complete response.
  • Option 2 – Colibri Framework With a Wrapper Layer (Custom Web UI): Using a custom web interface with a wrapper layer built around the Colibri framework reduced the total response time to under 32 minutes for the same prompt.
  • Option 3 – Colibri Framework With a Wrapper Layer and Multi-Node Architecture (Custom Web UI):Integrating the wrapper layer with the Colibri framework in a multi-node configuration further reduced the total response time to 3 – 4 minutes or less, representing a substantial performance improvement over the previous configurations.

Key Takeaway: The multi-node configuration delivered the most significant performance improvement, reducing response generation time from over 16 to 22 minutes to 3 – 4 minutes or less. This demonstrates the potential of combining hardware resources with software optimization to make local LLM inference considerably faster, without relying on expensive cloud-based infrastructure.


Now, let’s explore how we achieved what initially seemed impossible. Before diving into the technical details, it is important to understand the core principles behind this solution. The key lies in a combination of software and hardware optimizations, along with efficient data transfer and communication between components. Each of these elements plays a critical role in achieving the performance improvements demonstrated above.

For this setup, I used a Satechi CubeDock Thunderbolt 5 docking station equipped with a Samsung 9100 PRO 2 TB NVMe SSD as an external high-speed storage solution, rather than upgrading the internal storage of my MacBook Pro M4 Max. This external SSD stores two different LLMs configured to run using the Colibri framework.

Since the MacBook Pro can directly access this high-speed SSD, I used SMB (Server Message Block) network sharing to make the model files accessible to both Mac minis. Each Mac mini mounts the shared storage over the network, allowing all three machines to access the centrally stored models without maintaining separate copies on their internal SSDs.

This approach helps overcome the individual storage limitations of the Mac minis while enabling a more flexible, multi-node architecture. However, shared storage does not increase the available RAM on each machine; memory utilization must still be managed according to each node’s hardware capabilities.

An important aspect of this architecture is that each LLM and computing node has a specific responsibility, while the MacBook Pro M4 Max serves as the primary or master node, coordinating the overall workflow and distributing tasks across the available resources.

Now, I’ll share the hardware details, which I bought it from Amazon & Quill (This is not a paid promotion for any of the products).

I’ve been using my Mac minis and MacBook Pro for quite some time, so I decided to put these existing machines to better use by combining them into a multi-node computing cluster.

You can adopt a similar approach using your existing computers, provided they meet the hardware and software requirements of your setup. The machines do not necessarily need identical specifications, as different nodes can contribute based on their individual capabilities.

The key takeaway? Don’t be too quick to discard your older computers! With the right configuration and optimization, they can still serve a valuable purpose in modern AI workloads. Unless you’re upgrading or trading them in as part of a worthwhile deal, consider how you might repurpose them. You never know when those additional computing resources might come in handy.


In this section, I’ll explain how each computing node can run a specific LLM based on its available memory and hardware capabilities, with each model assigned a particular task. By distributing these tasks across multiple nodes and executing them in parallel, we can significantly reduce the overall processing time and improve the efficiency of the entire system.

The goal is to demonstrate how this multi-node architecture can deliver competitive LLM response performance, potentially approaching that of commercial, cloud-based LLM services for certain workloads, while making the most of existing hardware resources and minimizing infrastructure costs.
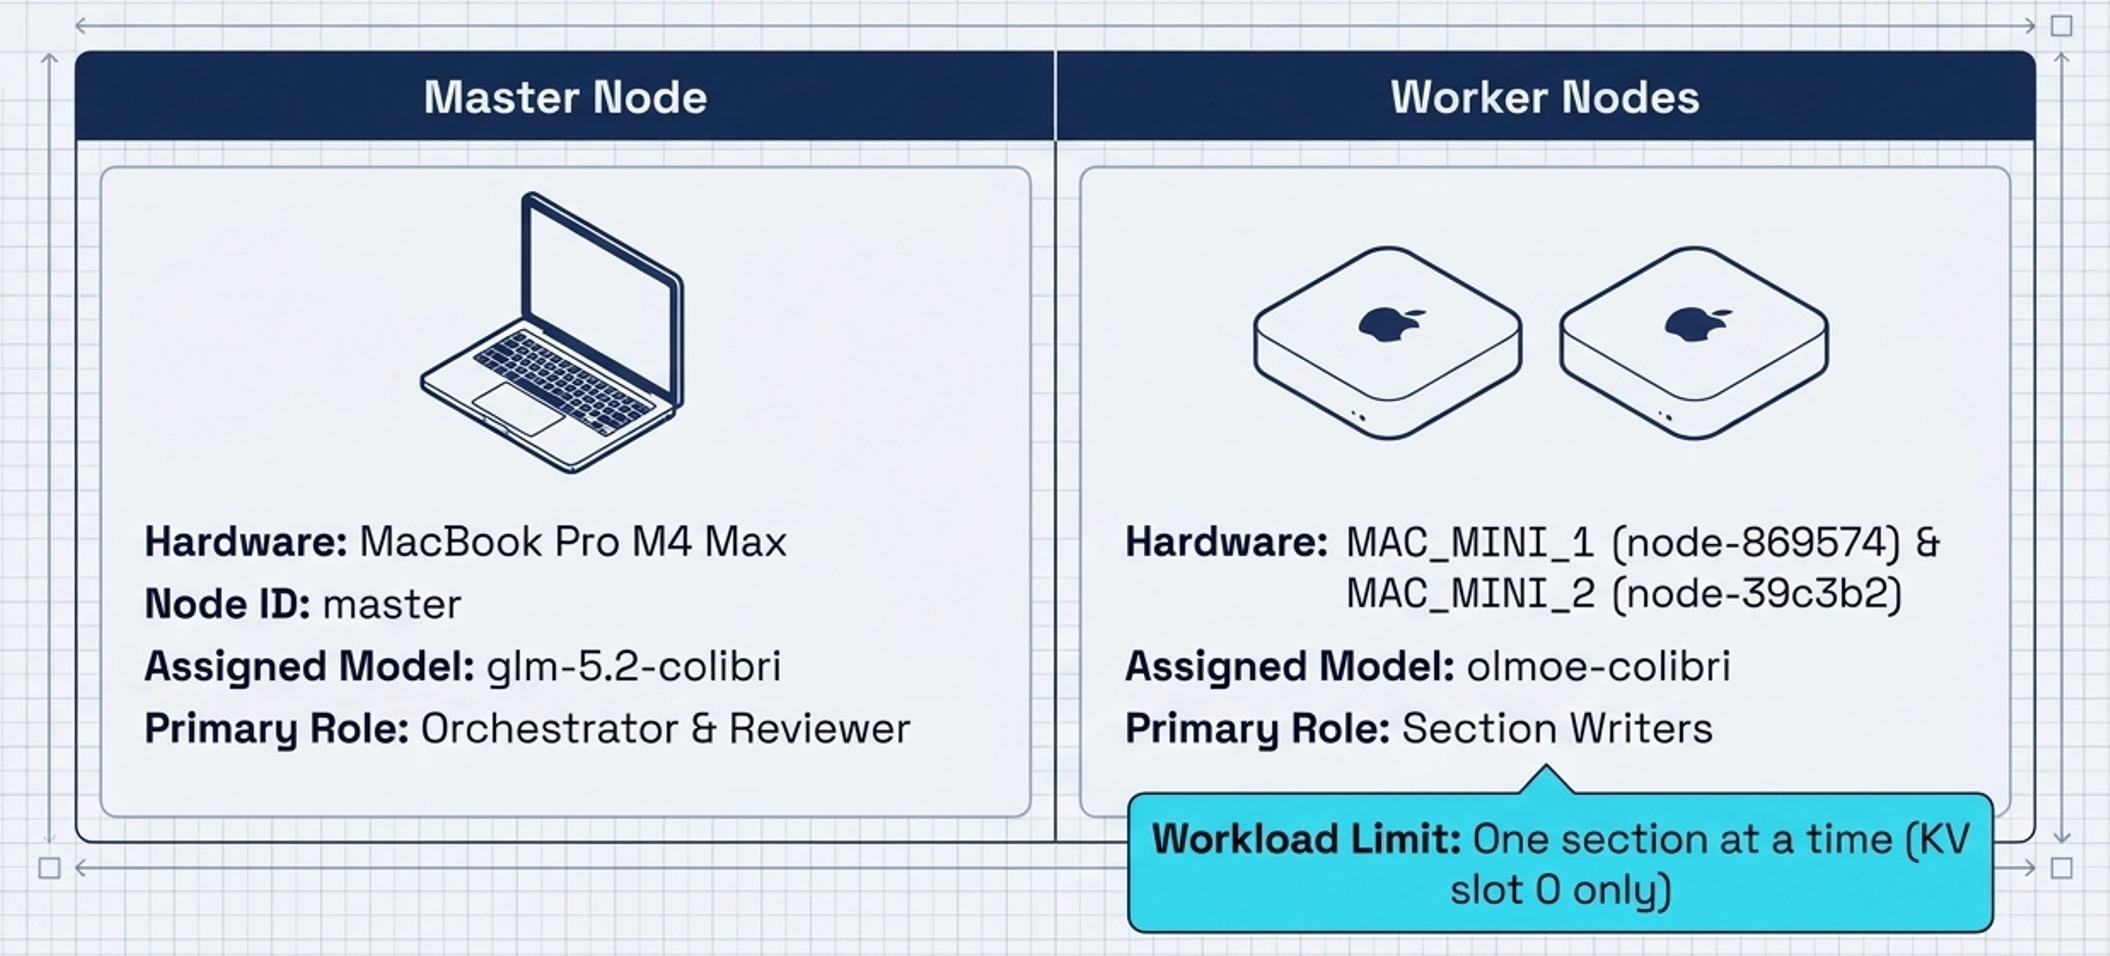
As you can see that, the Mini’s will share the caches, whereas the Master node won’t as they belongs to complete two different kinds of model families.
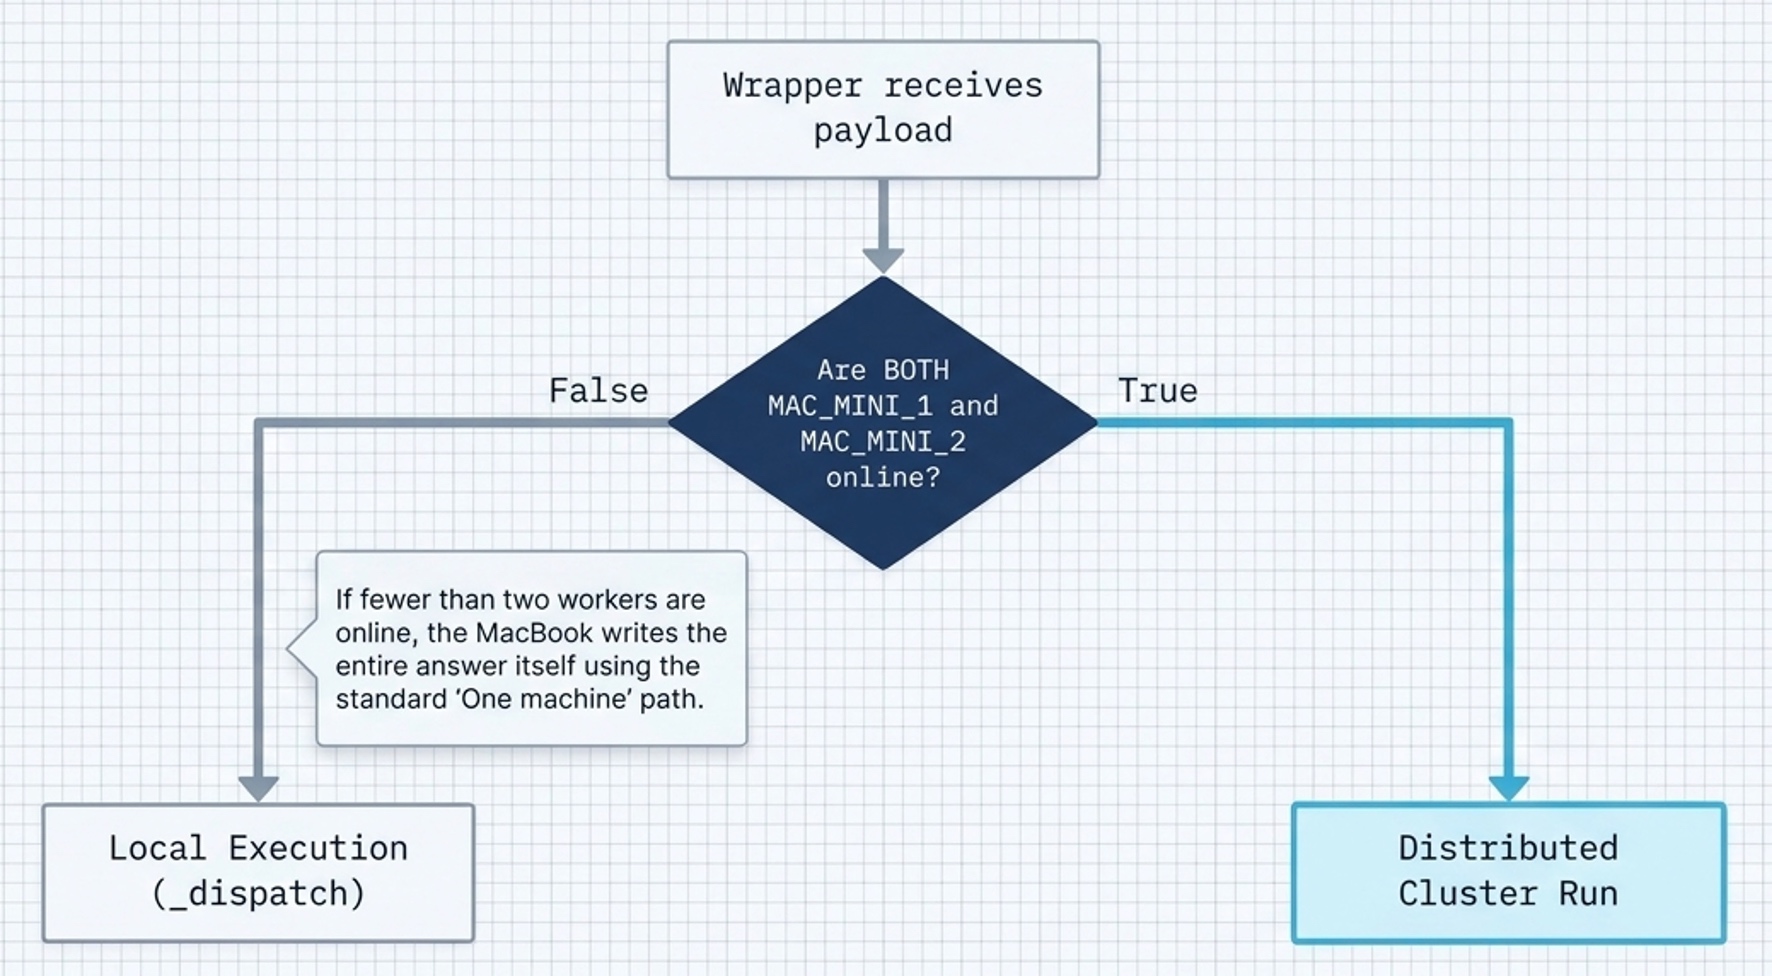
Until or unless the Mac Mini’s are available the entire process will take place in the master node only.

Now, the sequence of activities that happened as follows ->

As soon as you submit the prompt the following sequence of activities will take place –

  • The master node (MacBook Pro M4 Max) first analyzes the submitted request and breaks it down into high-level sections based on the topic and its context.
    • Task Distribution: Once the sections are defined, the master node shares each section’s specific context and instructions with the assigned Mac mini node.
    • Parallel Processing: Each Mac mini processes one request at a time. With two Mac minis operating simultaneously, the system can handle up to two concurrent requests, allowing both nodes to independently generate relevant content for their assigned sections.
    • Task Queue and Monitoring: While both nodes are busy processing their current assignments, the remaining sections stay in a queue. The Web UI displays the status of each section, making it easy to identify which tasks are being processed and which are waiting for an available node.
    • Automatic Task Execution: As soon as a Mac mini completes its assigned section, it automatically picks up the next task from its queue. Using the context and instructions provided by the master node, it generates the content for that section. This process continues until all assigned sections are completed.
  • By distributing independent tasks across multiple computing nodes, this architecture enables parallel content generation, efficient resource utilization, and reduced overall response time compared with processing every section sequentially on a single node.
  • As soon as a child node (Mac mini) completes its assigned section, the master node (MacBook Pro M4 Max) begins the first phase of content review. During this phase, the master node checks for incomplete sentences or unfinished paragraphs. If any are identified, it analyzes the surrounding context and attempts to complete them while preserving the original meaning and flow.
    • Phase 1 – Section-Level Review: The master node reviews each completed section individually, identifying and correcting incomplete sentences or paragraphs to ensure the content is clear, coherent, and contextually relevant.
    • Phase 2 – Final Content Review and Refinement: Once all child nodes have completed their assigned sections and the first review phase is finished, the master node performs a second review of the entire response. During this phase, it identifies and removes duplicate statements, repetitive phrases, and redundant information across sections. It may also add important details or missing points that the child nodes did not include in their initial responses.
  • This two-phase review process helps improve the consistency, completeness, and overall quality of the final response while taking advantage of parallel content generation across multiple computing nodes.

The below image will explain the above-points clearly –
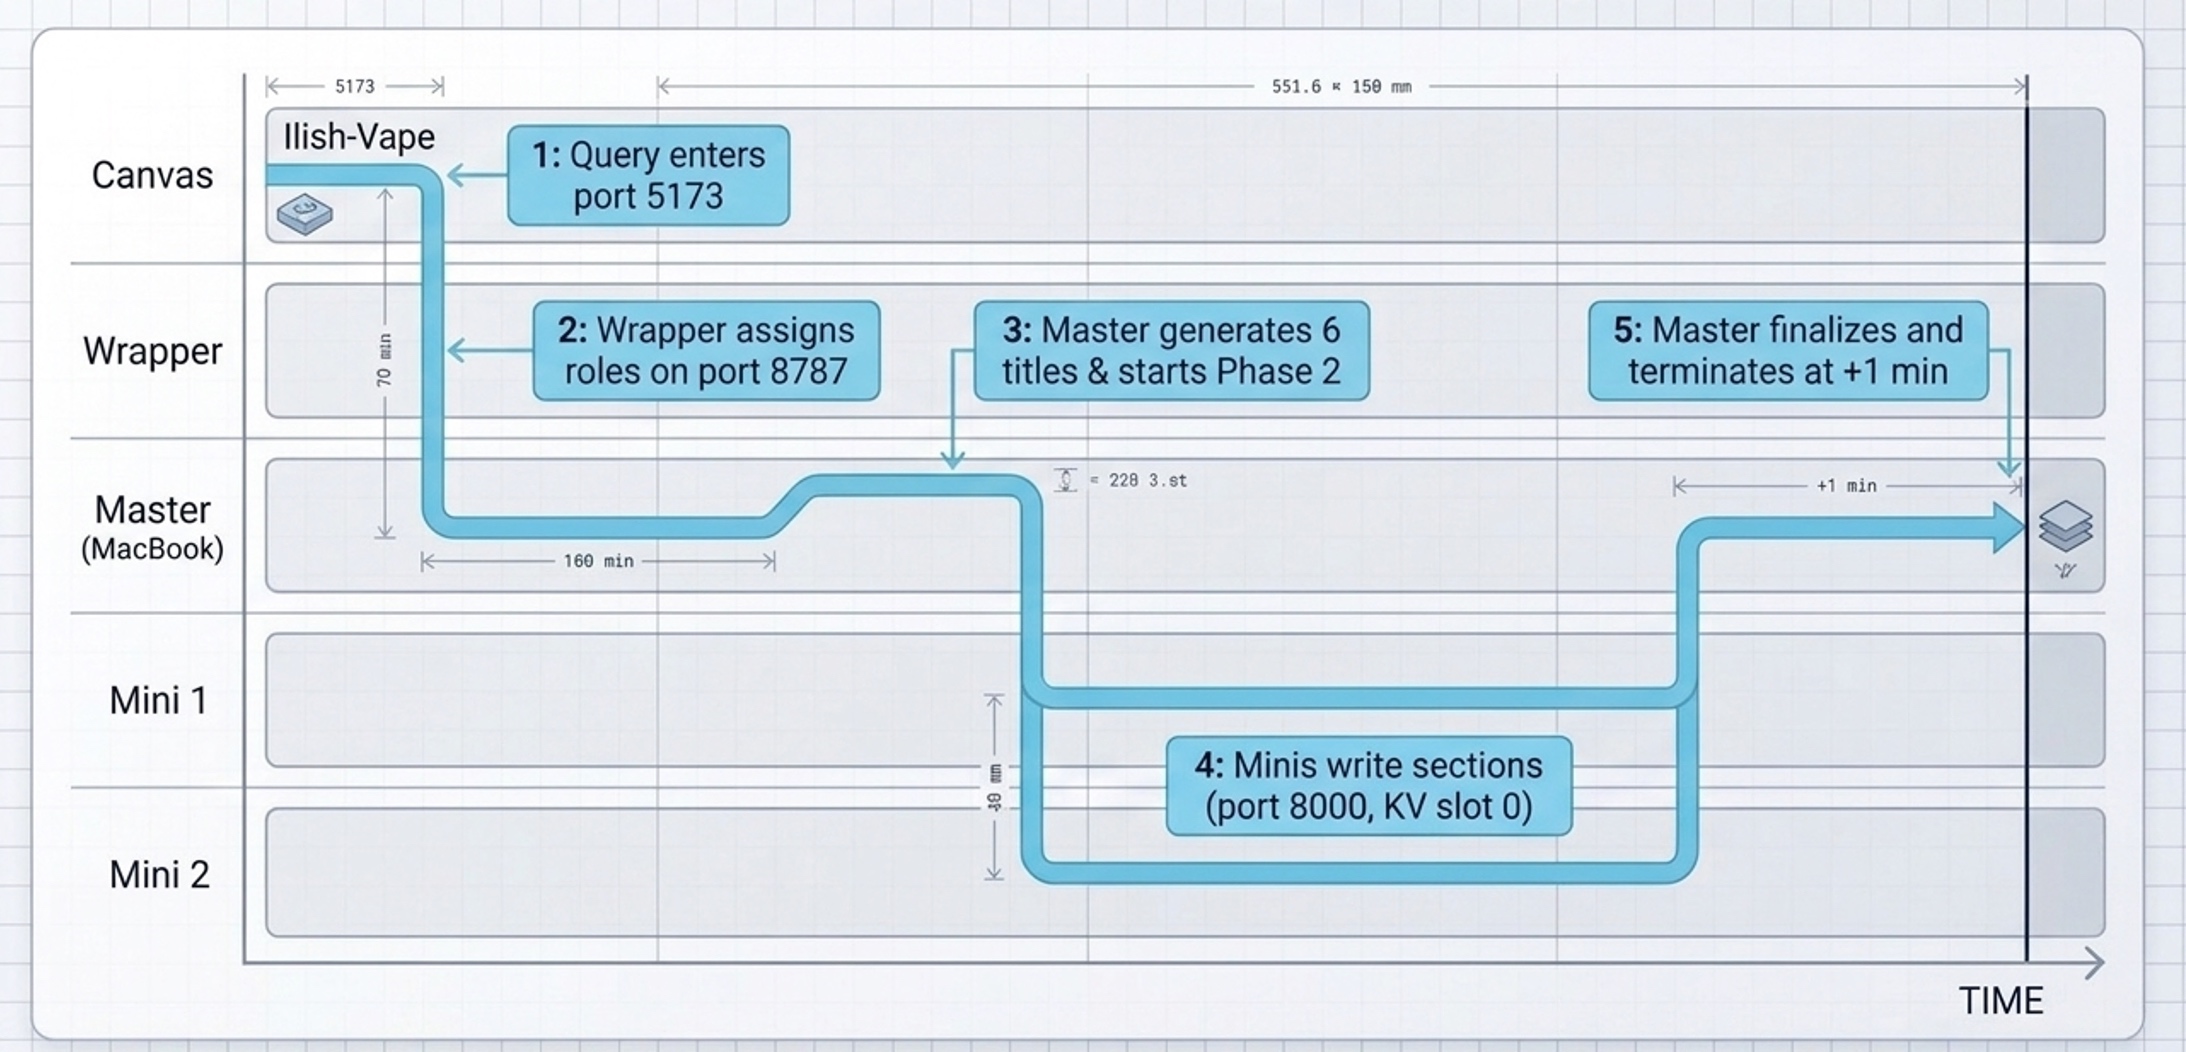
In the above, we’re showing the example of the following prompt -> “How to prepare Ilish-vape food in Bengali-Indian style?”

Hope this will give you clarity that you are looking for.

All the nodes will be connected by Thunderbolt 5 to get faster network communication.

And, here is the way all the nodes are connected ->

Satechi CubeDock (Samsung 2 TB SSD) -> MacBook Pro -> Mac Mini 1
-> Mac Mini 2

So, both the Mini’s are also diretly connected with the MacBook Pro as well.

Verify SMB is running on the MacBook Pro

networksetup -getinfo "Thunderbolt Bridge"

Verify the IP address & then execute the following –

sudo lsof -nP -iTCP:445 -sTCP:LISTEN

This checks whether the SMB service is listening for connections.

sudo launchctl print system/com.apple.smbd

Now, test the following in the Mini’s –

Configuring the SMB Drive:

nc -vz -G 5 192.168.100.X 445

X – represent your actual IP address (All the IP Address mentioned here are dummy in nature).

Then test the IP Address –

ping -c 20 192.168.100.Y

Remember, here the IP Address that is mentioned is the MacBook Pro’s IP Address i.e. Master node.

Mount the SSD from Finder

Using Command + K, you need to browse through the specific drive & navigate to the specific folder to mount it in the respective node.

smb://192.168.100.Y

Verify the SMB Drive from the terminal

mount | grep smbfs
ls /Volumes

It will show the newly mounted drive from the terminal as well.

The following is directory structure of the repo for the wrapper Layer that is hosted via the designed UI –

CollibriWrapper/
├── .cursor/
│   ├── hooks.json
│   ├── hooks/inbuilt-memory-capture.sh
│   └── rules/inbuilt-memory.mdc
├── .gitignore
├── .vscode/settings.json
├── config/nodes.json
├── docs/
│   ├── API.md
│   └── NODES_METHODS_AND_ALGORITHMS.md
├── backend/
│   ├── requirements.txt
│   ├── app/
│   │   ├── __init__.py
│   │   ├── capabilities.py
│   │   ├── colibri.py
│   │   ├── config.py
│   │   ├── discover.py
│   │   ├── hoststats.py
│   │   ├── main.py
│   │   ├── orchestrator.py
│   │   ├── planner.py
│   │   ├── scheduler.py
│   │   └── volumes.py
│   └── tests/
│       ├── __init__.py
│       ├── test_capabilities.py
│       ├── test_cluster_schedule.py
│       ├── test_discover.py
│       └── test_planner.py
├── frontend/
│   ├── index.html
│   ├── package.json
│   ├── package-lock.json
│   ├── tsconfig.json
│   ├── vite.config.ts
│   └── src/
│       ├── App.tsx
│       ├── main.tsx
│       ├── styles.css
│       └── types.ts
├── scripts/
│   ├── colibri-volume.sh
│   ├── lib/libomp.dylib
│   ├── restart-from-ui.sh
│   ├── stack-common.sh
│   ├── start.sh
│   ├── start-wrapper.sh
│   ├── stop.sh
│   ├── worker-host.py
│   ├── worker-start.sh
│   └── worker-stop.sh
└── data/
    ├── run/
    │   ├── canvas.log
    │   ├── colibri.log
    │   ├── colibri.volume
    │   ├── memory.log
    │   ├── memory-node.pid
    │   └── wrapper.log
    └── sessions/
        ├── 114af16ca1514055b309408288d8432a.json
        └── 686e1efe04f94ca293aac47e0f75ba5c.json

Start The Master Node:

We’ll be browsing through the right path (In our case) ->

cd /Volumes/TD_BLACK/StartUp/CollibriWrapper/scripts

# Start the Master Node
./start.sh

Stop The Master Node:

# To Stop the Master Node
./stop.sh

Start the Worker Node:

./worker-start.sh

Stop the Worker Node:

./worker-stop.sh

So, we’ve done it. 🙂

I hope you all like this effort & let me know your feedback. I’ll be back with another topic. Until then, Happy Avenging!

Monitoring & evaluating the leading LLMs (both the established & new) by Python-based evaluator

As we’re leaping more & more into the field of Generative AI, one of the frequent questions or challenges people are getting more & more is the performance & other evaluation factors. These factors will eventually bring the fruit of this technology; otherwise, you will end up in technical debt.

This post will discuss the key snippets of the monitoring app based on the Python-based AI app. But before that, let us first view the demo.

Isn’t it exciting?


Let us deep dive into it. But, here is the flow this solution will follow.

So, the current application will invoke the industry bigshots and some relatively unknown or new LLMs.

In this case, we’ll evaluate Anthropic, Open AI, DeepSeek, and Bharat GPT’s various models. However, Bharat GPT is open source, so we’ll use the Huggingface library and execute it locally against my MacBook Pro M4 Max.

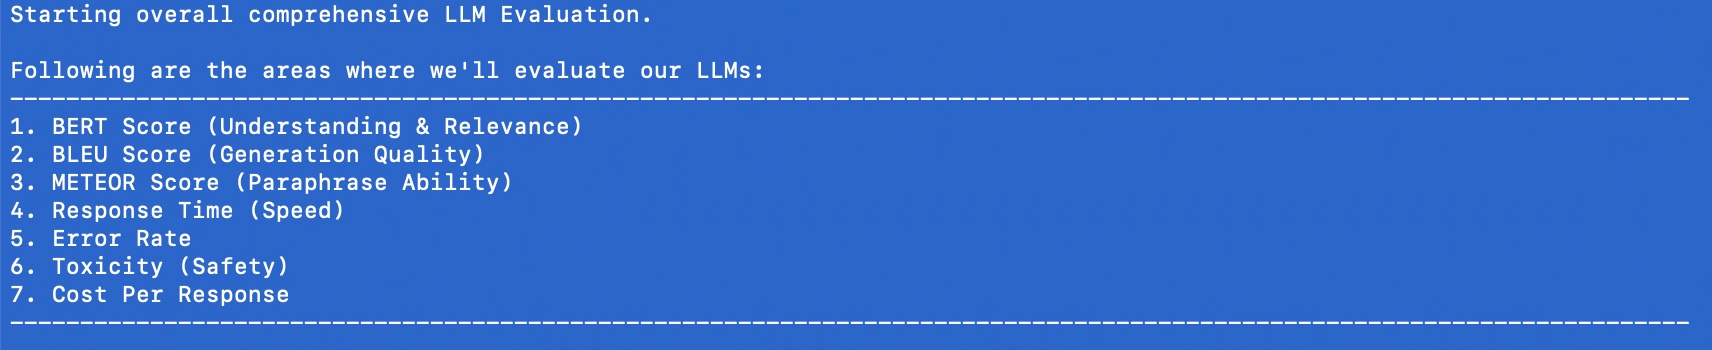
The following are the KPIs we’re going to evaluate:

Here are the lists of dependant python packages that is require to run this application –

pip install certifi==2024.8.30
pip install anthropic==0.42.0
pip install huggingface-hub==0.27.0
pip install nltk==3.9.1
pip install numpy==2.2.1
pip install moviepy==2.1.1
pip install numpy==2.1.3
pip install openai==1.59.3
pip install pandas==2.2.3
pip install pillow==11.1.0
pip install pip==24.3.1
pip install psutil==6.1.1
pip install requests==2.32.3
pip install rouge_score==0.1.2
pip install scikit-learn==1.6.0
pip install setuptools==70.2.0
pip install tokenizers==0.21.0
pip install torch==2.6.0.dev20250104
pip install torchaudio==2.6.0.dev20250104
pip install torchvision==0.22.0.dev20250104
pip install tqdm==4.67.1
pip install transformers==4.47.1
    @retry(stop=stop_after_attempt(3), wait=wait_exponential(multiplier=1, min=4, max=10))
    def get_claude_response(self, prompt: str) -> str:
        response = self.anthropic_client.messages.create(
            model=anthropic_model,
            max_tokens=maxToken,
            messages=[{"role": "user", "content": prompt}]
        )
        return response.content[0].text
  1. The Retry Mechanism
    • The @retry line means this function will automatically try again if it fails.
    • It will stop retrying after 3 attempts (stop_after_attempt(3)).
    • It will wait longer between retries, starting at 4 seconds and increasing up to 10 seconds (wait_exponential(multiplier=1, min=4, max=10)).
  2. The Function Purpose
    • The function takes a message, called prompt, as input (a string of text).
    • It uses a service (likely an AI system like Claude) to generate a response to this prompt.
  3. Sending the Message
    • Inside the function, the code self.anthropic_client.messages.create is the part that actually sends the prompt to the AI.
    • It specifies:Which AI model to use (e.g., anthropic_model).
    • The maximum length of the response (controlled by maxToken).
    • The input message for the AI has a “role” (user), as well as the content of the prompt.
  4. Getting the Response
    • Once the AI generates a response, it’s saved as response.
    • The code retrieves the first part of the response (response.content[0].text) and sends it back to whoever called the function.

Similarly, it will work for Open AI as well.

    @retry(stop=stop_after_attempt(3), wait=wait_exponential(multiplier=1, min=4, max=10))
    def get_deepseek_response(self, prompt: str) -> tuple:
        deepseek_api_key = self.deepseek_api_key

        headers = {
            "Authorization": f"Bearer {deepseek_api_key}",
            "Content-Type": "application/json"
            }
        
        payload = {
            "model": deepseek_model,  
            "messages": [{"role": "user", "content": prompt}],
            "max_tokens": maxToken
            }
        
        response = requests.post(DEEPSEEK_API_URL, headers=headers, json=payload)

        if response.status_code == 200:
            res = response.json()["choices"][0]["message"]["content"]
        else:
            res = "API request failed with status code " + str(response.status_code) + ":" + str(response.text)

        return res
  1. Retry Mechanism:
    • The @retry line ensures the function will try again if it fails.
    • It will stop retrying after 3 attempts (stop_after_attempt(3)).
    • It waits between retries, starting at 4 seconds and increasing up to 10 seconds (wait_exponential(multiplier=1, min=4, max=10)).

  1. What the Function Does:
    • The function takes one input, prompt, which is the message or question you want to send to the AI.
    • It returns the AI’s response or an error message.

  1. Preparing to Communicate with the API:
    • API Key: It gets the API key for the DeepSeek service from self.deepseek_api_key.
    • Headers: These tell the API that the request will use the API key (for security) and that the data format is JSON (structured text).
    • Payload: This is the information sent to the AI. It includes:
      • Model: Specifies which version of the AI to use (deepseek_model).
      • Messages: The input message with the role “user” and your prompt.
      • Max Tokens: Defines the maximum size of the AI’s response (maxToken).

  1. Sending the Request:
    • It uses the requests.post() method to send the payload and headers to the DeepSeek API using the URL DEEPSEEK_API_URL.

  1. Processing the Response:
    • If the API responds successfully (status_code == 200):
      • It extracts the AI’s reply from the response data.
      • Specifically, it gets the first choice’s message content: response.json()["choices"][0]["message"]["content"].
    • If there’s an error:
      • It constructs an error message with the status code and detailed error text from the API.

  1. Returning the Result:
    • The function outputs either the AI’s response or the error message.
    @retry(stop=stop_after_attempt(3), wait=wait_exponential(multiplier=1, min=4, max=10))
    def get_bharatgpt_response(self, prompt: str) -> tuple:
        try:
            messages = [[{"role": "user", "content": prompt}]]
            
            response = pipe(messages, max_new_tokens=maxToken,)

            # Extract 'content' field safely
            res = next((entry.get("content", "")
                        for entry in response[0][0].get("generated_text", [])
                        if isinstance(entry, dict) and entry.get("role") == "assistant"
                        ),
                        None,
                        )
            
            return res
        except Exception as e:
            x = str(e)
            print('Error: ', x)

            return ""
  1. Retry Mechanism:The @retry ensures the function will try again if it fails.
    • It will stop retrying after 3 attempts (stop_after_attempt(3)).
    • The waiting time between retries starts at 4 seconds and increases exponentially up to 10 seconds (wait_exponential(multiplier=1, min=4, max=10)).
  2. What the Function Does:The function takes one input, prompt, which is the message or question you want to send to BharatGPT.
    • It returns the AI’s response or an empty string if something goes wrong.
  3. Sending the Prompt:Messages Structure: The function wraps the user’s prompt in a format that the BharatGPT AI understands:
    • messages = [[{"role": "user", "content": prompt}]]
    • This tells the AI that the prompt is coming from the “user.”
  4. Pipe Function: It uses a pipe() method to send the messages to the AI system.
    • max_new_tokens=maxToken: Limits how long the AI’s response can be.
  5. Extracting the Response:The response from the AI is in a structured format. The code looks for the first piece of text where:
    • The role is “assistant” (meaning it’s the AI’s reply).
    • The text is in the “content” field.
    • The next() function safely extracts this “content” field or returns None if it can’t find it.
  6. Error Handling:If something goes wrong (e.g., the AI doesn’t respond or there’s a technical issue), the code:
    • Captures the error message in e.
    • Prints the error message: print('Error: ', x).
    • Returns an empty string ("") instead of crashing.
  7. Returning the Result:If everything works, the function gives you the AI’s response as plain text.
    • If there’s an error, it gives you an empty string, indicating no response was received.

    def get_model_response(self, model_name: str, prompt: str) -> ModelResponse:
        """Get response from specified model with metrics"""
        start_time = time.time()
        start_memory = psutil.Process(os.getpid()).memory_info().rss / 1024 / 1024

        try:
            if model_name == "claude-3":
                response_content = self.get_claude_response(prompt)
            elif model_name == "gpt4":
                response_content = self.get_gpt4_response(prompt)
            elif model_name == "deepseek-chat":
                response_content = self.get_deepseek_response(prompt)
            elif model_name == "bharat-gpt":
                response_content = self.get_bharatgpt_response(prompt)

            # Model-specific API calls 
            token_count = len(self.bert_tokenizer.encode(response_content))
            
            end_memory = psutil.Process(os.getpid()).memory_info().rss / 1024 / 1024
            memory_usage = end_memory - start_memory
            
            return ModelResponse(
                content=response_content,
                response_time=time.time() - start_time,
                token_count=token_count,
                memory_usage=memory_usage
            )
        except Exception as e:
            logging.error(f"Error getting response from {model_name}: {str(e)}")
            return ModelResponse(
                content="",
                response_time=0,
                token_count=0,
                memory_usage=0,
                error=str(e)
            )

Start Tracking Time and Memory:

    • The function starts a timer (start_time) to measure how long it takes to get a response.
    • It also checks how much memory is being used at the beginning (start_memory).

    Choose the AI Model:

    • Based on the model_name provided, the function selects the appropriate method to get a response:
      • "claude-3" → Calls get_claude_response(prompt).
      • "gpt4" → Calls get_gpt4_response(prompt).
      • "deepseek-chat" → Calls get_deepseek_response(prompt).
      • "bharat-gpt" → Calls get_bharatgpt_response(prompt).

    Process the Response:

    • Once the response is received, the function calculates:
      • Token Count: The number of tokens (small chunks of text) in the response using a tokenizer.
      • Memory Usage: The difference between memory usage after the response (end_memory) and before it (start_memory).

    Return the Results:

    • The function bundles all the information into a ModelResponse object:
      • The AI’s reply (content).
      • How long the response took (response_time).
      • The number of tokens in the reply (token_count).
      • How much memory was used (memory_usage).

    Handle Errors:

    • If something goes wrong (e.g., the AI doesn’t respond), the function:
      • Logs the error message.
      • Returns an empty response with default values and the error message.
        def evaluate_text_quality(self, generated: str, reference: str) -> Dict[str, float]:
            """Evaluate text quality metrics"""
            # BERTScore
            gen_embedding = self.sentence_model.encode([generated])
            ref_embedding = self.sentence_model.encode([reference])
            bert_score = cosine_similarity(gen_embedding, ref_embedding)[0][0]
    
            # BLEU Score
            generated_tokens = word_tokenize(generated.lower())
            reference_tokens = word_tokenize(reference.lower())
            bleu = sentence_bleu([reference_tokens], generated_tokens)
    
            # METEOR Score
            meteor = meteor_score([reference_tokens], generated_tokens)
    
            return {
                'bert_score': bert_score,
                'bleu_score': bleu,
                'meteor_score': meteor
            }

    Inputs:

    • generated: The text produced by the AI.
    • reference: The correct or expected version of the text.

    Calculating BERTScore:

    • Converts the generated and reference texts into numerical embeddings (mathematical representations) using a pre-trained model (self.sentence_model.encode).
    • Measures the similarity between the two embeddings using cosine similarity. This gives the bert_score, which ranges from -1 (completely different) to 1 (very similar).

    Calculating BLEU Score:

    • Breaks the generated and reference texts into individual words (tokens) using word_tokenize.
    • Converts both texts to lowercase for consistent comparison.
    • Calculates the BLEU Score (sentence_bleu), which checks how many words or phrases in the generated text overlap with the reference. BLEU values range from 0 (no match) to 1 (perfect match).

    Calculating METEOR Score:

    • Also uses the tokenized versions of generated and reference texts.
    • Calculates the METEOR Score (meteor_score), which considers exact matches, synonyms, and word order. Scores range from 0 (no match) to 1 (perfect match).

    Returning the Results:

    • Combines the three scores into a dictionary with the keys 'bert_score', 'bleu_score', and 'meteor_score'.

    Similarly, other functions are developed.

        def run_comprehensive_evaluation(self, evaluation_data: List[Dict]) -> pd.DataFrame:
            """Run comprehensive evaluation on all metrics"""
            results = []
            
            for item in evaluation_data:
                prompt = item['prompt']
                reference = item['reference']
                task_criteria = item.get('task_criteria', {})
                
                for model_name in self.model_configs.keys():
                    # Get multiple responses to evaluate reliability
                    responses = [
                        self.get_model_response(model_name, prompt)
                        for _ in range(3)  # Get 3 responses for reliability testing
                    ]
                    
                    # Use the best response for other evaluations
                    best_response = max(responses, key=lambda x: len(x.content) if not x.error else 0)
                    
                    if best_response.error:
                        logging.error(f"Error in model {model_name}: {best_response.error}")
                        continue
                    
                    # Gather all metrics
                    metrics = {
                        'model': model_name,
                        'prompt': prompt,
                        'response': best_response.content,
                        **self.evaluate_text_quality(best_response.content, reference),
                        **self.evaluate_factual_accuracy(best_response.content, reference),
                        **self.evaluate_task_performance(best_response.content, task_criteria),
                        **self.evaluate_technical_performance(best_response),
                        **self.evaluate_reliability(responses),
                        **self.evaluate_safety(best_response.content)
                    }
                    
                    # Add business impact metrics using task performance
                    metrics.update(self.evaluate_business_impact(
                        best_response,
                        metrics['task_completion']
                    ))
                    
                    results.append(metrics)
            
            return pd.DataFrame(results)
    • Input:
      • evaluation_data: A list of test cases, where each case is a dictionary containing:
        • prompt: The question or input to the AI model.
        • reference: The ideal or expected answer.
        • task_criteria (optional): Additional rules or requirements for the task.
    • Initialize Results:
      • An empty list results is created to store the evaluation metrics for each model and test case.
    • Iterate Through Test Cases:
      • For each item in the evaluation_data:
        • Extract the prompt, reference, and task_criteria.
    • Evaluate Each Model:
      • Loop through all available AI models (self.model_configs.keys()).
      • Generate three responses for each model to test reliability.
    • Select the Best Response:
      • Out of the three responses, pick the one with the most content (best_response), ignoring responses with errors.
    • Handle Errors:
      • If a response has an error, log the issue and skip further evaluation for that model.
    • Evaluate Metrics:
      • Using the best_response, calculate a variety of metrics, including:
        • Text Quality: How similar the response is to the reference.
        • Factual Accuracy: Whether the response is factually correct.
        • Task Performance: How well it meets task-specific criteria.
        • Technical Performance: Evaluate time, memory, or other system-related metrics.
        • Reliability: Check consistency across multiple responses.
        • Safety: Ensure the response is safe and appropriate.
    • Evaluate Business Impact:
      • Add metrics for business impact (e.g., how well the task was completed, using task_completion as a key factor).
    • Store Results:
      • Add the calculated metrics for this model and prompt to the results list.
    • Return Results as a DataFrame:
      • Convert the results list into a structured table (a pandas DataFrame) for easy analysis and visualization.

    Great! So, now, we’ve explained the code.

    Let us understand the final outcome of this run & what we can conclude from that.

    1. BERT Score (Semantic Understanding):
      • GPT4 leads slightly at 0.8322 (83.22%)
      • Bharat-GPT close second at 0.8118 (81.18%)
      • Claude-3 at 0.8019 (80.19%)
      • DeepSeek-Chat at 0.7819 (78.19%) Think of this like a “comprehension score” – how well the models understand the context. All models show strong understanding, with only a 5% difference between best and worst.
    2. BLEU Score (Word-for-Word Accuracy):
      • Bharat-GPT leads at 0.0567 (5.67%)
      • Claude-3 at 0.0344 (3.44%)
      • GPT4 at 0.0306 (3.06%)
      • DeepSeek-Chat lowest at 0.0189 (1.89%) These low scores suggest models use different wording than references, which isn’t necessarily bad.
    3. METEOR Score (Meaning Preservation):
      • Bharat-GPT leads at 0.4684 (46.84%)
      • Claude-3 close second at 0.4507 (45.07%)
      • GPT4 at 0.2960 (29.60%)
      • DeepSeek-Chat at 0.2652 (26.52%) This shows how well models maintain meaning while using different words.
    4. Response Time (Speed):
      • Claude-3 fastest: 4.40 seconds
      • Bharat-GPT: 6.35 seconds
      • GPT4: 6.43 seconds
      • DeepSeek-Chat slowest: 8.52 seconds
    5. Safety and Reliability:
      • Error Rate: Perfect 0.0 for all models
      • Toxicity: All very safe (below 0.15%) 
        • Claude-3 safest at 0.0007GPT4 at 0.0008Bharat-GPT at 0.0012
        • DeepSeek-Chat at 0.0014
    6. Cost Efficiency:
      • Claude-3 most economical: $0.0019 per response
      • Bharat-GPT close: $0.0021
      • GPT4: $0.0038
      • DeepSeek-Chat highest: $0.0050

    Key Takeaways by Model:

    1. Claude-3: ✓ Fastest responses ✓ Most cost-effective ✓ Excellent meaning preservation ✓ Lowest toxicity
    2. Bharat-GPT: ✓ Best BLEU and METEOR scores ✓ Strong semantic understanding ✓ Cost-effective ✗ Moderate response time
    3. GPT4: ✓ Best semantic understanding ✓ Good safety metrics ✗ Higher cost ✗ Moderate response time
    4. DeepSeek-Chat: ✗ Generally lower performance ✗ Slowest responses ✗ Highest cost ✗ Slightly higher toxicity

    Reliability of These Statistics:

    Strong Points:

    • Comprehensive metric coverage
    • Consistent patterns across evaluations
    • Zero error rates show reliability
    • Clear differentiation between models

    Limitations:

    • BLEU scores are quite low across all models
    • Doesn’t measure creative or innovative responses
    • May not reflect specific use case performance
    • Single snapshot rather than long-term performance

    Final Observation:

    1. Best Overall Value: Claude-3
      • Fast, cost-effective, safe, good performance
    2. Best for Accuracy: Bharat-GPT
      • Highest meaning preservation and precision
    3. Best for Understanding: GPT4
      • Strongest semantic comprehension
    4. Consider Your Priorities: 
      • Speed → Choose Claude-3
      • Cost → Choose Claude-3 or Bharat-GPT
      • Accuracy → Choose Bharat-GPT
      • Understanding → Choose GPT4

    These statistics provide reliable comparative data but should be part of a broader decision-making process that includes your specific needs, budget, and use cases.


    For the Bharat GPT model, we’ve tested this locally on my MacBook Pro 4 Max. And, the configuration is as follows –

    I’ve tried the API version locally, & it provided a similar performance against the stats that we received by running locally. Unfortunately, they haven’t made the API version public yet.

    So, apart from the Anthropic & Open AI, I’ll watch this new LLM (Bharat GPT) for overall stats in the coming days.


    So, we’ve done it.

    You can find the detailed code at the GitHub link.

    I’ll bring some more exciting topics in the coming days from the Python verse.

    Till then, Happy Avenging! 🙂

    Hacking the performance of Python Solutions with a custom-built library

    Today, I’m very excited to demonstrate an effortless & new way to hack the performance of Python. This post will be a super short & yet crisp presentation of improving the overall performance.

    Why not view the demo before going through it?


    Demo

    Isn’t it exciting? Let’s understand the steps to improve your code.

    pip install cython

    Cython is a Python-to-C compiler. It can significantly improve performance for specific tasks, especially those with heavy computation and loops. Also, Cython’s syntax is very similar to Python, which makes it easy to learn.

    Let’s consider an example where we calculate the sum of squares for a list of numbers. The code without optimization would look like this:

    • perfTest_1.py (First untuned Python class.)
    #########################################################
    #### Written By: SATYAKI DE                          ####
    #### Written On: 31-Jul-2023                         ####
    #### Modified On 31-Jul-2023                         ####
    ####                                                 ####
    #### Objective: This is the main calling             ####
    #### python script that will invoke the              ####
    #### first version of accute computation.            ####
    ####                                                 ####
    #########################################################
    from clsConfigClient import clsConfigClient as cf
    
    import time
    start = time.time()
    
    n_val = cf.conf['INPUT_VAL']
    
    def compute_sum_of_squares(n):
        return sum([i**2 for i in range(n)])
    
    n = n_val
    
    print(compute_sum_of_squares(n))
    
    print(f"Test - 1: Execution time: {time.time() - start} seconds")
    

    Here, n_val contains the value as – “1000000000”.

    Now, let’s optimize it using Cython by installing the abovementioned packages. Then, you will have to create a .pyx file, say “compute.pyx”, with the following code:

    cpdef double compute_sum_of_squares(int n):
        return sum([i**2 for i in range(n)])
    

    Now, create a setup.py file to compile it:

    ###########################################################
    #### Written By: SATYAKI DE                            ####
    #### Written On: 31-Jul-2023                           ####
    #### Modified On 31-Jul-2023                           ####
    ####                                                   ####
    #### Objective: This is the main calling               ####
    #### python script that will create the                ####
    #### compiled library after executing the compute.pyx. ####
    ####                                                   ####
    ###########################################################
    
    from setuptools import setup
    from Cython.Build import cythonize
    
    setup(
        ext_modules = cythonize("compute.pyx")
    )
    

    Compile it using the command:

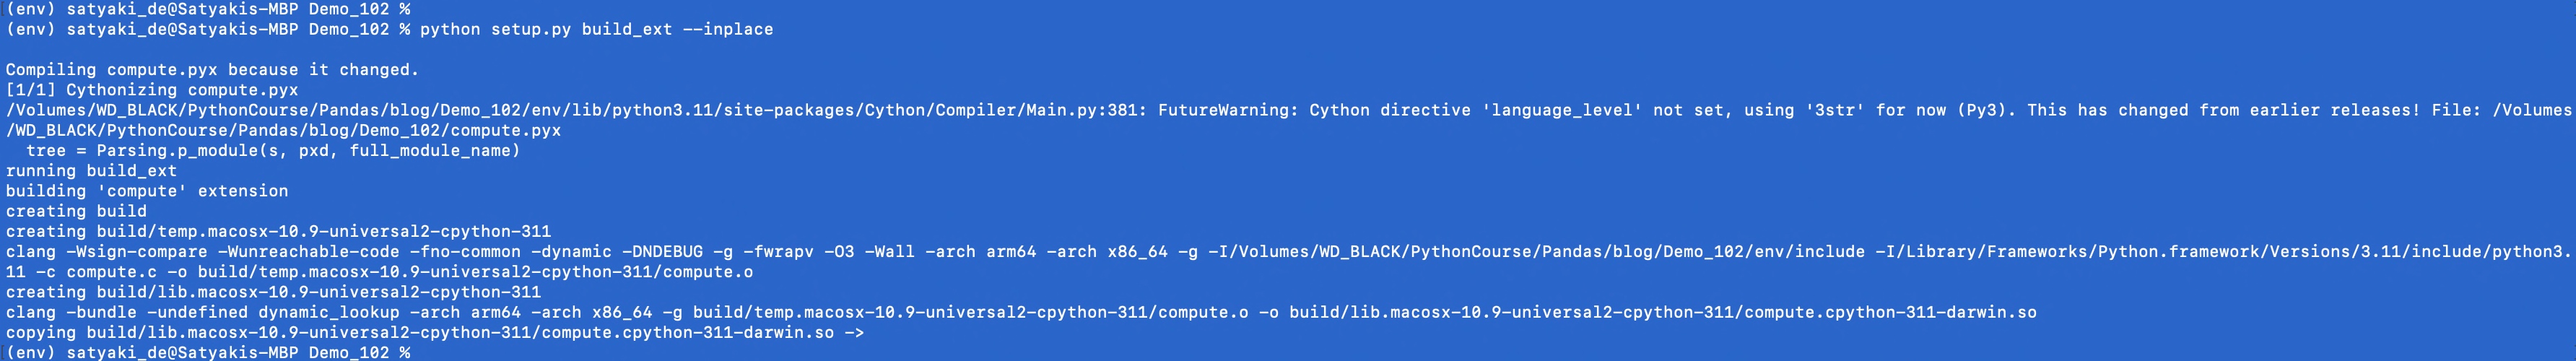
    python setup.py build_ext --inplace

    This will look like the following –

    Finally, you can import the function from the compiled “.pyx” file inside the improved code.

    • perfTest_2.py (First untuned Python class.)
    #########################################################
    #### Written By: SATYAKI DE                          ####
    #### Written On: 31-Jul-2023                         ####
    #### Modified On 31-Jul-2023                         ####
    ####                                                 ####
    #### Objective: This is the main calling             ####
    #### python script that will invoke the              ####
    #### optimized & precompiled custom library, which   ####
    #### will significantly improve the performance.     ####
    ####                                                 ####
    #########################################################
    from clsConfigClient import clsConfigClient as cf
    from compute import compute_sum_of_squares
    
    import time
    start = time.time()
    
    n_val = cf.conf['INPUT_VAL']
    
    n = n_val
    
    print(compute_sum_of_squares(n))
    
    print(f"Test - 2: Execution time with multiprocessing: {time.time() - start} seconds")
    

    By compiling to C, Cython can speed up loop and function calls, leading to significant speedup for CPU-bound tasks.

    Please note that while Cython can dramatically improve performance, it can make the code more complex and harder to debug. Therefore, starting with regular Python and switching to Cython for the performance-critical parts of the code is recommended.


    So, finally, we’ve done it. I know that this post is relatively smaller than my earlier post. But, I think, you can get a good hack to improve some of your long-running jobs by applying this trick.

    I’ll bring some more exciting topics in the coming days from the Python verse. Please share & subscribe to my post & let me know your feedback.

    Till then, Happy Avenging! 🙂

    Python performance improvement with 3.11 Version

    Today, we’ll share another performance improvement incorporating the latest Python 3.11 version. You can consider this significant advancement over the past versions. Last time, I posted for 3.7 in one of my earlier posts. But, we should diligently update everyone regarding the performance upgrade as it is slowly catching up with some of the finest programming languages.

    But, before that, I want to share the latest stats of the machine where I tried these tests (As there is a change of system compared to last time).


    Let us explore the base code –

    ##############################################
    #### Written By: SATYAKI DE               ####
    #### Written On: 06-May-2021              ####
    #### Modified On: 30-Oct-2022             ####
    ####                                      ####
    #### Objective: Main calling scripts for  ####
    #### normal execution.                    ####
    ##############################################
    
    from timeit import default_timer as timer
    
    def vecCompute(sizeNum):
        try:
            total = 0
            for i in range(1, sizeNum):
                for j in range(1, sizeNum):
                    total += i + j
            return total
        except Excception as e:
            x = str(e)
            print('Error: ', x)
    
            return 0
    
    
    def main():
    
        start = timer()
    
        totalM = 0
        totalM = vecCompute(100000)
    
        print('The result is : ' + str(totalM))
        duration = timer() - start
        print('It took ' + str(duration) + ' seconds to compute')
    
    if __name__ == '__main__':
        main()
    

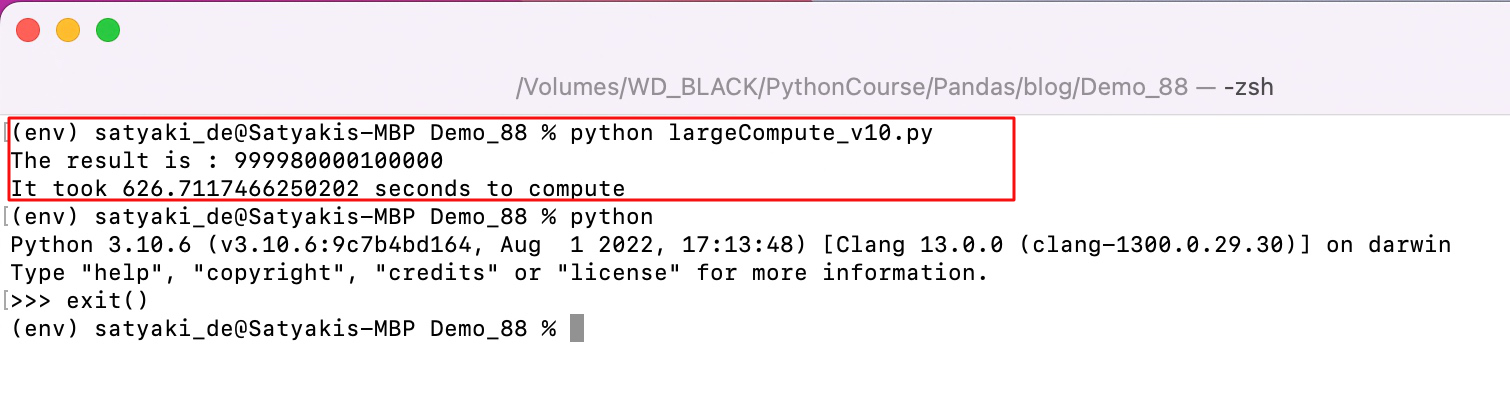
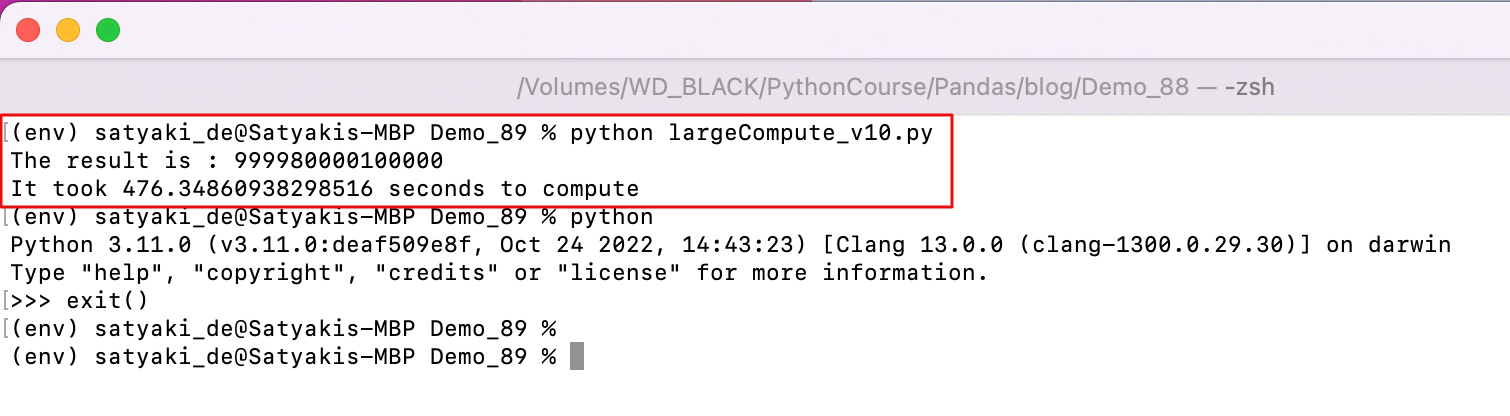
    And here is the outcome comparison between the 3.10 & 3.11 –

    The above screenshot shows an improvement of 23% on an average compared to the previous version.

    These performance stats are highly crucial. The result shows how Python is slowly emerging as the universal language for various kinds of work and is now targetting one of the vital threads, i.e., improvement of performance.


    So, finally, we have done it.

    I’ll bring some more exciting topic in the coming days from the Python verse.

    Till then, Happy Avenging! 🙂

    Note: All the data & scenario posted here are representational data & scenarios & available over the internet & for educational purpose only.

    Memory profiler in Python

    Today, I’ll be discussing a short but critical python topic. That is capturing the performance matrix by analyzing the memory profiling.

    We’ll take any ordinary scripts & then use this package to analyze them.

    But, before we start, why don’t we see the demo & then go through it?

    Demo

    Isn’t exciting? Let us understand in details.

    For this, we’ve used the following package –

    pip install memory-profiler


    How you can run this?

    All you have to do is to modify your existing python function & add this “profile” keyword. And this will open a brand new information shop for you.

    #####################################################
    #### Written By: SATYAKI DE                      ####
    #### Written On: 22-Jul-2022                     ####
    #### Modified On 30-Aug-2022                     ####
    ####                                             ####
    #### Objective: This is the main calling         ####
    #### python script that will invoke the          ####
    #### clsReadForm class to initiate               ####
    #### the reading capability in real-time         ####
    #### & display text from a formatted forms.      ####
    #####################################################
    
    # We keep the setup code in a different class as shown below.
    import clsReadForm as rf
    
    from clsConfig import clsConfig as cf
    
    import datetime
    import logging
    
    ###############################################
    ###           Global Section                ###
    ###############################################
    # Instantiating all the main class
    
    x1 = rf.clsReadForm()
    
    ###############################################
    ###    End of Global Section                ###
    ###############################################
    @profile
    def main():
        try:
            # Other useful variables
            debugInd = 'Y'
            var = datetime.datetime.now().strftime("%Y-%m-%d_%H-%M-%S")
            var1 = datetime.datetime.now()
    
            print('Start Time: ', str(var))
            # End of useful variables
    
            # Initiating Log Class
            general_log_path = str(cf.conf['LOG_PATH'])
    
            # Enabling Logging Info
            logging.basicConfig(filename=general_log_path + 'readingForm.log', level=logging.INFO)
    
            print('Started extracting text from formatted forms!')
    
            # Execute all the pass
            r1 = x1.startProcess(debugInd, var)
    
            if (r1 == 0):
                print('Successfully extracted text from the formatted forms!')
            else:
                print('Failed to extract the text from the formatted forms!')
    
            var2 = datetime.datetime.now()
    
            c = var2 - var1
            minutes = c.total_seconds() / 60
            print('Total difference in minutes: ', str(minutes))
    
            print('End Time: ', str(var1))
    
        except Exception as e:
            x = str(e)
            print('Error: ', x)
    
    if __name__ == "__main__":
        main()
    

    Let us analyze the code. As you can see that, we’ve converted a normal python main function & mar it as @profile.

    The next step is to run the following command –

    python -m memory_profiler readingForm.py

    This will trigger the script & it will collect all the memory information against individual lines & display it as shown in the demo.

    I think this will give all the python developer a great insight about their quality of the code, which they have developed. To know more on this you can visit the following link.

    I’ll bring some more exciting topic in the coming days from the Python verse. Please share & subscribe my post & let me know your feedback.

    Till then, Happy Avenging! 🙂

    Note: All the data & scenario posted here are representational data & scenarios & available over the internet & for educational purpose only. Some of the images (except my photo) that we’ve used are available over the net. We don’t claim the ownership of these images. There is an always room for improvement & especially the prediction quality.

    Another marvelous performance tuning tricks in Python

    Hi Guys!

    Today, I’ll be showing another post on how one can drastically improve the performance of a python code. Last time, we took advantage of vector computing by using GPU-based computation. This time we’ll explore PyPy (the new just in time compiler, while Python is the interpreter).


    What is PyPy?

    According to the standard description available over the net ->

    PyPy is a very compliant Python interpreter that is a worthy alternative to CPython. By installing and running your application with it, you can gain noticeable speed improvements. How much of an improvement you’ll see depends on the application you’re running.

    What is JIT (Just-In Time) compiler?

    A compiled programming language always faster in execution as it generates the bytecode based on the CPU architecture & OS. However, they are challenging to port into another system. Example: C, C++ etc.

    Interpreted languages are easy to port into a new system. However, they lack performance. Example: Perl, Matlab, etc.

    However, python falls between the two. Hence, it performs better than purely interpreted languages. But, indeed not as good as compiler-driven language.

    There is a new Just in time compiler comes, which takes advantage of both the world. It identifies the repeatable code & converts those chunks into machine learning code for optimum performance.


    To prepare the environment, you need to install the following in MAC (I’m using MacBook) –

    brew install pypy3

    Let’s revisit our code.

    Step 1: largeCompute.py (The main script, which will participate in a performance for both the interpreter):

    ##############################################
    #### Written By: SATYAKI DE ####
    #### Written On: 06-May-2021 ####
    #### ####
    #### Objective: Main calling scripts for ####
    #### normal execution. ####
    ##############################################
    from timeit import default_timer as timer
    def vecCompute(sizeNum):
    try:
    total = 0
    for i in range(1, sizeNum):
    for j in range(1, sizeNum):
    total += i + j
    return total
    except Excception as e:
    x = str(e)
    print('Error: ', x)
    return 0
    def main():
    start = timer()
    totalM = 0
    totalM = vecCompute(100000)
    print('The result is : ' + str(totalM))
    duration = timer() - start
    print('It took ' + str(duration) +' seconds to compute')
    if __name__ == '__main__':
    main()
    view raw largeCompute.py hosted with ❤ by GitHub

    Key snippets from the above script –

    for i in range(1, sizeNum):
                for j in range(1, sizeNum):
                    total += i + j

    vecCompute function calculates 100000 * 100000 or any new supplied number to process the value (I = I + J) of each iteration.


    Let’s see how it performs.

    To run the commands in pypy you need to use the following command –

    pypy largeCompute.py

    or, You have to mention the specific path as follows –

    /Users/satyaki_de/Desktop/pypy3.7-v7.3.4-osx64/bin/pypy largeCompute.py
    Performance Comparison between two interpreters

    As you can see there is a significant performance improvement i.e. (352.079 / 14.503) = 24.276. So, I can clearly say 24 times faster than using the standard python interpreter. This is as good as C++ code.


    Where not to use?

    PyPy works best with the pure python-driven applications. It can’t work with the Python or any C extension in python. Hence, you won’t get that benefits. However, I have a strong believe that one day we may use this for most of our use cases.

    For more information, please visit this link. So, this is another shortest yet effective post. 🙂


    So, finally, we have done it.

    I’ll bring some more exciting topic in the coming days from the Python verse.

    Till then, Happy Avenging! 😀

    Note: All the data & scenario posted here are representational data & scenarios & available over the internet & for educational purpose only.

    Performance improvement of Python application programming

    Hello guys,

    Today, I’ll be demonstrating a short but significant topic. There are widespread facts that, on many occasions, Python is relatively slower than other strongly typed programming languages like C++, Java, or even the latest version of PHP.

    I found a relatively old post with a comparison shown between Python and the other popular languages. You can find the details at this link.

    However, I haven’t verified the outcome. So, I can’t comment on the final statistics provided on that link.

    My purpose is to find cases where I can take certain tricks to improve performance drastically.

    One preferable option would be the use of Cython. That involves the middle ground between C & Python & brings the best out of both worlds.

    The other option would be the use of GPU for vector computations. That would drastically increase the processing power. Today, we’ll be exploring this option.

    Let’s find out what we need to prepare our environment before we try out on this.

    Step – 1 (Installing dependent packages):

    pip install pyopencl
    pip install plaidml-keras

    So, we will be taking advantage of the Keras package to use our GPU. And, the screen should look like this –

    Installation Process of Python-based Packages

    Once we’ve installed the packages, we’ll configure the package showing on the next screen.

    Configuration of Packages

    For our case, we need to install pandas as we’ll be using numpy, which comes default with it.

    Installation of supplemental packages

    Let’s explore our standard snippet to test this use case.

    Case 1 (Normal computational code in Python):

    ##############################################
    #### Written By: SATYAKI DE               ####
    #### Written On: 18-Jan-2020              ####
    ####                                      ####
    #### Objective: Main calling scripts for  ####
    #### normal execution.                    ####
    ##############################################
    
    import numpy as np
    from timeit import default_timer as timer
    
    def pow(a, b, c):
        for i in range(a.size):
             c[i] = a[i] ** b[i]
    
    def main():
        vec_size = 100000000
    
        a = b = np.array(np.random.sample(vec_size), dtype=np.float32)
        c = np.zeros(vec_size, dtype=np.float32)
    
        start = timer()
        pow(a, b, c)
        duration = timer() - start
    
        print(duration)
    
    if __name__ == '__main__':
        main()

    Case 2 (GPU-based computational code in Python):

    #################################################
    #### Written By: SATYAKI DE                  ####
    #### Written On: 18-Jan-2020                 ####
    ####                                         ####
    #### Objective: Main calling scripts for     ####
    #### use of GPU to speed-up the performance. ####
    #################################################
    
    import numpy as np
    from timeit import default_timer as timer
    
    # Adding GPU Instance
    from os import environ
    environ["KERAS_BACKEND"] = "plaidml.keras.backend"
    
    def pow(a, b):
        return a ** b
    
    def main():
        vec_size = 100000000
    
        a = b = np.array(np.random.sample(vec_size), dtype=np.float32)
        c = np.zeros(vec_size, dtype=np.float32)
    
        start = timer()
        c = pow(a, b)
        duration = timer() - start
    
        print(duration)
    
    if __name__ == '__main__':
        main()

    And, here comes the output for your comparisons –

    Case 1 Vs Case 2:

    Performance Comparisons

    As you can see, there is a significant improvement that we can achieve using this. However, it has limited scope. Not everywhere you get the benefits. Until or unless Python decides to work on the performance side, you better need to explore either of the two options that I’ve discussed here (I didn’t mention a lot on Cython here. Maybe some other day.).

    To get the codebase you can refer the following Github link.


    So, finally, we have done it.

    I’ll bring some more exciting topic in the coming days from the Python verse.

    Till then, Happy Avenging! 😀

    Note: All the data & scenario posted here are representational data & scenarios & available over the internet & for educational purpose only.