Pandas, Numpy, Encryption/Decryption, Hidden Files In Python (Crossover between Space Stone, Reality Stone & Mind Stone of Python-Verse)

So, here we come up with another crossover of Space Stone, Reality Stone & Mind Stone of Python-Verse. It is indeed exciting & I cannot wait to explore that part further. Today, in this post, we’ll see how one application can integrate all these key ingredients in Python to serve the purpose. Our key focus will be involving popular packages like Pandas, Numpy & Popular Encryption-Decryption techniques, which include some hidden files as well.

So, our objective here is to proceed with the encryption & decryption technique. But, there is a catch. We need to store some salt or tokenized value inside a hidden file. Our application will extract the salt value from it & then based on that it will perform Encrypt/Decrypt on the data.

Why do we need this approach?

The answer is simple. On many occasions, we don’t want to store our right credentials in configuration files. Also, we don’t want to keep our keys to open to other developers. There are many ways you can achieve this kind of security.  Today, I’ll be showing a different approach to make the same.

Let’s explore.

As usual, I’ll provide the solution, which is tested in Windows & MAC & provide the script. Also, I’ll explain the critical lines of those scripts to understand it from a layman point of view. And, I won’t explain any script, which I’ve already explained in my earlier post. So, you have to refer my old post for that.

To encrypt & decrypt, we need the following files, which contains credentials in a csv. Please find the sample data –

Config_orig.csv

Orig_File

Please see the file, which will be hidden by the application process.
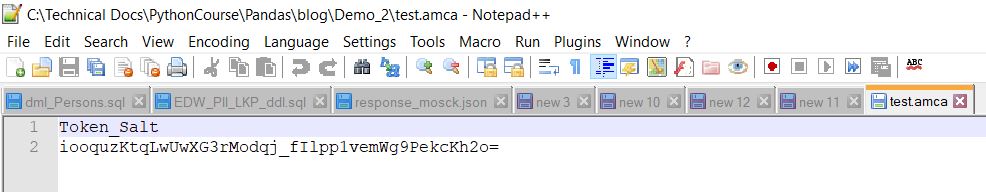
Token_Salt_File

As you can see, this column contains the salt, which will be used in our Encryption/Decryption.

1. clsL.py (This script will create the csv files or any intermediate debug csv file after the corresponding process. Hence, the name comes into the picture.)

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
###########################################
#### Written By: SATYAKI DE        ########
#### Written On: 25-Jan-2019       ########
####                               ########
#### Objective: Log File           ########
###########################################
import pandas as p
import platform as pl
from clsParam import clsParam as cf

class clsL(object):
    def __init__(self):
        self.path = cf.config['PATH']

    def logr(self, Filename, Ind, df, subdir=None):
        try:
            x = p.DataFrame()
            x = df
            sd = subdir

            os_det = pl.system()

            if sd == None:
                if os_det == "Windows":
                    fullFileName = self.path + '\\' + Filename
                else:
                    fullFileName = self.path + '/' + Filename
            else:
                if os_det == "Windows":
                    fullFileName = self.path + '\\' + sd + "\\" + Filename
                else:
                    fullFileName = self.path + '/' + sd + "/" + Filename

            if Ind == 'Y':
                x.to_csv(fullFileName, index=False)

            return 0

        except Exception as e:
            y = str(e)
            print(y)
            return 3

2. clsParam.py (This is the script that will be used as a parameter file & will be used in other python scripts.)

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
###########################################
#### Written By: SATYAKI DE        ########
#### Written On: 25-Jan-2019       ########
#### Objective: Parameter File     ########
###########################################

import os
import platform as pl

class clsParam(object):

    config = {
        'FILENAME' : 'test.amca',
        'OSX_MOD_FILE_NM': '.test.amca',
        'CURR_PATH': os.path.dirname(os.path.realpath(__file__)),
        'NORMAL_FLAG': 32,
        'HIDDEN_FLAG': 34,
        'OS_DET': pl.system()
    }


3. clsWinHide.py (This script contains the core logic of hiding/unhiding a file under Windows OS. Hence, the name comes into the picture.)

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
###########################################
#### Written By: SATYAKI DE          ######
#### Written On: 25-Jan-2019         ######
####                                 ######
#### This script will hide or Unhide ######
#### Files in Windows.               ######
###########################################

import win32file
import win32con
from clsParam import clsParam as cp

class clsWinHide(object):
    def __init__(self):
        self.path = cp.config['CURR_PATH']
        self.FileName = cp.config['FILENAME']
        self.normal_file_flag = cp.config['NORMAL_FLAG']

    def doit(self):
        try:
            path = self.path
            FileName = self.FileName

            FileNameWithPath = path + '\\' + FileName
            flags = win32file.GetFileAttributesW(FileNameWithPath)
            win32file.SetFileAttributes(FileNameWithPath,win32con.FILE_ATTRIBUTE_HIDDEN | flags)

            return 0
        except Exception as e:
            x = str(e)
            print(x)

            return 1

    def undoit(self):
        try:
            path = self.path
            FileName = self.FileName
            normal_file_flag = self.normal_file_flag

            FileNameWithPath = path + '\\' + FileName
            win32file.SetFileAttributes(FileNameWithPath,win32con.FILE_ATTRIBUTE_NORMAL | int(normal_file_flag))

            return 0
        except Exception as e:
            x = str(e)
            print(x)

            return 1

Key lines that we would like to explore are as follows –

def doit()

flags = win32file.GetFileAttributesW(FileNameWithPath)
win32file.SetFileAttributes(FileNameWithPath,win32con.FILE_ATTRIBUTE_HIDDEN | flags)

The above two lines under doit() functions are changing the file attributes in Windows OS to the hidden mode by assigning the FILE_ATTRIBUTE_HIDDEN property.

def undoit()

normal_file_flag = self.normal_file_flag

FileNameWithPath = path + '\\' + FileName
win32file.SetFileAttributes(FileNameWithPath,win32con.FILE_ATTRIBUTE_NORMAL | int(normal_file_flag))

As the script suggested, the application is setting the file attribute of a hidden file to FILE_ATTRIBUTE_NORMAL & set the correct flag from parameters, which leads to the file appears as a normal windows file.

4. clsOSXHide.py (This script contains the core logic of hiding/unhiding a file under OSX, i.e., MAC OS. Hence, the name comes into the picture.)

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
###########################################
#### Written By: SATYAKI DE           #####
#### Written On: 25-Jan-2019          #####
####                                  #####
#### Objective: This script will hide #####
#### or Unhide the file in OSX.       #####
###########################################

import os
from clsParam import clsParam as cp

class clsOSXHide(object):
    def __init__(self):
        self.path = cp.config['CURR_PATH']
        self.FileName = cp.config['FILENAME']
        self.OSX_Mod_FileName = cp.config['OSX_MOD_FILE_NM']
        self.normal_file_flag = cp.config['NORMAL_FLAG']

    def doit(self):
        try:
            path = self.path
            FileName = self.FileName

            FileNameWithPath = path + '/' + FileName
            os.rename(FileNameWithPath, os.path.join(os.path.dirname(FileNameWithPath),'.'
                                                     + os.path.basename(FileNameWithPath)))

            return 0
        except Exception as e:
            x = str(e)
            print(x)

            return 1

    def undoit(self):
        try:
            path = self.path
            FileName = self.FileName
            OSX_Mod_FileName = self.OSX_Mod_FileName

            FileNameWithPath = path + '/' + FileName
            os.rename(OSX_Mod_FileName, FileNameWithPath)

            return 0
        except Exception as e:
            x = str(e)
            print(x)

            return 1

The key lines that we’ll be exploring here are as follows –

def doit()

FileNameWithPath = path + '/' + FileName
os.rename(FileNameWithPath, os.path.join(os.path.dirname(FileNameWithPath),'.'
                                         + os.path.basename(FileNameWithPath)))

In MAC or Linux, any file starts with ‘.’ will be considered as a hidden file. Hence, we’re changing the file type by doing this manipulation.

def undoit()

OSX_Mod_FileName = self.OSX_Mod_FileName

FileNameWithPath = path + '/' + FileName
os.rename(OSX_Mod_FileName, FileNameWithPath)

In this case, our application simply renaming a file with its the original file to get the file as a normal file.

Let’s understand that in Linux or MAC, you have a lot of other ways to restrict any files as it has much more granular level access control.  But, I thought, why not take a slightly different & fun way to achieve the same. After all, we’re building an Infinity War for Python verse. A little bit of fun will certainly make some sense. 🙂

5. clsProcess.py (This script will invoke any of the hide scripts, i.e. clsWinHide.py or clsOSXHide.py based on the OS platform. Hence, the name comes into the picture.)

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
###########################################
#### Written By: SATYAKI DE          ######
#### Written On: 25-Jan-2019         ######
####                                 ######
#### Objective: Based on the OS, this######
#### script calls the actual script. ######
###########################################

from clsParam import clsParam as cp

plat_det = cp.config['OS_DET']

# Based on the platform
# Application is loading subprocess
# in order to avoid library missing
# case against cross platform

if plat_det == "Windows":
    import clsWinHide as win
else:
    import clsOSXHide as osx

# End of conditional class load

class clsProcess(object):
    def __init__(self):
        self.os_det = plat_det

    def doit(self):
        try:

            os_det = self.os_det
            print("OS Info: ", os_det)

            if os_det == "Windows":
                win_doit = win.clsWinHide()
                ret_val = win_doit.doit()
            else:
                osx_doit = osx.clsOSXHide()
                ret_val = osx_doit.doit()

            return ret_val
        except Exception as e:
            x = str(e)
            print(x)

            return 1

    def undoit(self):
        try:

            os_det = self.os_det
            print("OS Info: ", os_det)

            if os_det == "Windows":
                win_doit = win.clsWinHide()
                ret_val = win_doit.undoit()
            else:
                osx_doit = osx.clsOSXHide()
                ret_val = osx_doit.undoit()

            return ret_val
        except Exception as e:
            x = str(e)
            print(x)

            return 1

Key lines to explores are as follows –

from clsParam import clsParam as cp

plat_det = cp.config['OS_DET']

# Based on the platform
# Application is loading subprocess
# in order to avoid library missing
# case against cross platform

if plat_det == "Windows":
    import clsWinHide as win
else:
    import clsOSXHide as osx

This step is very essential to run the same python scripts in both the environments, e.g. in this case like MAC & Windows.

So, based on the platform details, which the application is getting from the clsParam class, it is loading the specific class to the application. And why it is so important.

Under Windows OS, this will work if you load both the class. But, under MAC, this will fail as the first program will try to load all the libraries & it may happen that the pywin32/pypiwin32 package might not available under MAC. Anyway, you are not even using that package. So, this conditional class loading is significant.

os_det = self.os_det
print("OS Info: ", os_det)

if os_det == "Windows":
    win_doit = win.clsWinHide()
    ret_val = win_doit.doit()
else:
    osx_doit = osx.clsOSXHide()
    ret_val = osx_doit.doit()

As you can see that, based on the OS, it is invoking the correct function of that corresponding class.

6. clsEnDec.py (This script will read the credentials from a csv file & then based on the salt captured from the hidden file, it will either encrypt or decrypt the content. Hence, the name comes into the picture.)

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
###########################################
#### Written By: SATYAKI DE        ########
#### Written On: 25-Jan-2019       ########
#### Package Cryptography needs to ########
#### install in order to run this  ########
#### script.                       ########
####                               ########
#### Objective: This script will   ########
#### encrypt/decrypt based on the  ########
#### hidden supplied salt value.   ########
###########################################

import pandas as p
from cryptography.fernet import Fernet

class clsEnDec(object):

    def __init__(self, token):
        # Calculating Key
        self.token = token

    def encrypt_str(self):
        try:
            # Capturing the Salt Information
            salt = self.token
            # Fetching the content of lookup file
            df_orig = p.read_csv('Config_orig.csv', index_col=False)

            # Checking Individual Types inside the Dataframe
            cipher = Fernet(salt)

            df_orig['User'] = df_orig['User'].apply(lambda x1: cipher.encrypt(bytes(x1,'utf8')))
            df_orig['Pwd'] = df_orig['Pwd'].apply(lambda x2: cipher.encrypt(bytes(x2,'utf8')))

            # Writing to the File
            df_orig.to_csv('Encrypt_Config.csv', index=False)

            return 0
        except Exception as e:
            x = str(e)
            print(x)
            return 1

    def decrypt_str(self):
        try:
            # Capturing the Salt Information
            salt = self.token
            # Checking Individual Types inside the Dataframe
            cipher = Fernet(salt)

            # Fetching the Encrypted csv file
            df_orig = p.read_csv('Encrypt_Config.csv', index_col=False)

            df_orig['User'] = df_orig['User'].apply(lambda x1: str(cipher.decrypt(bytes(x1[2:-1],'utf8'))).replace("b'","").replace("'",""))
            df_orig['Pwd'] = df_orig['Pwd'].apply(lambda x2: str(cipher.decrypt(bytes(x2[2:-1],'utf8'))).replace("b'","").replace("'",""))

            # Writing to the file
            df_orig.to_csv('Decrypt_Config.csv', index=False)

            return 0
        except Exception as e:
            x = str(e)
            print(x)
            return 1

Key lines from this script are as follows –

def encrypt_str()

# Checking Individual Types inside the Dataframe
cipher = Fernet(salt)

df_orig['User'] = df_orig['User'].apply(lambda x1: cipher.encrypt(bytes(x1,'utf8')))
df_orig['Pwd'] = df_orig['Pwd'].apply(lambda x2: cipher.encrypt(bytes(x2,'utf8')))

So, once you captured the salt from that hidden file, the application is capturing that value over here. And, based on that both the field will be encrypted. But, note that cryptography package is required for this. And, you need to pass bytes value to work this thing. Hence, we’ve used bytes() function over here.

def decrypt_str()

cipher = Fernet(salt)

# Fetching the Encrypted csv file
df_orig = p.read_csv('Encrypt_Config.csv', index_col=False)

df_orig['User'] = df_orig['User'].apply(lambda x1: str(cipher.decrypt(bytes(x1[2:-1],'utf8'))).replace("b'","").replace("'",""))
df_orig['Pwd'] = df_orig['Pwd'].apply(lambda x2: str(cipher.decrypt(bytes(x2[2:-1],'utf8'))).replace("b'","").replace("'",""))

Again, in this step, our application is extracting the salt & then it retrieves the encrypted values of corresponding fields & applies the decryption logic on top of it. Note that, since we need to pass bytes value to get it to work. Hence, your output will be appended with (b’xxxxx’). To strip that, we’ve used the replace() functions. You can use regular expression using pattern matching as well.

7. callEnDec.py (This script will create the split csv files or final merge file after the corresponding process. However, this can be used as normal verbose debug logging as well. Hence, the name comes into the picture.)

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
###########################################
#### Written By: SATYAKI DE           #####
#### Written On: 25-Jan-2019          #####
####                                  #####
#### Objective: Main calling function #####
###########################################

import clsEnDec as ed
import clsProcess as h
from clsParam import clsParam as cp
import time as t
import pandas as p

def main():
    print("")
    print("#" * 60)
    print("Calling (Encryption/Decryption) Package!!")
    print("#" * 60)
    print("")

    # Unhiding the file
    x = h.clsProcess()
    ret_val_unhide = x.undoit()

    if ret_val_unhide == 0:
        print("Successfully Unhide the file!")
    else:
        print("Unsuccessful to Unhide the file!")

    # To See the Unhide file
    t.sleep(10)

    print("*" * 60)
    print("Proceeding with Encryption...")
    print("*" * 60)

    # Getting Salt Value from the hidden files
    # by temporarily making it available
    FileName = cp.config['FILENAME']
    df = p.read_csv(FileName, index_col=False)
    salt = str(df.iloc[0]['Token_Salt'])
    print("-" * 60)
    print("Salt: ", salt)
    print("-" * 60)

    # Calling the Encryption Method
    x = ed.clsEnDec(salt)
    ret_val = x.encrypt_str()

    if ret_val == 0:
        print("Encryption Successful!")
    else:
        print("Encryption Failure!")

    print("")
    print("*" * 60)
    print("Checking Decryption Now...")
    print("*" * 60)

    # Calling the Decryption Method
    ret_val1 = x.decrypt_str()

    if ret_val1 == 0:
        print("Decryption Successful!")
    else:
        print("Decryption Failure!")

    # Hiding the salt file
    x = h.clsProcess()
    ret_val_hide = x.doit()

    if ret_val_hide == 0:
        print("Successfully Hide the file!")
    else:
        print("Unsuccessful to Hide the file!")

    print("*" * 60)
    print("Operation Done!")
    print("*" * 60)

if __name__ == '__main__':
    main()

And, here comes the final calling methods.

The key lines that we would like to discuss –

# Getting Salt Value from the hidden files
# by temporarily making it available
FileName = cp.config['FILENAME']
df = p.read_csv(FileName, index_col=False)
salt = str(df.iloc[0]['Token_Salt'])

As I’ve shown that, we have our hidden files that contain only 1 row & 1 column. To extract the specific value we’ve used iloc with the row number as 0 along with the column name, i.e. Token_Salt.

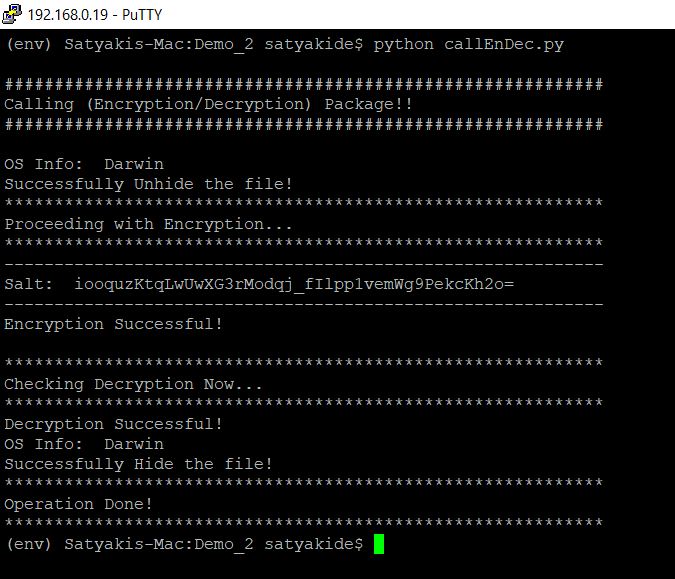
Now, let’s see how it runs –

Windows (64 bit):

Win_Run

Mac (32 bit):

MAC_Run

So, from the screenshot, we can see our desired output & you can calculate the aggregated value based on our sample provided in the previous screenshot.

Let’s check the Encrypted & Decrypted values –

Encrypted Values (Encrypt_Config.csv):

Encrypted_File

Decrypted Values (Decrypt_Config.csv):

Decrypted_File

So, finally, we’ve achieved our target.

I hope this will give you some more idea about more insights into the Python verse. Let me know – how do you think about this post.

Till then – Happy Avenging!

Pandas, Numpy, JSON & SSL (Crossover of Space Stone & Reality Stone in Python Verse)

In our last installment, we’ve shown pandas & numpy based on a specific situation. If that is our Space Stone installment of Python Verse, then this would be one approach of creating much interesting crossover of Space Stone & Reality Stone of Python verse. Yes. You are right. We’ll be discussing one requirement, where we need many of these in a single task.

Let’s dive into it!

Let’s assume that we have a source csv file which has the following data –

src_csv

Now, the requirement is – we need to use one third party web service to send JSON payload preparing with this data & send them to the 3rd party API to get the City, State & based on that we need to find the total number of item sold against each State & City.

requirement_data

Let’s look into our third-party API site  –

Please find the third-party API Link

website_api

As per the agreement with this website, any developer can test 10 calls per day free. After that, it will send your response with encrypted values, e.g. Classified. But, we don’t need more than 10 calls to test it.

Here, we’ll be dealing with the 4 python scripts. Among them, one scenario I’ve already described in my previous post. So, I’ll be just mentioning the file & post the script.

Please find the directory structure in both the OS –

directory_win_mac

1. clsLpy (This script will create the split csv files or final merge file after the corresponding process. However, this can be used as usual verbose debug logging as well. Hence, the name comes into the picture.)


 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
###########################################
#### Written By: SATYAKI DE        ########
#### Written On: 20-Jan-2019       ########
###########################################
import pandas as p
import os
import platform as pl
from clsParam import clsParam as cf

class clsL(object):
    def __init__(self):
        self.path = cf.config['PATH']

    def logr(self, Filename, Ind, df, subdir=None):
        try:
            x = p.DataFrame()
            x = df
            sd = subdir

            os_det = pl.system()

            if sd == None:
                if os_det == "Windows":
                    fullFileName = self.path + '\\' + Filename
                else:
                    fullFileName = self.path + '/' + Filename
            else:
                if os_det == "Windows":
                    fullFileName = self.path + '\\' + sd + "\\" + Filename
                else:
                    fullFileName = self.path + '/' + sd + "/" + Filename

            if Ind == 'Y':
                x.to_csv(fullFileName, index=False)

            return 0

        except Exception as e:
            y = str(e)
            print(y)
            return 3


2. clsParam.py (This script contains the parameter entries in the form of dictionary & later this can be used in all the relevant python scripts as configuration parameters.)

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
###########################################
#### Written By: SATYAKI DE        ########
#### Written On: 20-Jan-2019       ########
###########################################

import os

class clsParam(object):

    config = {
        'MAX_RETRY' : 5,
        'API_KEY' : 'HtWTVS86n8xoGXahyg1tPYH0HwngPqH2YFICzRCtlLbCtfNdya8L1UwRvH90PeMF',
        'PATH' : os.path.dirname(os.path.realpath(__file__)),
        'SUBDIR' : 'data'
    }

As you can see from this script that we’ve declared all the necessary parameters here as dictionary object & later we’ll be referring these parameters in the corresponding python scripts.

'API_KEY' : 'HtWTVS86n8xoGXahyg1tPYH0HwngPqH2YFICzRCtlLbCtfNdya8L1UwRvH90PeMF'

One crucial line, we’ll look into. API_KEY will be used while sending the JSON payload to the third-party web service. We’ll get this API_KEY from the highlighted (In Yellow) picture posted above.

3. clsWeb.py (This is the main script, which will first convert the pandas’ data frames into JSON & and send the API request as per the third party site.  It will capture the response & convert that by normalizing the data & poured it back to the data frame for further process.)


  1
  2
  3
  4
  5
  6
  7
  8
  9
 10
 11
 12
 13
 14
 15
 16
 17
 18
 19
 20
 21
 22
 23
 24
 25
 26
 27
 28
 29
 30
 31
 32
 33
 34
 35
 36
 37
 38
 39
 40
 41
 42
 43
 44
 45
 46
 47
 48
 49
 50
 51
 52
 53
 54
 55
 56
 57
 58
 59
 60
 61
 62
 63
 64
 65
 66
 67
 68
 69
 70
 71
 72
 73
 74
 75
 76
 77
 78
 79
 80
 81
 82
 83
 84
 85
 86
 87
 88
 89
 90
 91
 92
 93
 94
 95
 96
 97
 98
 99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
###########################################
#### Written By: SATYAKI DE        ########
#### Written On: 20-Jan-2019       ########
###########################################

import json
import requests
import datetime
import time
import ssl
from urllib.request import urlopen
import pandas as p
import numpy as np
import os
import gc
from clsParam import clsParam as cp

class clsWeb(object):
    def __init__(self, payload, format, unit):
        self.payload = payload
        self.path = cp.config['PATH']
        # To disable logging info
        self.max_retries = cp.config['MAX_RETRY']
        self.api_key = cp.config['API_KEY']
        self.unit = unit
        self.format =format

    def get_response(self):
        # Assigning Logging Info
        max_retries = self.max_retries
        api_key = self.api_key
        unit = self.unit
        format = self.format
        df_conv = p.DataFrame()
        cnt = 0

        try:
            # Bypassing SSL Authentication
            try:
                _create_unverified_https_context = ssl._create_unverified_context
            except AttributeError:
                # Legacy python that doesn't verify HTTPS certificates by default
                pass
            else:
                # Handle target environment that doesn't support HTTPS verification
                ssl._create_default_https_context = _create_unverified_https_context

            # Capturing the payload
            data_df = self.payload
            temp_df = data_df[['zipcode']]

            list_of_rec = temp_df['zipcode'].values.tolist()

            print(list_of_rec)

            for i in list_of_rec:
                zip = i

                # Providing the url
                url_part = 'http://www.zipcodeapi.com/rest/'
                url = url_part + api_key + '/' + 'info.' + format + '/' + str(zip) + '/' + unit

                headers = {"Content-type": "application/json"}
                param = headers

                var1 = datetime.datetime.now().strftime("%H:%M:%S")
                print('Json Fetch Start Time:', var1)

                retries = 1
                success = False

                while not success:
                    # Getting response from web service
                    response = requests.get(url, params=param, verify=False)
                    # print("Complete Error:: ", str(response.status_code))
                    # print("Error First::", str(response.status_code)[:1])

                    if str(response.status_code)[:1] == '2':
                        # response = s.post(url, params=param, json=json_data, verify=False)
                        success=True
                    else:
                        wait = retries * 2
                        print("Retry fails! Waiting " + str(wait) + " seconds and retrying.")
                        time.sleep(wait)
                        retries += 1

                    # Checking Maximum Retries
                    if retries == max_retries:
                        success=True
                        raise ValueError

                # print(response.text)

                var2 = datetime.datetime.now().strftime("%H:%M:%S")
                print('Json Fetch End Time:', var2)

                print("-" * 90)

                # Capturing the response json from Web Service
                df_response_json = response.text
                string_to_json = json.loads(df_response_json)

                # Converting the response json to Dataframe
                # df_Int_Rec = p.read_json(string_to_json, orient='records')
                df_Int_Rec = p.io.json.json_normalize(string_to_json)
                df_Int_Rec.columns = df_Int_Rec.columns.map(lambda x: x.split(".")[-1])

                if cnt == 0:
                    df_conv = df_Int_Rec
                else:
                    d_frames = [df_conv, df_Int_Rec]
                    df_conv = p.concat(d_frames)

                cnt += 1

            # Deleting temporary dataframes & Releasing memories
            del [[df_Int_Rec]]
            gc.collect()

            # Resetting the Index Value
            df_conv.reset_index(drop=True, inplace=True)

            # Merging two data side ways maintaining the orders
            df_add = p.concat([data_df, df_conv], axis=1)

            del [[df_conv]]
            gc.collect()

            # Dropping unwanted column
            df_add.drop(['acceptable_city_names'], axis=1, inplace=True)

            return df_add

        except ValueError as v:
            print(response.text)
            x = str(v)
            print(x)

            # Return Empty Dataframe
            df = p.DataFrame()
            return df

        except Exception as e:
            print(response.text)
            x = str(e)
            print(x)

            # Return Empty Dataframe
            df = p.DataFrame()
            return df

Let’s look at the key lines to discuss –

def __init__(self, payload, format, unit):

    self.payload = payload
    self.path = cp.config['PATH']

    # To disable logging info
    self.max_retries = cp.config['MAX_RETRY']
    self.api_key = cp.config['API_KEY']
    self.unit = unit
    self.format = format

The first block will be instantiated as soon as you are invoking the class. Note that, we’ve used our parameter class python script here as cp & then we’re referring the corresponding elements as & when requires. Other parameters will be captured from the invoking script, which we’ll be discussed later in this post.

# Bypassing SSL Authentication
try:
    _create_unverified_https_context = ssl._create_unverified_context
except AttributeError:
    # Legacy python that doesn't verify HTTPS certificates by default
    pass
else:
    # Handle target environment that doesn't support HTTPS verification
    ssl._create_default_https_context = _create_unverified_https_context

Sometimes, Your Firewall or Proxy might block your web service request due to a specific certificate error. This snippet will bypass that authentication. However, it is always advised to use proper SSL certification in the Production environment.

# Capturing the payload
data_df = self.payload
temp_df = data_df[['zipcode']]

list_of_rec = temp_df['zipcode'].values.tolist()

In this snippet, we’re capturing the zip code from our source data frame & converting them into a list & this would be our candidate to pass the data as part of our JSON payload.

for i in list_of_rec:
    zip = i

    # Providing the url
    url_part = 'http://www.zipcodeapi.com/rest/'
    url = url_part + api_key + '/' + 'info.' + format + '/' + str(zip) + '/' + unit

    headers = {"Content-type": "application/json"}
    param = headers

Once, we’ve extracted our zip codes, we’re passing it one-by-one & forming our JSON with header & data.

retries = 1
success = False

while not success:
    # Getting response from web service
    response = requests.get(url, params=param, verify=False)
    # print("Complete Error:: ", str(response.status_code))
    # print("Error First::", str(response.status_code)[:1])

    if str(response.status_code)[:1] == '2':
        # response = s.post(url, params=param, json=json_data, verify=False)
        success=True
    else:
        wait = retries * 2
        print("Retry fails! Waiting " + str(wait) + " seconds and retrying.")
        time.sleep(wait)
        retries += 1

    # Checking Maximum Retries
    if retries == max_retries:
        success=True
        raise ValueError

In this section, we’re posting our JSON application & waiting for the response from the third-party API. If we receive the success response (200), we will proceed with the next zip code. However, if we didn’t receive the success response, we’ll retry the post option again until or unless it reaches the maximum limits. In case, if the application still waiting for a valid answer even after the maximum limit, it will exit from the loop & raise an error to the main application.

# Capturing the response json from Web Service
df_response_json = response.text
string_to_json = json.loads(df_response_json)

# Converting the response json to Dataframe
# df_Int_Rec = p.read_json(string_to_json, orient='records')
df_Int_Rec = p.io.json.json_normalize(string_to_json)
df_Int_Rec.columns = df_Int_Rec.columns.map(lambda x: x.split(".")[-1])

This snippet will extract the desired response from the API & convert that back to the Pandas data frame. Last two lines, it is normalizing the data that it has received from the API for further process. This is critical steps as these steps will lead to extract City & State from our API response.

# Merging two data side ways maintaining the orders
df_add = p.concat([data_df, df_conv], axis=1)

Once, we’ll have structured data – we can merge it back to our source data frame for our next step.

4. callWebservice.py (This script will call the API script & also process the data to create an aggregate report for our task.)

  1
  2
  3
  4
  5
  6
  7
  8
  9
 10
 11
 12
 13
 14
 15
 16
 17
 18
 19
 20
 21
 22
 23
 24
 25
 26
 27
 28
 29
 30
 31
 32
 33
 34
 35
 36
 37
 38
 39
 40
 41
 42
 43
 44
 45
 46
 47
 48
 49
 50
 51
 52
 53
 54
 55
 56
 57
 58
 59
 60
 61
 62
 63
 64
 65
 66
 67
 68
 69
 70
 71
 72
 73
 74
 75
 76
 77
 78
 79
 80
 81
 82
 83
 84
 85
 86
 87
 88
 89
 90
 91
 92
 93
 94
 95
 96
 97
 98
 99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
#####################################################
### Objective: Purpose of this Library is to call ###
### the Web Service method to capture the city,   ###
### & the state as a json response & update them  ###
### in the dataframe & finally produce the summary###
### of Total Sales & Item Counts based on the City###
### & the State.                                  ###
###                                               ###
### Arguments are as follows:                     ###
### Mentioned the Exception Part. First time dry  ###
### run the program without providing any args.   ###
### It will show all the mandatory params.        ###
###                                               ###
#####################################################
#####################################################
#### Written By: SATYAKI DE                       ###
#### Written On: 20-Jan-2019                      ###
#####################################################

import clsWeb as cw
import sys
import pandas as p
import os
import platform as pl
import clsLog as log
import datetime
import numpy as np
from clsParam import clsParam as cp

# Disbling Warnings
def warn(*args, **kwargs):
    pass
import warnings
warnings.warn = warn

def main():
    print("Calling the custom Package..")

    try:
        if len(sys.argv) == 4:
            inputFile = str(sys.argv[1])
            format = str(sys.argv[2])
            unit = str(sys.argv[3])
        else:
            raise Exception

        # Checking whether the format contains
        # allowable choices or not
        if (format == 'JSON'):
            format = 'json'
        elif (format == 'CSV'):
            format = 'csv'
        elif (format == 'XML'):
            format = 'xml'
        else:
            raise Exception

        # Checking whether the format contains
        # allowable choices or not
        if (unit == 'DEGREE'):
            unit = 'degree'
        elif (unit == 'RADIANS'):
            unit = 'radians'
        else:
            raise Exception

        print("*" * 170)
        print("Reading from " + str(inputFile))
        print("*" * 170)

        # Initiating Logging Instances
        clog = log.clsLog()

        path = cp.config['PATH']
        subdir = cp.config['SUBDIR']

        os_det = pl.system()

        if os_det == "Windows":
            src_path = path + '\\' + 'data\\'
        else:
            src_path = path + '/' + 'data/'

        # Reading source data csv file
        df_Payload = p.read_csv(src_path+inputFile, index_col=False, skipinitialspace=True)

        x = cw.clsWeb(df_Payload, format, unit)
        retDf = x.get_response()

        # Total Number of rows fetched
        count_row = retDf.shape[0]

        if count_row == 0:
            print("Data Processing Issue!")
        else:
            print("Writing to file -> (" + str(inputFile) + "_modified.csv) Status: Success")

        FileName, FileExtn = inputFile.split(".")

        # Writing to the file
        clog.logr(FileName + '_modified.' + FileExtn, 'Y', retDf, subdir)
        print("*" * 170)

        # Performing group by operation to get the desired result
        # State & City-wise total Sales & Item Sales
        df_src = p.DataFrame()
        df_src = retDf[['city', 'state', 'total', 'item_count']]

        # Converting values to Integer
        df_src['city_1'] = retDf['city'].astype(str)
        df_src['state_1'] = retDf['state'].astype(str)
        df_src['total_1'] = retDf['total'].astype(int)
        df_src['item_count_1'] = retDf['item_count'].astype(int)

        # Dropping the old Dtype Columns
        df_src.drop(['city'], axis=1, inplace=True)
        df_src.drop(['state'], axis=1, inplace=True)
        df_src.drop(['total'], axis=1, inplace=True)
        df_src.drop(['item_count'], axis=1, inplace=True)

        # Renaming the new columns to as per Old Column Name
        df_src.rename(columns={'city_1': 'city'}, inplace=True)
        df_src.rename(columns={'state_1': 'state'}, inplace=True)
        df_src.rename(columns={'total_1': 'total'}, inplace=True)
        df_src.rename(columns={'item_count_1': 'item_count'}, inplace=True)

        # Performing Group By Operation
        grouped = df_src.groupby(['state', 'city'])
        res_1 = grouped.aggregate(np.sum)

        print("DF:")
        print(res_1)

        FileName1 = 'StateCityWiseReport'
        # Handling Multiple source files
        var = datetime.datetime.now().strftime(".%H.%M.%S")
        print('Target File Extension will contain the following:: ', var)

        # Writing to the file
        clog.logr(FileName1 + var + '.' + FileExtn, 'Y', df_src, subdir)

        print("*" * 170)
        print("Operation done for " + str(inputFile) + "!")
        print("*" * 170)
    except Exception as e:
        x = str(e)
        print(x)
        print("*" * 170)
        print('Current order would be - <' + str(sys.argv[0]) + '> <Csv File Name> <JSON/CSV/XML> <DEGREE/RADIANS>')
        print('Make sure last two params should be in CAPS only!')
        print("*" * 170)

if __name__ == "__main__":
    main()

Let’s look at some vital code snippet in this main script –

# Reading source data csv file
df_Payload = p.read_csv(src_path+inputFile, index_col=False, skipinitialspace=True)

x = cw.clsWeb(df_Payload, format, unit)
retDf = x.get_response()

In this snippet, we’re getting our data from our source csv & then calling our leading Web API service to get the State & City information.

# Converting values to Integer
df_src['city_1'] = retDf['city'].astype(str)
df_src['state_1'] = retDf['state'].astype(str)
df_src['total_1'] = retDf['total'].astype(int)
df_src['item_count_1'] = retDf['item_count'].astype(int)

Converting individual data type to appropriate data types. In Pandas, it is always advisable to change the data type of frames to avoid unforeseen scenarios.

# Dropping the old Dtype Columns
df_src.drop(['city'], axis=1, inplace=True)
df_src.drop(['state'], axis=1, inplace=True)
df_src.drop(['total'], axis=1, inplace=True)
df_src.drop(['item_count'], axis=1, inplace=True)

# Renaming the new columns to as per Old Column Name
df_src.rename(columns={'city_1': 'city'}, inplace=True)
df_src.rename(columns={'state_1': 'state'}, inplace=True)
df_src.rename(columns={'total_1': 'total'}, inplace=True)
df_src.rename(columns={'item_count_1': 'item_count'}, inplace=True)

Now, dropping the old columns & renaming the new columns to get the same column with correct data types. I personally like this way as it is an immaculate way to do this task. You can also debug it easily.

# Performing Group By Operation
grouped = df_src.groupby(['state', 'city'])
res_1 = grouped.aggregate(np.sum)

And, finally, using Pandas group-by method we’re aggregating the groups & then using numpy to generate the same against each group.

Please check the first consolidated output –

consolidate_data_from_web_api

From this screenshot, you can see how we have the desired intermediate data of City & State to proceed for the next level.

Let’s see how it runs –

Windows (64 bit):

run_windows

Mac (32 bit):

run_mac

So, from the screenshot, we can see our desired output & you can calculate the aggregated value based on our sample provided in the previous screenshot.

Let’s check how the data directory looks like after run –

Windows:

final_data_windows

MAC:

final_data_mac

So, finally, we’ve achieved our target.

I hope this will give you some more idea about more insights into the Python verse. Let me know – how do you think about this post.

Till then – Happy Avenging!

Python Verse – Universe of Avengers in Computer Language World!

The last couple of years, I’ve been working on various technologies. And, one of the interesting languages that I came across is Python. It is extremely flexible for developers to learn & rapidly develop with very few lines of code compared to the other languages. There are major versions of python that I worked with. Among them, python 2.7 & current python 3.7.1 are very popular to developers & my personal favorite.

There are many useful packages that are available to reduce the burden of the developers. Among them, packages like “pandas”, “numpy”, “json”, “AES”, “threading” etc. are extremely useful & one can do lot’s of work with it.

I personally prefer Ubuntu or Mac version of python. However, I’ve worked on Windows version as well or developed python based framework & application, which works in all the major operating systems. If you take care few things from the beginning, then you don’t have to make much more changes of your python application in order to work in all the major operating systems. 🙂

To me, Python Universe is nothing shorter than Marvel’s Universe of Avengers. In order to beat Supreme Villain Thanos (That Challenging & Complex Product with extremely tight timeline), you got to have 6 infinity stones to defeat him.

  1. Space Stone ( Pandas & Numpy )
  2. Reality Stone ( Json, SSL & Encryption/Decryption )
  3. Power Stone ( Multi-Threading/Multi-Processing )
  4. Mind Stone ( OS, Database, Directories & Files )
  5. Soul Stone ( Logging & Exception )
  6. Time Stone ( Cloud Interaction & Framework )

I’ll release a series of python based post in coming days, which might be useful for many peers or information seeker. Hopefully, this installment is a beginning & please follow my post. I hope, very soon you will get many such useful posts.

You get the latest version of Python from the official site given below –

Python Link (3.7.1)

Make sure you must install pip package along with python. I’m not going in details of how one should install python in either of Windows/Mac or Linux.

Just showing you how to install individual python packages.

Windows:

pip install pandas

Linux/Mac:

sudo python3.7 -m pip install pandas

From the second example, you can see that you can install packages to specific python version in case if you have multiple versions of python.

Note that: There might be slight variation based on different versions of Linux. Make sure you are using the correct syntax as per your flavor.

You can get plenty of good sites, where the detailed step-by-step process shared for each operating system.

Till then – Happy Avenging!

Oracle procedure using Java

Today, i’m going to discuss another powerful feature of Oracle. That is embedding your Java code inside Oracle Procedures. This gives a lot of flexibility & power to Oracle and certainly you can do plenty of things which generally are very difficult to implement directly.

In this purpose i cannot restrict myself to explanation made by  Bulusu Lakshman and that is –

From Oracle 9i a new environments are taking place where Java and PL/SQL can interact as two major database languages. There are many advantages to using both languages –

PL/SQL Advantage:

  • Intensive Database Access – It is faster than Java.
  • Oracle Specific Functionality that has no equivalent in Java such as using dbms_lock & dbms_alert.
  • Using the same data types and language construct as SQL providing seamless access to the database.

JAVA Advantage:

  • Automatic garbage collection, polymorphism, inheritance, multi-threading
  • Access to system resources outside of the database such as OS commands, files, sockets
  • Functionality not avialable in PL/SQL such as OS Commands, fine-grained security policies, image generation, easy sending of e-mails with attachements using JavaMail.

But, i dis-agree with him in case of fine grained security policies as Oracle has drastically improves it and introduces security policies like – VPDB (Virtual Private Database) & Database Vault. Anyway, we’ll discuss these topics on some other day.

For better understanding i’m follow categories and we will explore them one by one. Hope you get some basic idea on this powerful feature by Oracle.

Before proceed we have to know the basics of the main ingredients called dbms_java .

We’ve to prepare the environment.

In Sys,

sys@ORCL>select * from v$version;

BANNER
--------------------------------------------------------------------------------
Oracle Database 11g Enterprise Edition Release 11.1.0.6.0 - Production
PL/SQL Release 11.1.0.6.0 - Production
CORE 11.1.0.6.0 Production
TNS for 32-bit Windows: Version 11.1.0.6.0 - Production
NLSRTL Version 11.1.0.6.0 - Production

Elapsed: 00:00:00.00
sys@ORCL>
sys@ORCL>
sys@ORCL>exec dbms_java.grant_permission('SCOTT','SYS:java.lang.RuntimePermission','writeFileDescriptor','');

PL/SQL procedure successfully completed.

Elapsed: 00:00:53.54
sys@ORCL>
sys@ORCL>exec dbms_java.grant_permission('SCOTT','SYS:java.lang.RuntimePermission','readFileDescriptor','');

PL/SQL procedure successfully completed.

Elapsed: 00:00:00.08
sys@ORCL>
sys@ORCL>exec dbms_java.grant_permission('SCOTT','SYS:java.io.FilePermission','D:\Java_Output\*.*','read,write,execute,delete');

PL/SQL procedure successfully completed.

Elapsed: 00:00:00.08
sys@ORCL>

Let’s concentrate on our test cases.

In Scott,

Type: 1

scott@ORCL>select * from v$version;

BANNER
--------------------------------------------------------------------------------
Oracle Database 11g Enterprise Edition Release 11.1.0.6.0 - Production
PL/SQL Release 11.1.0.6.0 - Production
CORE 11.1.0.6.0 Production
TNS for 32-bit Windows: Version 11.1.0.6.0 - Production
NLSRTL Version 11.1.0.6.0 - Production

Elapsed: 00:00:02.77
scott@ORCL>
scott@ORCL>
scott@ORCL>create or replace and compile java source named "Print_Hello"
2 as
3 import java.io.*;
4 public class Print_Hello
5 {
6 public static void dislay()
7 {
8 System.out.println("Hello World...... In Java Through Oracle....... ");
9 }
10 };
11 /

Java created.

Elapsed: 00:00:44.17
scott@ORCL>
scott@ORCL>
scott@ORCL>create or replace procedure java_print
2 as
3 language java name 'Print_Hello.dislay()';
4 /

Procedure created.

Elapsed: 00:00:01.39
scott@ORCL>
scott@ORCL>call dbms_java.set_output(1000000);

Call completed.

Elapsed: 00:00:00.34
scott@ORCL>
scott@ORCL>set serveroutput on size 1000000;
scott@ORCL>
scott@ORCL>exec java_print;
Hello World...... In Java Through Oracle.......

PL/SQL procedure successfully completed.

Elapsed: 00:00:00.22
scott@ORCL>

Type: 2 (Returning Value from JAVA)

scott@ORCL>
scott@ORCL>select * from v$version;

BANNER
--------------------------------------------------------------------------------
Oracle Database 11g Enterprise Edition Release 11.1.0.6.0 - Production
PL/SQL Release 11.1.0.6.0 - Production
CORE 11.1.0.6.0 Production
TNS for 32-bit Windows: Version 11.1.0.6.0 - Production
NLSRTL Version 11.1.0.6.0 - Production

Elapsed: 00:00:00.13
scott@ORCL>
scott@ORCL>
scott@ORCL>create or replace and resolve java source named "ReturnVal"
2 as
3 import java.io.*;
4
5 public class ReturnVal extends Object
6 {
7 public static String Display()
8 throws IOException
9 {
10 return "Hello World";
11 }
12 };
13 /

Java created.

Elapsed: 00:00:00.22
scott@ORCL>
scott@ORCL>
scott@ORCL>create or replace function ReturnVal
2 return varchar2
3 is
4 language java
5 name 'ReturnVal.Display() return String';
6 /

Function created.

Elapsed: 00:00:00.00
scott@ORCL>
scott@ORCL>
scott@ORCL>call dbms_java.set_output(1000000);

Call completed.

Elapsed: 00:00:00.00
scott@ORCL>
scott@ORCL>
scott@ORCL>column ReturnVal format a15
scott@ORCL>
scott@ORCL>
scott@ORCL>
scott@ORCL>
scott@ORCL>select ReturnVal from dual;

RETURNVAL
---------------
Hello World

Elapsed: 00:00:00.12
scott@ORCL>
scott@ORCL>

So, you can return the value from the compiled Java source, too.

Type: 3 (Reading console value into JAVA)

scott@ORCL>ed
Wrote file C:\OracleSpoolBuf\BUF.SQL

1 create or replace java source named "ConsoleRead"
2 as
3 import java.io.*;
4 class ConsoleRead
5 {
6 public static void RDisplay(String Det)
7 {
8 String dd = Det;
9 System.out.println("Value Passed In Java Is: " + dd);
10 System.out.println("Exiting from the Java .....");
11 }
12* };
13 /

Java created.

scott@ORCL>
scott@ORCL>
scott@ORCL>create or replace procedure java_UserInput(InputStr in varchar2)
2 as
3 language java
4 name 'ConsoleRead.RDisplay(java.lang.String)';
5 /

Procedure created.

scott@ORCL>

scott@ORCL>
scott@ORCL>call dbms_java.set_output(100000);

Call completed.

scott@ORCL>
scott@ORCL>
scott@ORCL>set serveroutput on size 100000
scott@ORCL>
scott@ORCL>exec java_UserInput('Satyaki');
Value Passed In Java Is: Satyaki
Exiting from the Java .....

PL/SQL procedure successfully completed.

scott@ORCL>

Type: 4 (Reading file from OS directory using JAVA) 

scott@ORCL>ed
Wrote file C:\OracleSpoolBuf\BUF.SQL

1 create or replace java source named "ReadTextFile"
2 as
3 import java.io.*;
4 class ReadTextFile
5 {
6 public static void Process(String FileName) throws IOException
7 {
8 int i;
9 FileInputStream fin;
10 try
11 {
12 fin = new FileInputStream(FileName);
13 }
14 catch(FileNotFoundException e)
15 {
16 System.out.println("File Not Found....");
17 return;
18 }
19 catch(ArrayIndexOutOfBoundsException e)
20 {
21 System.out.println("Usage: showFile File");
22 return;
23 }
24 do
25 {
26 i = fin.read();
27 if(i != 1)
28 System.out.println((char) i);
29 }while(i != 1);
30 fin.close();
31 }
32* };
33 /

Java created.

scott@ORCL>
scott@ORCL>create or replace procedure Java_ReadTextFile(FileNameWithPath in varchar2)
2 as
3 language java
4 name 'ReadTextFile.Process(java.lang.String)';
5 /

Procedure created.

scott@ORCL>
scott@ORCL>
scott@ORCL>call dbms_java.set_output(100000);

Call completed.

scott@ORCL>
scott@ORCL>
scott@ORCL>exec Java_ReadTextFile('D:\Java_Output\Trial.txt');

Type: 4 (Writing file in  OS directory using JAVA)


In Scott,

scott@ORCL>
scott@ORCL>create or replace java source named "DynWriteTextFile"
2 as
3 import java.io.*;
4 class DynWriteTextFile
5 {
6 public static void proc(String ctent,String FlNameWithPath) throws IOException
7 {
8 int i,j;
9 String FileNm = FlNameWithPath;
10 RandomAccessFile rFile;
11
12 try
13 {
14 rFile = new RandomAccessFile(FileNm,"rw");
15 }
16 catch(FileNotFoundException e)
17 {
18 System.out.println("Error Writing Output File....");
19 return;
20 }
21
22 try
23 {
24 int ch;
25
26 System.out.println("Processing starts...");
27
28 ch = ctent.length();
29
30 rFile.seek(rFile.length());
31 for(int k=0; k<ch; k=k+ctent.length())
32 {
33 rFile.writeBytes(ctent);
34 }
35 }
36 catch(IOException e)
37 {
38 System.out.println("File Error....");
39 }
40 finally
41 {
42 try
43 {
44 System.out.println("Successfully file generated....");
45 rFile.close();
46 }
47 catch(IOException oe)
48 {
49 System.out.println("Exception in the catch block of finally is: " +oe);
50 System.exit(0);
51 }
52 }
53 }
54 };
55 /

Java created.

Elapsed: 00:00:00.17
scott@ORCL>
scott@ORCL>
scott@ORCL>create or replace procedure JavaDyn_WriteTextFile(para in varchar2,FileNameWithPath in varchar2)
2 as
3 language JAVA
4 name 'DynWriteTextFile.proc(java.lang.String, java.lang.String)';
5 /

Procedure created.

Elapsed: 00:00:00.15
scott@ORCL>

In Sys,

BANNER
--------------------------------------------------------------------------------
Oracle Database 11g Enterprise Edition Release 11.1.0.6.0 - Production
PL/SQL Release 11.1.0.6.0 - Production
CORE 11.1.0.6.0 Production
TNS for 32-bit Windows: Version 11.1.0.6.0 - Production
NLSRTL Version 11.1.0.6.0 - Production

sys@ORCL>set timi on
sys@ORCL>
sys@ORCL>
sys@ORCL>create or replace public synonym dbms_dwrite_file for scott.JavaDyn_WriteTextFile;

Synonym created.

Elapsed: 00:00:00.08
sys@ORCL>
sys@ORCL>grant execute on dbms_dwrite_file to scott;

Grant succeeded.

Elapsed: 00:00:00.18
sys@ORCL>
 
In Scott,  

scott@ORCL>
scott@ORCL>create or replace procedure DWrite_Content(dt in date,FileNmWithPath in varchar2)
2 is
3 cursor c1
4 is
5 select empno,ename,sal
6 from emp
7 where hiredate = dt;
8 r1 c1%rowtype;
9
10 str varchar2(500);
11 begin
12 str:= replace(FileNmWithPath,'\','\\');
13 dbms_dwrite_file('Employee No'||' '||'First Name'||' '||'Salary',str);
14 dbms_dwrite_file(chr(10),str);
15 dbms_dwrite_file('---------------------------------------------------',str);
16 dbms_dwrite_file(chr(10),str);
17 for r1 in c1
18 loop
19 dbms_dwrite_file(r1.empno||' '||r1.ename||' '||r1.sal,str);
20 dbms_dwrite_file(chr(10),str);
21 end loop;
22 exception
23 when others then
24 dbms_output.put_line(sqlerrm);
25 end;
26 /

Procedure created.

Elapsed: 00:00:00.43
scott@ORCL>
scott@ORCL>
scott@ORCL>call dbms_java.set_output(100000);

Call completed.

Elapsed: 00:00:00.02
scott@ORCL>
scott@ORCL>exec DWrite_Content(to_date('21-JUN-1999','DD-MON-YYYY'),'D:\Java_Output\satyaki.txt');
Processing starts...
Successfully file generated....

PL/SQL procedure successfully completed.
 
Hope, this thread will give you some basic idea about using your Java code with Oracle PL/SQL.
I’ll discuss another topic very soon. Till then – Keep following. 😉
Regards.


How to store data from XML to Tables

In the previous post we have discussed about generating an XML file using Oracle SQL XML functions. Today we will do that in reverse manner. That means we will load the data generated by that query in the database tables.

At the end of this post (Which is a continue of the previous post) – you will be successfully generate an XML file from Oracle Tables & also able to load the data from XML on that same structured tables. So, that will complete the full life cycle of XML in oracle(Obviously concentrate on some basics).

Lets see –

Our main ingredients for this class – is the XML file named – emp_oracle.xml

And, it looks like –


200
<
First>Whalen</First>
4400
1987-09-17


201
<
First>Billy</First>
4500
1985-06-10


202
<
First>Bireswar</First>
9000
1978-06-10


We need to create one Oracle Directories to map with the Operating System directories in the following manner ->

sys@ORCL>
sys@ORCL>select * from v$version;

BANNER
----------------------------------------------------------------------------
Oracle Database 11g Enterprise Edition Release 11.1.0.6.0 - Production
PL/SQL Release 11.1.0.6.0 - Production
CORE 11.1.0.6.0 Production
TNS for 32-bit Windows: Version 11.1.0.6.0 - Production
NLSRTL Version 11.1.0.6.0 - Production

Elapsed: 00:00:00.00
sys@ORCL>
sys@ORCL>
sys@ORCL>CREATE OR REPLACE DIRECTORY SATY_DIR AS 'D:\XML_Output'
2 /

Directory created.

Elapsed: 00:00:00.23
sys@ORCL>
sys@ORCL>GRANT READ, WRITE ON DIRECTORY SATY_DIR TO SCOTT, HR;

Grant succeeded.

Elapsed: 00:00:00.08
sys@ORCL>

Once you have created the directory successfully and give the proper privileges to the users like Scott or Hr – you have completed one important component of today’s test. Still we are far to go. Now the second part is –

scott@ORCL>
scott@ORCL>select * from v$version;

BANNER
--------------------------------------------------------------------------------
Oracle Database 11g Enterprise Edition Release 11.1.0.6.0 - Production
PL/SQL Release 11.1.0.6.0 - Production
CORE 11.1.0.6.0 Production
TNS for 32-bit Windows: Version 11.1.0.6.0 - Production
NLSRTL Version 11.1.0.6.0 - Production

Elapsed: 00:00:00.00
scott@ORCL>
scott@ORCL>
scott@ORCL>CREATE TABLE t
2 (
3 serialNo NUMBER(10),
4 fileName VARCHAR2(100),
5 xml XMLTYPE,
6 constraints pk_serialNo primary key(serialNo)
7 );

Table created.

Elapsed: 00:00:04.13
scott@ORCL>
scott@ORCL>
scott@ORCL>CREATE SEQUENCE x_seq
2 START WITH 1
3 INCREMENT BY 1;

Sequence created.

Elapsed: 00:00:00.31
scott@ORCL>
scott@ORCL>CREATE OR REPLACE PROCEDURE load_xml(
2 p_dir IN VARCHAR2,
3 p_filename IN VARCHAR2
4 )
5 IS
6 l_bfile BFILE := BFILENAME(p_dir, p_filename);
7 l_clob CLOB;
8 BEGIN
9 DBMS_LOB.createtemporary (l_clob, TRUE);
10
11 DBMS_LOB.fileopen(l_bfile, DBMS_LOB.file_readonly);
12 DBMS_LOB.loadfromfile(l_clob, l_bfile, DBMS_LOB.getlength(l_bfile));
13 DBMS_LOB.fileclose(l_bfile);
14
15 INSERT INTO t(
16 serialNo,
17 fileName,
18 xml
19 )
20 VALUES (
21 x_seq.NEXTVAL,
22 p_filename,
23 XMLTYPE.createXML(l_clob)
24 );
25
26 COMMIT;
27
28 DBMS_LOB.freetemporary(l_clob);
29 END;
30 /

Procedure created.

Elapsed: 00:00:00.88
scott@ORCL>
scott@ORCL>EXEC load_xml(p_dir => 'SATY_DIR', p_filename => 'emp_oracle.xml');

PL/SQL procedure successfully completed.

Elapsed: 00:00:00.16
scott@ORCL>
scott@ORCL>set long 5000
scott@ORCL>
scott@ORCL>set pagesize 0
scott@ORCL>
scott@ORCL>select xml from t;


200
Whalen
4400
1987-09-17


201
Billy
4500
1985-06-10


202
Bireswar
9000
1978-06-10


Elapsed: 00:00:00.10
scott@ORCL>

Ok. So, we’ve initially load the data into the temp table t. But, we need to load the data from this temp table t to our target table revive_xml which will look like –

scott@ORCL>create table revive_xml
2 (
3 rev_emp_id number(4),
4 rev_f_name varchar2(40),
5 rev_salary number(10,2),
6 rev_jn_dt date,
7 constraints pk_rev_emp_id primary key(rev_emp_id)
8 );

Table created.

Elapsed: 00:00:00.40
scott@ORCL>

Ok. So, we have done another important part of our job. Let’s concentrate on our final mission –

scott@ORCL>insert into revive_xml(
2 rev_emp_id,
3 rev_f_name,
4 rev_salary,
5 rev_jn_dt
6 )
7 select cast(t1.EmployeeId as number(4)) EmployeeId,
8 t2.FirstName,
9 cast(t3.Salary as number(10,2)) Salary,
10 to_date(t4.JoiningDt,'YYYY-MM-DD') JoiningDt
11 from (
12 select rownum rn1,
13 extractValue(value(EmployeeId),'/Emp/Employee_ID') EmployeeId
14 from t,
15 table(xmlsequence(extract(xml, '/EmployeeList/Emp'))) EmployeeId
16 ) t1,
17 (
18 select rownum rn2,
19 extractValue(value(FirstName),'/Emp/First') FirstName
20 from t,
21 table(xmlsequence(extract(xml, '/EmployeeList/Emp'))) FirstName
22 ) t2,
23 (
24 select rownum rn3,
25 extractValue(value(Salary),'/Emp/Sal') Salary
26 from t,
27 table(xmlsequence(extract(xml, '/EmployeeList/Emp'))) Salary
28 ) t3,
29 (
30 select rownum rn4,
31 extractValue(value(HireDate),'/Emp/HireDate') JoiningDt
32 from t,
33 table(xmlsequence(extract(xml, '/EmployeeList/Emp'))) HireDate
34 ) t4
35 where t1.rn1 = t2.rn2
36 and t1.rn1 = t3.rn3
37 and t1.rn1 = t4.rn4;

3 rows created.

Elapsed: 00:00:00.16
scott@ORCL>
scott@ORCL>commit;

Commit complete.

Elapsed: 00:00:00.22
scott@ORCL>
scott@ORCL>
scott@ORCL>select * from revive_xml;

REV_EMP_ID REV_F_NAME REV_SALARY REV_JN_DT
---------- ---------------------------------------- ---------- ---------
200 Whalen 4400 17-SEP-87
201 Billy 4500 10-JUN-85
202 Bireswar 9000 10-JUN-78

scott@ORCL>

So, you have done it finally.

You can do it another way but that is limited to single record parsing –

scott@ORCL>with t
2 as (
3 select xmlType('
4
5
6 200
7 Whalen
8 4400
9 1987-09-17
10
11 ') xml from dual
12 )
13 SELECT rownum rn,
14 a.EmployeeId,
15 a.FirstName,
16 a.Salary,
17 a.JoiningDt
18 FROM t,
19 XMLTABLE('/EmployeeList'
20 PASSING t.xml
21 COLUMNS
22 EmployeeId varchar2(10) PATH '/EmployeeList/Emp/Employee_ID',
23 FirstName varchar2(20) PATH '/EmployeeList/Emp/First',
24 Salary number(10) PATH '/EmployeeList/Emp/Sal',
25 JoiningDt date PATH '/EmployeeList/Emp/HireDate'
26 ) a;

RN EMPLOYEEID FIRSTNAME SALARY JOININGDT
---------- ---------- -------------------- ---------- ---------
1 200 Whalen 4400 17-SEP-87

scott@ORCL>
scott@ORCL>

Hope this will solve your purpose.

Also you can refer to the following XML In Oracle link.

Regards.