This site mainly deals with various use cases demonstrated using Python, Data Science, Cloud basics, SQL Server, Oracle, Teradata along with SQL & their implementation. Expecting yours active participation & time. This blog can be access from your TP, Tablet & mobile also. Please provide your feedback.
Welcome back! As you have now understood our objectives for the new initiative that we have explored in the other two posts, this post will show the actual implementation of the framework in a simple step-by-step process. But before that, why don’t you see the final LLM environment and the response from it?
But before that, here are the previous two posts in case you directly land on this page –
6. Download the preconverted model directly to the external SSD
I would use the project’s currently recommended preconverted GLM-5.2 model instead of downloading the approximately 756 GB FP8 source and converting it unless you specifically want to experiment with quantization.
Colibrì currently recommends:
mastouri/GLM-5.2-colibri-int4-g64-with-int8-mtp
and specifically recommends its group-scaled gs64 configuration. For more information, you can refer to the following link.
Create an optional Python environment on the external SSD:
python3-mvenv"$COLI_DRIVE/AI/venv"
Activate it:
source"$COLI_DRIVE/AI/venv/bin/activate"
Install the Hugging Face client:
pipinstall-Uhuggingface_hub
Now keep Hugging Face’s standard cache on the external drive too:
exportHF_HOME="$COLI_DRIVE/AI/huggingface"
HF_HOME controls the root of Hugging Face’s cache; otherwise, it normally defaults to your user cache on the internal drive.
Now, we are in a position to start downloading the model with the given command –
As you can see, those models that are already downloaded won’t show the model size beside their name. Otherwise, it will show the name of the model along with its size, as shown below –
The --ram parameter is explicitly Colibrì’s RAM budget for the expert working set; leaving it at 0 lets the software choose an automatic value based on available memory. For more information, you can refer to the following link.
Therefore, you can also start more safely with:
COLI_METAL=1 \./colichat \--model"$COLI_MODEL"
However, I’ll use some of the more advanced options to get the best performance out of this. “chat” means you will be triggering the chat interface.
9. Let Colibrì measure your external SSD
This part is particularly useful on a Mac.
On Metal/macOS, Colibrì automatically performs an F_NOCACHE storage test against the model volume and writes the result into:
$COLI_MODEL/.coli_ssd
The file contains the measured throughput and volume identity. Colibrì uses this information when selecting caching behavior.
You can inspect it after the first successful startup:
cat"$COLI_MODEL/.coli_ssd"
would represent a measured storage throughput value used by Colibrì.
This is particularly useful because an external enclosure advertised as “10 Gbps” or “40 Gbps” does not guarantee that the actual SSD delivers that performance under Colibrì’s workload.
10. Run Colibrì as a local AI server
For your applications, I recommend running Colibrì as a server rather than launching the model separately for every script.
And you would see & then ask some questions to get your answer, which should look like this –
Now, let us ask some questions & validate the response –
The performance is quite better. Now, based on your external SSD’s USB speed, you can get close to your MacBook Pro’s SSD speed.
In the next post, we’ll explore a more advanced combination to explore even better & faster response with the introduction of a custom script. And there will be some upgraded architecture that follows it. However, in this post, we conclude the basic concept of the Colibri framework.
The screenshot below shows the successful run without any GPU on an old legacy MacBook that has Intel Core processors. And you can see the LLM framework is utilizing the CPU cores extensively rather than relying on the GPU.
Below is the command to run Colibri on an Intel MacBook –
./coli chat \--model "$COLI_MODEL"\--ram 64
Now, if you want to use the legacy MacBook’s GPU, then you need to run the following command –
The first command will rebuild Colibri & optimize it & then you can run the chat interface.
So, we’ve done it. 🙂
I hope you all like this effort & let me know your feedback. I’ll be back with another topic. Until then, Happy Avenging!
Note: All the data & scenarios posted here are representative of data & scenarios available on the internet for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. This article is for educational purposes only. The techniques described should only be used for authorized security testing and research. Unauthorized access to computer systems is illegal and unethical & not encouraged.
Today, I will share a new post in a part series about creating end-end LLMs that feed source data with RAG implementation. I’ll also use OpenAI python-based SDK and Haystack embeddings in this case.
In this post, I’ve directly subscribed to OpenAI & I’m not using OpenAI from Azure. However, I’ll explore that in the future as well.
Before I explain the process to invoke this new library, why not view the demo first & then discuss it?
Demo
FLOW OF EVENTS:
Let us look at the flow diagram as it captures the sequence of events that unfold as part of the process.
As you can see, to enable this large & complex solution, we must first establish the capabilities to build applications powered by LLMs, Transformer models, vector search, and more. You can use state-of-the-art NLP models to perform question-answering, answer generation, semantic document search, or build tools capable of complex decision-making and query resolution. Hence, steps no. 1 & 2 showcased the data embedding & creating that informed repository. We’ll be discussing that in our second part.
Once you have the informed repository, the system can interact with the end-users. As part of the query (shown in step 3), the prompt & the question are shared with the process engine, which then turned to reduce the volume & get relevant context from our informed repository & get the tuned context as part of the response (Shown in steps 4, 5 & 6).
Then, this tuned context is shared with the OpenAI for better response & summary & concluding remarks that are very user-friendly & easier to understand for end-users (Shown in steps 8 & 9).
IMPORTANT PACKAGES:
The following are the important packages that are essential to this project –
Let us understand some of the important sections of the above script –
Function – login():
The login function retrieves a ‘username’ and ‘password’ from a JSON request and prints them. It checks if the provided credentials are missing from users or password lists, returning a failure JSON response if so. It creates and returns an access token in a JSON response if valid.
Function – get_chat():
The get_chat function retrieves the running session count and user input from a JSON request. Based on the session count, it extracts catalog data or processes the user’s message from the RAG framework that finally receives the refined response from the OpenAI, extracting hash values, image URLs, and wiki URLs. If an error arises, the function captures and returns the error as a JSON message.
Function – updateCounter():
The updateCounter function checks if a given CSV file exists and retrieves its counter value. It then increments the counter and writes it back to the CSV. If any errors occur, an error message is printed, and the function returns a value of 1.
Function – extractRemoveUrls():
The extractRemoveUrls function attempts to filter a data frame, resDf, based on a provided hash value to extract image and wiki URLs. If the data frame contains matching entries, it retrieves the corresponding URLs. Any errors encountered are printed, but the function always returns the image and wiki URLs, even if they are empty.
clsContentScrapper.py (This is the main class that brings the default options for the users if they agree with the initial prompt by the bot.)
Let us understand the the core part that require from this class.
Function – extractCatalog():
The extractCatalog function uses specific headers to make a GET request to a constructed URL. The URL is derived by appending ‘/departments’ to a base_url, and a header token is used in the request headers. If successful, it returns the text of the response; if there’s an exception, it prints the error and returns the error message.
clsRAGOpenAI.py (This is the main class that brings the RAG-enabled context that is fed to OpenAI for fine-tuned response with less cost.)
############################################################# Written By:SATYAKIDE ######## Written On:27-Jun-2023 ######## ModifiedOn28-Jun-2023 ######## ######## Objective:Thisisthemaincalling ######## pythonscriptthatwillinvokethe ######## shortcutapplicationcreatedinsideMAC ######## enviornmentincludingMacBook,IPadorIPhone. ######## #############################################################fromhaystack.document_stores.faissimportFAISSDocumentStorefromhaystack.nodesimportDensePassageRetrieverimportopenaifromclsConfigClientimportclsConfigClientascfimportclsLaslog# DisblingWarningdefwarn(*args,**kwargs):passimportwarningswarnings.warn = warnimportosimportre################################################## GlobalSection ##################################################Ind = cf.conf['DEBUG_IND']queryModel = cf.conf['QUERY_MODEL']passageModel = cf.conf['PASSAGE_MODEL']#InitiatingLoggingInstancesclog = log.clsL()os.environ["TOKENIZERS_PARALLELISM"] = "false"vectorDBFileName = cf.conf['VECTORDB_FILE_NM']indexFile = "vectorDB/" + str(vectorDBFileName) + '.faiss'indexConfig = "vectorDB/" + str(vectorDBFileName) + ".json"print('File: ',str(indexFile))print('Config: ',str(indexConfig))# Also,provide`config_path`parameterifyousetitwhencallingthe`save()`method:new_document_store = FAISSDocumentStore.load(index_path=indexFile,config_path=indexConfig)# InitializeRetrieverretriever = DensePassageRetriever(document_store=new_document_store,query_embedding_model=queryModel,passage_embedding_model=passageModel,use_gpu=False)################################################## EndofGlobalSection ##################################################classclsRAGOpenAI:def__init__(self):self.basePath = cf.conf['DATA_PATH']self.fileName = cf.conf['FILE_NAME']self.Ind = cf.conf['DEBUG_IND']self.subdir = str(cf.conf['OUT_DIR'])self.base_url = cf.conf['BASE_URL']self.outputPath = cf.conf['OUTPUT_PATH']self.vectorDBPath = cf.conf['VECTORDB_PATH']self.openAIKey = cf.conf['OPEN_AI_KEY']self.temp = cf.conf['TEMP_VAL']self.modelName = cf.conf['MODEL_NAME']self.maxToken = cf.conf['MAX_TOKEN']defextractHash(self,text):try: # Regularexpressionpatterntomatch'Ref: {'followedbyanumberandthen'}'pattern = r"Ref: \{'(\d+)'\}"match = re.search(pattern,text)ifmatch:returnmatch.group(1)else:returnNoneexceptExceptionase:x = str(e)print('Error: ',x)returnNonedefremoveSentencesWithNaN(self,text):try: # Splittextintosentencesusingregularexpressionsentences = re.split('(?<!\w\.\w.)(?<![A-Z][a-z]\.)(?<=\.|\?)\s',text) # Filteroutsentencescontaining'nan'filteredSentences = [sentenceforsentenceinsentencesif'nan'notinsentence] # Rejointhesentencesreturn''.join(filteredSentences)exceptExceptionase:x = str(e)print('Error: ',x)return''defretrieveDocumentsReader(self,question,top_k=9):returnretriever.retrieve(question,top_k=top_k)defgenerateAnswerWithGPT3(self,retrieved_docs,question):try:openai.api_key = self.openAIKeytemp = self.tempmodelName = self.modelNamemaxToken = self.maxTokendocumentsText = "".join([doc.contentfordocinretrieved_docs])filteredDocs = self.removeSentencesWithNaN(documentsText)hashValue = self.extractHash(filteredDocs)print('RAG Docs:: ')print(filteredDocs) #prompt = f"Given the following documents: {documentsText}, answer the question accurately based on the above data with the supplied http urls: {question}" # Setupachat-stylepromptwithyourdatamessages = [{"role": "system", "content": "Youareahelpfulassistant,answerthequestionaccuratelybasedontheabovedatawiththesuppliedhttpurls. Onlyrelevantcontentneedstopublish. Pleasedonotprovidethefactsorthetextsthatresultscrossingthemax_tokenlimits."},{"role": "user", "content": filteredDocs} ] # Chatstyleinvokingthelatestmodelresponse = openai.ChatCompletion.create(model=modelName,messages=messages,temperature = temp,max_tokens=maxToken )returnhashValue,response.choices[0].message['content'].strip().replace('\n','\\n')exceptExceptionase:x = str(e)print('failed to get from OpenAI: ',x)return'Not Available!'defragAnswerWithHaystackAndGPT3(self,question):retrievedDocs = self.retrieveDocumentsReader(question)returnself.generateAnswerWithGPT3(retrievedDocs,question)defgetData(self,strVal):try:print('*'*120)print('Index Your Data for Retrieval:')print('*'*120)print('Response from New Docs: ')print()hashValue,answer = self.ragAnswerWithHaystackAndGPT3(strVal)print('GPT3 Answer::')print(answer)print('Hash Value:')print(str(hashValue))print('*'*240)print('End Of Use RAG to Generate Answers:')print('*'*240)returnhashValue,answerexceptExceptionase:x = str(e)print('Error: ',x)answer = xhashValue = 1returnhashValue,answer
Let us understand some of the important block –
Function – ragAnswerWithHaystackAndGPT3():
The ragAnswerWithHaystackAndGPT3 function retrieves relevant documents for a given question using the retrieveDocumentsReader method. It then generates an answer for the query using GPT-3 with the retrieved documents via the generateAnswerWithGPT3 method. The final response is returned.
Function – generateAnswerWithGPT3():
The generateAnswerWithGPT3 function, given a list of retrieved documents and a question, communicates with OpenAI’s GPT-3 to generate an answer. It first processes the documents, filtering and extracting a hash value. Using a chat-style format, it prompts GPT-3 with the processed documents and captures its response. If an error occurs, an error message is printed, and “Not Available!” is returned.
Function – retrieveDocumentsReader():
The retrieveDocumentsReader function takes in a question and an optional parameter, top_k (defaulted to 9). It is called the retriever.retrieve method with the given parameters. The result of the retrieval will generate at max nine responses from the RAG engine, which will be fed to OpenAI.
React:
App.js (This is the main react script, that will create the interface & parse the data apart from the authentication)
// App.jsimportReact,{useState}from'react';importaxiosfrom'axios';import'./App.css';constApp=()=>{const[isLoggedIn,setIsLoggedIn]=useState(false);const[username,setUsername]=useState('');const[password,setPassword]=useState('');const[message,setMessage]=useState('');const[chatLog,setChatLog]=useState([{sender:'MuBot',message:'Welcome to MuBot! Please explore the world of History from our brilliant collections! Do you want to proceed to see the catalog?'}]);consthandleLogin=async(e)=>{e.preventDefault();try{constresponse=awaitaxios.post('http://localhost:5000/login',{username,password});if (response.status===200) {setIsLoggedIn(true);}}catch (error) {console.error('Login error:',error);}};constsendMessage=async(username)=>{if (message.trim() ==='') return;// Create a new chat entryconstnewChatEntry={sender:'user',message:message.trim(),};// Clear the input fieldsetMessage('');try{// Make API request to Python-based APIconstresponse=awaitaxios.post('http://localhost:5000/chat',{message:newChatEntry.message});// Replace with your API endpoint URLconstresponseData=response.data;// Print the response to the console for debuggingconsole.log('API Response:',responseData);// Parse the nested JSON from the 'message' attributeconstjsonData=JSON.parse(responseData.message);// Check if the data contains 'departments'if (jsonData.departments) {// Extract the 'departments' attribute from the parsed dataconstdepartments=jsonData.departments;// Extract the department names and create a single string with line breaksconstbotResponseText=departments.reduce((acc,department)=>{returnacc+department.departmentId+''+department.displayName+'\n';},'');// Update the chat log with the bot's responsesetChatLog((prevChatLog)=> [...prevChatLog,{sender:'user',message:message},{sender:'bot',message:botResponseText},]);}elseif (jsonData.records){// Data structure 2: Artwork informationconstrecords=jsonData.records;// Prepare chat entriesconstchatEntries= [];// Iterate through records and extract text, image, and wiki informationrecords.forEach((record)=>{consttextInfo=Object.entries(record).map(([key,value])=>{if (key!=='Image'&&key!=='Wiki') {return`${key}: ${value}`;}returnnull;}).filter((info)=>info!==null).join('\n');constimageLink=record.Image;//const wikiLinks = JSON.parse(record.Wiki.replace(/'/g, '"'));//const wikiLinks = record.Wiki;constwikiLinks=record.Wiki.split(',').map(link=>link.trim());console.log('Wiki:',wikiLinks);// Check if there is a valid image linkconsthasValidImage=imageLink&&imageLink!=='[]';constimageElement=hasValidImage? (<imgsrc={imageLink}alt="Artwork"style={{maxWidth:'100%'}}/> ) :null;// Create JSX elements for rendering the wiki links (if available)constwikiElements=wikiLinks.map((link,index)=> (<divkey={index}><ahref={link}target="_blank"rel="noopener noreferrer"> Wiki Link {index+1}</a></div> ));if (textInfo) {chatEntries.push({sender:'bot',message:textInfo});}if (imageElement) {chatEntries.push({sender:'bot',message:imageElement});}if (wikiElements.length >0) {chatEntries.push({sender:'bot',message:wikiElements});}});// Update the chat log with the bot's responsesetChatLog((prevChatLog)=> [...prevChatLog,{sender:'user',message},...chatEntries, ]);}}catch (error) {console.error('Error sending message:',error);}};if (!isLoggedIn) {return (<divclassName="login-container"><h2>Welcome to the MuBot</h2><formonSubmit={handleLogin}className="login-form"><inputtype="text"placeholder="Enter your name"value={username}onChange={(e)=>setUsername(e.target.value)}required/><inputtype="password"placeholder="Enter your password"value={password}onChange={(e)=>setPassword(e.target.value)}required/><buttontype="submit">Login</button></form></div> );}return (<divclassName="chat-container"><divclassName="chat-header"><h2>Hello, {username}</h2><h3>Chat with MuBot</h3></div><divclassName="chat-log">{chatLog.map((chatEntry,index)=> (<divkey={index}className={`chat-entry ${chatEntry.sender==='user'?'user':'bot'}`}><spanclassName="user-name">{chatEntry.sender==='user'?username:'MuBot'}</span><pclassName="chat-message">{chatEntry.message}</p></div> ))}</div><divclassName="chat-input"><inputtype="text"placeholder="Type your message..."value={message}onChange={(e)=>setMessage(e.target.value)}onKeyPress={(e)=>{if (e.key==='Enter') {sendMessage();}}}/><buttononClick={sendMessage}>Send</button></div></div> );};exportdefaultApp;
Please find some of the important logic –
Function – handleLogin():
The handleLogin asynchronous function responds to an event by preventing its default action. It attempts to post a login request with a username and password to a local server endpoint. If the response is successful with a status of 200, it updates a state variable to indicate a successful login; otherwise, it logs any encountered errors.
Function – sendMessage():
The sendMessage asynchronous function is designed to handle the user’s chat interaction:
If the message is empty (after trimming spaces), the function exits without further action.
A chat entry object is created with the sender set as ‘user’ and the trimmed message.
The input field’s message is cleared, and an API request is made to a local server endpoint with the chat message.
If the API responds with a ‘departments’ attribute in its JSON, a bot response is crafted by iterating over department details.
If the API responds with ‘records’ indicating artwork information, the bot crafts responses for each record, extracting text, images, and wiki links, and generating JSX elements for rendering them.
After processing the API response, the chat log state is updated with the user’s original message and the bot’s responses.
Errors, if encountered, are logged to the console.
This function enables interactive chat with bot responses that vary based on the nature of the data received from the API.
DIRECTORY STRUCTURES:
Let us explore the directory structure starting from the parent to some of the important child folder should look like this –
So, finally, we’ve done it.
I know that this post is relatively bigger than my earlier post. But, I think, you can get all the details once you go through it.
You will get the complete codebase in the following GitHub link.
I’ll bring some more exciting topics in the coming days from the Python verse. Please share & subscribe to my post & let me know your feedback.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. Some of the images (except my photo) we’ve used are available over the net. We don’t claim ownership of these images. There is always room for improvement & especially in the prediction quality.
Today, We want to make our use case a little bit harder & more realistic. We want to consume real-time live trade-data consuming through FinnHub API & displaying them into our dashboard using another brilliant H2O-Wave API with the help of native Python.
The use-case mentioned above is extremely useful & for that, we’ll be using the following Third-Party APIs to achieve the same –
FinnHub:For more information, please click the following link.
Ably: For more information, please click the following link.
H2O-Wave: For more information, please click the following link.
I’m not going to discuss these topics more, as I’ve already discussed them in separate earlier posts. Please refer to the following threads for detailed level information –
In this post, we will address the advanced concept compared to the previous post mentioned above. Let us first look at how the run looks before we start exploring the details –
Real-time trade dashboard
Let us explore the architecture of this implementation –
Architecture Diagram
This application will talk to the FinnHub websocket & consume real-time trade data from it. And this will be temporarily stored in our Ably channels. The dashboard will pick the message & display that as soon as there is new data for that trading company.
For this use case, you need to install the following packages –
STEP – 1:
Main Packages
STEP – 2:
Main Packages – Continue
STEP – 3:
Main Packages – Continue
STEP – 4:
Main Packages – End
You can copy the following commands to install the above-mentioned packages –
Let’s explore the important data-point that you need to capture from the FinnHub portal to consume the real-time trade data –
FinnHub Portal
We’ve two main scripts. The first script will consume the streaming data into a message queue & the other one will be extracting the data from the queue & transform the data & publish it into the real-time dashboard.
1. dashboard_finnhub.py ( This native Python script will consume streaming data & create the live trade dashboard. )
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters. Learn more about bidirectional Unicode characters
Let’s explore the key snippets from the above script –
def process_DF(inputDF, inputDFUnq):
    try:
        # Core Business logic
        # The application will show default value to any
        # trade-in stock in case that data doesn't consume
        # from the source.

        # Getting block count
        #df_conv['block_count'] = df_conv.groupby(['default_rank']).cumcount()
        #l.logr('3. block_df.csv', 'Y', df_conv, subdir)

        # Getting block count
        #df_conv['max_count'] = df_conv.groupby(['default_rank']).size()
        #df_conv_fin = df_conv.groupby(['default_rank']).agg(['count'])
        #df_conv_fin = df_conv.value_counts(['default_rank']).reset_index(name='max_count')
        #df_conv_fin = df_conv.value_counts(['default_rank'])
        df_conv = inputDF
        df_unique_fin = inputDFUnq

        df_conv['max_count'] = df_conv.groupby('default_rank')['default_rank'].transform('count')
        l.logr('3. max_df.csv', 'Y', df_conv, subdir)


        # Sorting the output
        sorted_df = df_conv.sort_values(by=['default_rank','s'], ascending=True)

        # New Column List Orders
        column_order = ['s', 'default_rank', 'max_count', 'p', 't', 'v']
        df_fin = sorted_df.reindex(column_order, axis=1)

        l.logr('4. sorted_df.csv', 'Y', df_fin, subdir)

        # Now splitting the sorted df into two sets
        lkp_max_count = 4
        df_fin_na = df_fin[(df_fin['max_count'] == lkp_max_count)]

        l.logr('5. df_fin_na.csv', 'Y', df_fin_na, subdir)

        df_fin_req = df_fin[(df_fin['max_count'] != lkp_max_count)]
        l.logr('6. df_fin_req.csv', 'Y', df_fin_req, subdir)

        # Now to perform cross join, we will create
        # a key column in both the DataFrames to
        # merge on that key.
        df_unique_fin['key'] = 1
        df_fin_req['key'] = 1

        # Dropping unwanted columns
        df_unique_fin.drop(columns=['t'], axis=1, inplace=True)
        l.logr('7. df_unique_slim.csv', 'Y', df_unique_fin, subdir)

        # Padding with dummy key values
        #merge_df = p.merge(df_unique_fin,df_fin_req,on=['s'],how='left')
        merge_df = p.merge(df_unique_fin,df_fin_req,on=['key']).drop("key", 1)

        l.logr('8. merge_df.csv', 'Y', merge_df, subdir)

        # Sorting the output
        sorted_merge_df = merge_df.sort_values(by=['default_rank_y','s_x'], ascending=True)

        l.logr('9. sorted_merge_df.csv', 'Y', sorted_merge_df, subdir)

        # Calling new derived logic
        sorted_merge_df['derived_p'] = sorted_merge_df.apply(lambda row: calc_p(row), axis=1)
        sorted_merge_df['derived_v'] = sorted_merge_df.apply(lambda row: calc_v(row), axis=1)

        l.logr('10. sorted_merge_derived.csv', 'Y', sorted_merge_df, subdir)

        # Dropping unwanted columns
        sorted_merge_df.drop(columns=['default_rank_x', 'p_x', 'v_x', 's_y', 'p_y', 'v_y'], axis=1, inplace=True)

        #Renaming the columns
        sorted_merge_df.rename(columns={'s_x':'s'}, inplace=True)
        sorted_merge_df.rename(columns={'default_rank_y':'default_rank'}, inplace=True)
        sorted_merge_df.rename(columns={'derived_p':'p'}, inplace=True)
        sorted_merge_df.rename(columns={'derived_v':'v'}, inplace=True)

        l.logr('11. org_merge_derived.csv', 'Y', sorted_merge_df, subdir)

        # Aligning columns
        column_order = ['s', 'default_rank', 'max_count', 'p', 't', 'v']
        merge_fin_df = sorted_merge_df.reindex(column_order, axis=1)

        l.logr('12. merge_fin_df.csv', 'Y', merge_fin_df, subdir)

        # Finally, appending these two DataFrame (df_fin_na & merge_fin_df)
        frames = [df_fin_na, merge_fin_df]
        fin_df = p.concat(frames, keys=["s", "default_rank", "max_count"])

        l.logr('13. fin_df.csv', 'Y', fin_df, subdir)

        # Final clearance & organization
        fin_df.drop(columns=['default_rank', 'max_count'], axis=1, inplace=True)

        l.logr('14. Final.csv', 'Y', fin_df, subdir)

        # Adjusting key columns
        fin_df.rename(columns={'s':'Company'}, inplace=True)
        fin_df.rename(columns={'p':'CurrentExchange'}, inplace=True)
        fin_df.rename(columns={'v':'Change'}, inplace=True)

        l.logr('15. TransormedFinal.csv', 'Y', fin_df, subdir)

        return fin_df
    except Exception as e:
        print('$' * 120)

        x = str(e)
        print(x)

        print('$' * 120)

        df = p.DataFrame()

        return df
The above function will check if the queue is sending all the key trade-in data for all the companies. In our use case, we’re testing with the four companies & they are as follows –
a. AAPL
b. AMZN
c. BINANCE:BTCUSDT
d. IC MARKETS:1
Every message is containing data from all of these four companies together. If any of the company’s data is missing, this transformation will add a dummy record of that missing company to make the uniform number of entries in each message bouquet. And dummy trade-in values added for all the missing information.
In the above snippet, the application will consume the streaming data from the Ably queue.
for i in message_page.items:
        print('Last Msg: {}'.format(i.data))
        json_data = json.loads(i.data)

        # Converting JSON to Dataframe
        df = p.json_normalize(json_data)
        df.columns = df.columns.map(lambda x: x.split(".")[-1])

        if cnt == 0:
            df_conv = df
        else:
            d_frames = [df_conv, df]
            df_conv = p.concat(d_frames)

        cnt += 1
The above snippet will convert the streaming messages to a more meaningful pandas data-frame, which we can use for a wide variety of analytics.
    # Converting dataframe to a desired Series
    f = CategoricalSeries(fin_df)

    for j in range(count_row):
        # Getting the series values from above
        cat, val, pc = f.next()

        # Getting Individual Element & convert them to Series
        if ((start_pos + interval) <= count_row):
            end_pos = start_pos + interval
        else:
            end_pos = start_pos + (count_row - start_pos)

        split_df = df_unq_finale.iloc[start_pos:end_pos]

        if ((start_pos > count_row) | (start_pos == count_row)):
            pass
        else:
            start_pos = start_pos + interval

        x_currency = str(split_df.iloc[0]['Company'])

        ####################################################
        ##### Debug Purpose                        #########
        ####################################################
        print('Company: ', x_currency)
        print('J: ', str(j))
        print('Cat: ', cat)
        ####################################################
        #####   End Of Debug                         #######
        ####################################################

        c = page.add(f'e{j+1}', ui.tall_series_stat_card(
            box=f'{j+1} 1 1 2',
            title=x_currency,
            value='=${{intl qux minimum_fraction_digits=2 maximum_fraction_digits=2}}',
            aux_value='={{intl quux style="percent" minimum_fraction_digits=1 maximum_fraction_digits=1}}',
            data=dict(qux=val, quux=pc),
            plot_type='area',
            plot_category='foo',
            plot_value='qux',
            plot_color=next_color(),
            plot_data=data('foo qux', -15),
            plot_zero_value=0,
            plot_curve=next_curve(),
        ))
        large_lines.append((f, c))

    page.save()

    while update_freq > 0:

        time.sleep(update_freq)

        for f, c in large_lines:
            cat, val, pc = f.next()

            print('Update Cat: ', cat)
            print('Update Val: ', val)
            print('Update pc: ', pc)
            print('*' * 160)

            c.data.qux = val
            c.data.quux = pc / 100
            c.plot_data[-1] = [cat, val]

        page.save()
The above snippet will consume the data into H2O-Wave driven framework, which will expose this data into beautiful & easily representable GUI-based solutions through an interactive dashboard.
2. publish_ably_mod.py ( This native Python script will consume streaming data into Ably message Queue )
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters. Learn more about bidirectional Unicode characters
As we already discussed, we’ll pass a default set of data for all the candidate companies.
    # Publish a message to the sd_channel channel
    channel.publish('event', jdata)

    # Publish rest of the messages to the sd_channel channel
    channel.publish('event', jdata_dyn)
Send the company-specific trade queries through websocket apps to submit that to FinnHub.
3. clsConfig.py ( This file contains the configuration details. )
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters. Learn more about bidirectional Unicode characters
Today, I’ll be using a popular tool known as Mulesoft to generate a mock API & then we’ll be testing the same using python. Mulesoft is an excellent tool to rapidly develop API & also can integrate multiple cloud environments as an Integration platform. You can use their Anypoint platform to quickly design such APIs for your organization. You can find the details in the following link. However, considering the cost, many organization has to devise their own product or tool to do the same. That’s where developing a Python or Node.js or C# comes adequately considering the cloud platform.
Before we start, let us quickly know what Mock API is?
A mock API server imitates a real API server by providing realistic responses to requests. They can be on your local machine or the public Internet. Responses can be static or dynamic, and simulate the data the real API would return, matching the schema with data types, objects, and arrays.
And why do we need that?
A mock API server is useful during development and testing when live data is either unavailable or unreliable. While designing an API, you can use mock APIs to work concurrently on the front and back-end, as well as to gather feedback from developers. Our mock API sever guide for testing covers how you can use a mock API server so the absence of a real API doesn’t hold you back.
Often with internal projects, the API consumer (such as a front end developer through REST APIs) moves faster than the backend team building the API. This API mocking guide shows how a mock API server allows developers to consume a working API with the same interface as the eventual production API. As an added benefit, the backend team can discover where the mock API doesn’t meet the developer’s needs without spending developer time on features that may be removed or changed. This fast feedback loop can make engineering teams much more efficient.
If you need more information on this topic, you can refer to the following link.
Great! Since now we have a background of mock API – let’s explore how Mulesoft can help us here?
Mulesoft used the “RESTfulAPIModelingLanguage (RAML)” language. We’ll be using this language to develop our mock API. To know more about this, you can view the following link.
Under the developer section, you can find Tutorials as shown in the screenshot given below –
You can select any of the categories & learn basic scripting from it.
Now, let’s take a look at the process of creating a Mulesoft free account to test our theories.
Step 1:
Click the following link, and you will see the page as shown below –
Step 2:
Now, click the login shown in the RED square. You will see the following page –
Step 3:
Please provide your credentials if you already have an account. Else, you have to click the “Sign-Up” & then you will need to provide the few details as shown below –
Step 4:
Once, you successfully create the account, you will see the following page –
So, now we are set. To design an API, you will need to click the design center as marked within the white square.
Once you click the “Start designing” button, this will land into the next screen.
As shown above, you need to click the “Create new” for fresh API design.
This will prompt you the next screen –
Now, you need to create the – “Create API specification” as marked in the RED square box. And, that will prompt you the following screen –
You have to provide a meaningful name of our API & you can choose either Text or Visual editor. For this task, we’ll be selecting the Text Editor. And we’ll select RAML 1.0 as our preferred language. Once, we provide all the relevant information, the “Create Specification” button marked in Green will be activated. And then you need to click it. It will lead you to the next screen –
Since we’ll be preparing this for mock API, we need to activate that by clicking the toggle button marked in the GREEN square box on the top-right side. And, this will generate an automated baseUri script as shown below –
Now, we’re ready to develop our RAML code for the mock API. Let’s look into the RAML code.
1. phonevalisd.raml (This is the mock API script, which will send the response of an API request by returning a mock JSON if successful conditions met.)
#%RAML 1.0# Created By - Satyaki De# Date: 01-Mar-2020# Description: This is an Mock API
baseUri: https://anypoint.mulesoft.com/mocking/api/v1/links/09KK0pos-1080-4049-9e04-a093456a64a8/#
title: PhoneVSD
securitySchemes:
    basic :
        type: Basic Authentication
displayName: Satyaki's Basic Authentication
description: API Only works with the basic authentication
protocols:
- HTTP
description: This is a REST API Json base service to verify any phone numbers.
documentation:
- title: PHONE VERIFY API
content: This is a Mock API, which will simulate the activity of a Phone Validation API.
types:
apiresponse:
properties:
valid: boolean
number: string
local_format: string
international_format: string
country_prefix: string
country_code: string
country_name: string
location: string
carrier: string
line_type: string
/validate:
get:
queryParameters:
access_key: string
number: string
country_code: string
format: string
description: For Validating the phone
displayName: Validate phone
protocols:
- HTTP
responses:
      403:
        body:
          application/json:
            properties:
              message: string
            example:
              {
                message : "Resource does not exists!"
              }
      400:
        body:
          application/json:
            properties:
              message: string
            example:
              {
                message : "API Key is invalid!"
              }
      200:
        body:
          application/json:
            type: apiresponse
            example:
              {
                "valid":true,
                "number":"17579758240",
                "local_format":"7579758240",
                "international_format":"+17579758240",
                "country_prefix":"+1",
                "country_code":"US",
                "country_name":"United States of America",
                "location":"Nwptnwszn1",
                "carrier":"MetroPCS Communications Inc.",
                "line_type":"mobile"
              }
Let’s quickly explore the critical snippet from the above script.
We’ve created a provision for a few specific cases of response as part of our business logic & standards.
Once, we’re done with our coding, we need to focus on two places as shown in the below picture –
The snippet marked in RED square box, identifying our mandatory input parameters shown in the code as well as the right-hand side of the walls.
To test this mock API locally, you can pass these key parameters as follows –
Now, you have to click the Send button marked in a GREEN square box. This will send your query parameters & as per our API response, you can see the output just below the Send button as follows –
Now, we’re good to publish this mock API in the Mulesoft Anywhere portal. This will help us to test it from an external application i.e., Python-based application for our case. So, click the “Publish” button highlighted with the Blue square box. That will prompt the following screen –
Now, we’ll click the “Public to Exchange” button marked with the GREEN square box. This will prompt the next screen as shown below –
Now, you need to fill up the relevant details & then click – “Publish to Exchange,” as shown above. And, that will lead to the following screen –
And, after a few second you will see the next screen –
Now, you can click “Done” to close this popup. And, to verify the status, you can check it by clicking the top-left side of the code-editor & then click “Design Center” as shown below –
So, we’re done with our Mulesoft mock API design & deployment. Let’s test it from our Python application. We’ll be only discussing the key snippets here.
2. clsConfig.py (This is the parameter file for our mock API script.)
################################################## Written By: SATYAKI DE ######## Written On: 04-Apr-2020 ######## ######## Objective: This script is a config ######## file, contains all the keys for ######## Mulesoft Mock API. Application will ######## process these information & perform ######## the call to our newly developed Mock ######## API in Mulesoft. ##################################################importosimportplatformasplclassclsConfig(object):
Curr_Path = os.path.dirname(os.path.realpath(__file__))
os_det = pl.system()
if os_det =="Windows":
sep ='\\'else:
sep ='/'
config = {
'APP_ID': 1,
'URL': "https://anypoint.mulesoft.com/mocking/api/v1/links/a23e4e71-9c25-317b-834b-10b0debc3a30/validate",
'CLIENT_SECRET': 'a12345670bacb1e3cec55e2f1234567d',
'API_TYPE': "application/json",
'CACHE': "no-cache",
'CON': "keep-alive",
'ARCH_DIR': Curr_Path + sep +'arch'+ sep,
'PROFILE_PATH': Curr_Path + sep +'profile'+ sep,
'LOG_PATH': Curr_Path + sep +'log'+ sep,
'REPORT_PATH': Curr_Path + sep +'report',
'SRC_PATH': Curr_Path + sep +'Src_File'+ sep,
'APP_DESC_1': 'Mule Mock API Calling!',
'DEBUG_IND': 'N',
'INIT_PATH': Curr_Path
}
Today, I’ll share a little different topic in Python compared to my last couple of posts, where I have demonstrated the use of Python in the field of machine learning & forecast modeling.
We’ll explore to create meaningful sample data points for Airlines & hotel reservations. At this moment, this industry is the hard-hit due to the pandemic. And I personally wish a speedy recovery to all employees who risked their lives to maintain the operation or might have lost their jobs due to this time.
I’ll be providing only major scripts & will show how you can extract critical data from their API.
However, to create the API, you need to register in Amadeus as a developer & follow specific steps to get the API details. You will need to register using the following link.
Step 1:
Once you provide the necessary details, you need to activate your account by clicking the email validation.
Step 2:
As part of the next step, you will be clicking the “Self-Service Workspace” option as marked in the green box shown above.
Now, you have to click “My apps“ & under that, you need to click – “Create new app” shown below –
Step 3:
You need to provide the following details before creating the API. Note that once you create – it will take 30 minutes to activate the API-link.
Step 4:
You will come to the next page once you click the “Create” button in the previous step.
For production, you need to create a separate key shown above.
You need to install the following packages –
pip install amadeus
And, the installation process is shown as –
pip install flatten_json
And, this installation process is shown as –
1. clsAmedeus (This is the API script, which will send the API requests & return JSON if successful.)
################################################## Written By: SATYAKI DE ######## Written On: 05-Jul-2020 ######## Modified On 05-Jul-2020 ######## ######## Objective: Main calling scripts. ##################################################fromamadeusimport Client, ResponseError
importjsonfromclsConfigimport clsConfig as cf
classclsAmedeus:
def__init__(self):
self.client_id = cf.config['CLIENT_ID']
self.client_secret = cf.config['CLIENT_SECRET']
self.type = cf.config['API_TYPE']
defflightOffers(self, origLocn, destLocn, departDate, noOfAdult):
try:
cnt =0# Setting Clients
amadeus = Client(
client_id=str(self.client_id),
client_secret=str(self.client_secret)
)
# Flight Offers
response = amadeus.shopping.flight_offers_search.get(
originLocationCode=origLocn,
destinationLocationCode=destLocn,
departureDate=departDate,
adults=noOfAdult)
ResJson = response.data
return ResJson
exceptExceptionas e:
print(e)
x =str(e)
ResJson = {'errorDetails': x}
return ResJson
defcheapestDate(self, origLocn, destLocn):
try:
# Setting Clients
amadeus = Client(
client_id=self.client_id,
client_secret=self.client_secret
)
# Flight Offers# Flight Cheapest Date Search
response = amadeus.shopping.flight_dates.get(origin=origLocn, destination=destLocn)
ResJson = response.data
return ResJson
exceptExceptionas e:
print(e)
x =str(e)
ResJson = {'errorDetails': x}
return ResJson
deflistOfHotelsByCity(self, origLocn):
try:
# Setting Clients
amadeus = Client(
client_id=self.client_id,
client_secret=self.client_secret
)
# Hotel Search# Get list of Hotels by city code
response = amadeus.shopping.hotel_offers.get(cityCode=origLocn)
ResJson = response.data
return ResJson
exceptExceptionas e:
print(e)
x =str(e)
ResJson = {'errorDetails': x}
return ResJson
deflistOfOffersBySpecificHotels(self, hotelID):
try:
# Setting Clients
amadeus = Client(
client_id=self.client_id,
client_secret=self.client_secret
)
# Get list of offers for a specific hotel
response = amadeus.shopping.hotel_offers_by_hotel.get(hotelId=hotelID)
ResJson = response.data
return ResJson
exceptExceptionas e:
print(e)
x =str(e)
ResJson = {'errorDetails': x}
return ResJson
defhotelReview(self, hotelID):
try:
# Setting Clients
amadeus = Client(
client_id=self.client_id,
client_secret=self.client_secret
)
# Hotel Ratings# What travelers think about this hotel?
response = amadeus.e_reputation.hotel_sentiments.get(hotelIds=hotelID)
ResJson = response.data
return ResJson
exceptExceptionas e:
print(e)
x =str(e)
ResJson = {'errorDetails': x}
return ResJson
defprocess(self, choice, origLocn, destLocn, departDate, noOfAdult, hotelID):
try:
# Main Area to call apropriate choiceif choice ==1:
resJson =self.flightOffers(origLocn, destLocn, departDate, noOfAdult)
elif choice ==2:
resJson =self.cheapestDate(origLocn, destLocn)
elif choice ==3:
resJson =self.listOfHotelsByCity(origLocn)
elif choice ==4:
resJson =self.listOfOffersBySpecificHotels(hotelID)
elif choice ==5:
resJson =self.hotelReview(hotelID)
else:
resJson = {'errorDetails': 'Invalid Options!'}
# Converting back to JSON
jdata = json.dumps(resJson)
# Checking the begining character# for the new package# As that requires dictionary array# Hence, We'll be adding '[' if this# is missing from the return payload
SYM = jdata[:1]
if SYM !='[':
rdata ='['+ jdata +']'else:
rdata = jdata
ResJson = json.loads(rdata)
return ResJson
except ResponseError as error:
x =str(error)
resJson = {'errorDetails': x}
return resJson
Let’s explore the key lines –
Creating an instance of the client by providing the recently acquired API Key & API-Secret.
Today, I’ll be demonstrating some scenarios based on open-source data from Canada. In this post, I will only explain some of the significant parts of the code. Not the entire range of scripts here.
Let’s explore a couple of sample source data –
I would like to explore how much this disease caused an impact on the elderly in Canada.
Let’s explore the source directory structure –
For this, you need to install the following packages –
In this case, we’ve downloaded the data from Canada’s site. However, they have created API. So, you can consume the data through that way as well. Since the volume is a little large. I decided to download that in CSV & then use that for my analysis.
Before I start, let me explain a couple of critical assumptions that I had to make due to data impurities or availabilities.
If there is no data available for a specific case, my application will consider that patient as COVID-Active.
We will consider the patient is affected through Community-spreading until we have data to find it otherwise.
If there is no data available for gender, we’re marking these records as “Other.” So, that way, we’re making it into that category, where the patient doesn’t want to disclose their sexual orientation.
If we don’t have any data, then by default, the application is considering the patient is alive.
Lastly, my application considers the middle point of the age range data for all the categories, i.e., the patient’s age between 20 & 30 will be considered as 25.
1. clsCovidAnalysisByCountryAdv (This is the main script, which will invoke the Machine-Learning API & return 0 if successful.)
################################################## Written By: SATYAKI DE ######## Written On: 01-Jun-2020 ######## Modified On 01-Jun-2020 ######## ######## Objective: Main scripts for Logistic ######## Regression. ##################################################importpandasaspimportclsLaslogimportdatetimeimportmatplotlib.pyplotaspltimportseabornassnsfromclsConfigimport clsConfig as cf
# %matplotlib inline -- for Jupyter NotebookclassclsCovidAnalysisByCountryAdv:
def__init__(self):
self.fileName_1 = cf.config['FILE_NAME_1']
self.fileName_2 = cf.config['FILE_NAME_2']
self.Ind = cf.config['DEBUG_IND']
self.subdir =str(cf.config['LOG_DIR_NAME'])
defsetDefaultActiveCases(self, row):
try:
str_status =str(row['case_status'])
if str_status =='Not Reported':
return'Active'else:
return str_status
except:
return'Active'defsetDefaultExposure(self, row):
try:
str_exposure =str(row['exposure'])
if str_exposure =='Not Reported':
return'Community'else:
return str_exposure
except:
return'Community'defsetGender(self, row):
try:
str_gender =str(row['gender'])
if str_gender =='Not Reported':
return'Other'else:
return str_gender
except:
return'Other'defsetSurviveStatus(self, row):
try:
# 0 - Deceased# 1 - Alive
str_active =str(row['ActiveCases'])
if str_active =='Deceased':
return0else:
return1except:
return1defgetAgeFromGroup(self, row):
try:
# We'll take the middle of the Age group# If a age range falls with 20, we'll# consider this as 10.# Similarly, a age group between 20 & 30,# should reflect by 25.# Anything above 80 will be considered as# 85
str_age_group =str(row['AgeGroup'])
if str_age_group =='<20':
return10elif str_age_group =='20-29':
return25elif str_age_group =='30-39':
return35elif str_age_group =='40-49':
return45elif str_age_group =='50-59':
return55elif str_age_group =='60-69':
return65elif str_age_group =='70-79':
return75else:
return85except:
return100defpredictResult(self):
try:
# Initiating Logging Instances
clog = log.clsL()
# Important variables
var = datetime.datetime.now().strftime(".%H.%M.%S")
print('Target File Extension will contain the following:: ', var)
Ind =self.Ind
subdir =self.subdir
######################################## ## Using Logistic Regression to ## Idenitfy the following scenarios - ## ## Age wise Infection Vs Deaths ## ########################################
inputFileName_2 =self.fileName_2
# Reading from Input File
df_2 = p.read_csv(inputFileName_2)
# Fetching only relevant columns
df_2_Mod = df_2[['date_reported','age_group','gender','exposure','case_status']]
df_2_Mod['State'] = df_2['province_abbr']
print()
print('Projecting 2nd file sample rows: ')
print(df_2_Mod.head())
print()
x_row_1 = df_2_Mod.shape[0]
x_col_1 = df_2_Mod.shape[1]
print('Total Number of Rows: ', x_row_1)
print('Total Number of columns: ', x_col_1)
########################################################################################## Few Assumptions ########################################################################################### By default, if there is no data on exposure - We'll treat that as community spreading ## By default, if there is no data on case_status - We'll consider this as active ## By default, if there is no data on gender - We'll put that under a separate Gender ## category marked as the "Other". This includes someone who doesn't want to identify ## his/her gender or wants to be part of LGBT community in a generic term. ## ## We'll transform our data accordingly based on the above logic. ##########################################################################################
df_2_Mod['ActiveCases'] = df_2_Mod.apply(lambda row: self.setDefaultActiveCases(row), axis=1)
df_2_Mod['ExposureStatus'] = df_2_Mod.apply(lambda row: self.setDefaultExposure(row), axis=1)
df_2_Mod['Gender'] = df_2_Mod.apply(lambda row: self.setGender(row), axis=1)
# Filtering all other records where we don't get any relevant information# Fetching Data for
df_3 = df_2_Mod[(df_2_Mod['age_group'] !='Not Reported')]
# Dropping unwanted columns
df_3.drop(columns=['exposure'], inplace=True)
df_3.drop(columns=['case_status'], inplace=True)
df_3.drop(columns=['date_reported'], inplace=True)
df_3.drop(columns=['gender'], inplace=True)
# Renaming one existing column
df_3.rename(columns={"age_group": "AgeGroup"}, inplace=True)
# Creating important feature# 0 - Deceased# 1 - Alive
df_3['Survived'] = df_3.apply(lambda row: self.setSurviveStatus(row), axis=1)
clog.logr('2.df_3'+ var +'.csv', Ind, df_3, subdir)
print()
print('Projecting Filter sample rows: ')
print(df_3.head())
print()
x_row_2 = df_3.shape[0]
x_col_2 = df_3.shape[1]
print('Total Number of Rows: ', x_row_2)
print('Total Number of columns: ', x_col_2)
# Let's do some basic checkings
sns.set_style('whitegrid')
#sns.countplot(x='Survived', hue='Gender', data=df_3, palette='RdBu_r')# Fixing Gender Column# This will check & indicate yellow for missing entries#sns.heatmap(df_3.isnull(), yticklabels=False, cbar=False, cmap='viridis')#sex = p.get_dummies(df_3['Gender'], drop_first=True)
sex = p.get_dummies(df_3['Gender'])
df_4 = p.concat([df_3, sex], axis=1)
print('After New addition of columns: ')
print(df_4.head())
clog.logr('3.df_4'+ var +'.csv', Ind, df_4, subdir)
# Dropping unwanted columns for our Machine Learning
df_4.drop(columns=['Gender'], inplace=True)
df_4.drop(columns=['ActiveCases'], inplace=True)
df_4.drop(columns=['Male','Other','Transgender'], inplace=True)
clog.logr('4.df_4_Mod'+ var +'.csv', Ind, df_4, subdir)
# Fixing Spread Columns
spread = p.get_dummies(df_4['ExposureStatus'], drop_first=True)
df_5 = p.concat([df_4, spread], axis=1)
print('After Spread columns:')
print(df_5.head())
clog.logr('5.df_5'+ var +'.csv', Ind, df_5, subdir)
# Dropping unwanted columns for our Machine Learning
df_5.drop(columns=['ExposureStatus'], inplace=True)
clog.logr('6.df_5_Mod'+ var +'.csv', Ind, df_5, subdir)
# Fixing Age Columns
df_5['Age'] = df_5.apply(lambda row: self.getAgeFromGroup(row), axis=1)
df_5.drop(columns=["AgeGroup"], inplace=True)
clog.logr('7.df_6'+ var +'.csv', Ind, df_5, subdir)
# Fixing Dummy Columns Name# Renaming one existing column Travel-Related with Travel_Related
df_5.rename(columns={"Travel-Related": "TravelRelated"}, inplace=True)
clog.logr('8.df_7'+ var +'.csv', Ind, df_5, subdir)
# Removing state for temporary basis
df_5.drop(columns=['State'], inplace=True)
# df_5.drop(columns=['State','Other','Transgender','Pending','TravelRelated','Male'], inplace=True)# Casting this entire dataframe into Integer# df_5_temp.apply(p.to_numeric)print('Info::')
print(df_5.info())
print("*"*60)
print(df_5.describe())
print("*"*60)
clog.logr('9.df_8'+ var +'.csv', Ind, df_5, subdir)
print('Intermediate Sample Dataframe for Age::')
print(df_5.head())
# Plotting it to Graphsns.jointplot(x="Age", y='Survived', data=df_5)
sns.jointplot(x="Age", y='Survived', data=df_5, kind='kde', color='red')
plt.xlabel("Age")
plt.ylabel("Data Point (0 - Died Vs 1 - Alive)")# Another check with Age Group
sns.countplot(x='Survived', hue='Age', data=df_5, palette='RdBu_r')
plt.xlabel("Survived(0 - Died Vs 1 - Alive)")
plt.ylabel("Total No Of Patient")
df_6 = df_5.drop(columns=['Survived'], axis=1)
clog.logr('10.df_9'+ var +'.csv', Ind, df_6, subdir)
# Train & Split Data
x_1 = df_6
y_1 = df_5['Survived']
# Now Train-Test Split of your source datafromsklearn.model_selectionimport train_test_split
# test_size => % of allocated data for your test cases# random_state => A specific set of random split on your data
X_train_1, X_test_1, Y_train_1, Y_test_1 = train_test_split(x_1, y_1, test_size=0.3, random_state=101)
# Importing Modelfromsklearn.linear_modelimport LogisticRegression
logmodel = LogisticRegression()
logmodel.fit(X_train_1, Y_train_1)
# Adding Predictions to it
predictions_1 = logmodel.predict(X_test_1)
fromsklearn.metricsimport classification_report
print('Classification Report:: ')
print(classification_report(Y_test_1, predictions_1))
fromsklearn.metricsimport confusion_matrix
print('Confusion Matrix:: ')
print(confusion_matrix(Y_test_1, predictions_1))
# This is require when you are trying to print from conventional# front & not using Jupyter notebook.
plt.show()
return0exceptExceptionas e:
x =str(e)
print('Error : ', x)
return1
Key snippets from the above script –
df_2_Mod['ActiveCases'] = df_2_Mod.apply(lambda row: self.setDefaultActiveCases(row), axis=1)df_2_Mod['ExposureStatus'] = df_2_Mod.apply(lambda row: self.setDefaultExposure(row), axis=1)df_2_Mod['Gender'] = df_2_Mod.apply(lambda row: self.setGender(row), axis=1)# Filtering all other records where we don't get any relevant information# Fetching Data fordf_3 = df_2_Mod[(df_2_Mod['age_group'] != 'Not Reported')]# Dropping unwanted columnsdf_3.drop(columns=['exposure'], inplace=True)df_3.drop(columns=['case_status'], inplace=True)df_3.drop(columns=['date_reported'], inplace=True)df_3.drop(columns=['gender'], inplace=True)# Renaming one existing columndf_3.rename(columns={"age_group": "AgeGroup"}, inplace=True)# Creating important feature# 0 - Deceased# 1 - Alivedf_3['Survived'] = df_3.apply(lambda row: self.setSurviveStatus(row), axis=1)
The above lines point to the critical transformation areas, where the application is invoking various essential business logic.
The above lines will transform the data into this –
As you can see, we’ve transformed the row values into columns with binary values. This kind of transformation is beneficial.
# Plotting it to Graphsns.jointplot(x="Age", y='Survived', data=df_5)sns.jointplot(x="Age", y='Survived', data=df_5, kind='kde', color='red')plt.xlabel("Age")plt.ylabel("Data Point (0 - Died Vs 1 - Alive)")# Another check with Age Groupsns.countplot(x='Survived', hue='Age', data=df_5, palette='RdBu_r')plt.xlabel("Survived(0 - Died Vs 1 - Alive)")plt.ylabel("Total No Of Patient")
The above lines will process the data & visualize based on that.
x_1 = df_6y_1 = df_5['Survived']
In the above snippet, we’ve assigned the features & target variable for our final logistic regression model.
# Now Train-Test Split of your source datafrom sklearn.model_selection import train_test_split# test_size => % of allocated data for your test cases# random_state => A specific set of random split on your dataX_train_1, X_test_1, Y_train_1, Y_test_1 = train_test_split(x_1, y_1, test_size=0.3, random_state=101)# Importing Modelfrom sklearn.linear_model import LogisticRegressionlogmodel = LogisticRegression()logmodel.fit(X_train_1, Y_train_1)
In the above snippet, we’re splitting the primary data & create a set of test & train data. Once we have the collection, the application will put the logistic regression model. And, finally, we’ll fit the training data.
The above lines, finally use the model & then we feed our test data.
Let’s see how it runs –
And, here is the log directory –
For better understanding, I’m just clubbing both the diagram at one place & the final outcome is showing as follows –
So, from the above picture, we can see that the maximum vulnerable patients are patients who are 80+. The next two categories that also suffered are 70+ & 60+.
Also, We’ve checked the Female Vs. Male in the following code –
sns.countplot(x='Survived', hue='Female', data=df_5, palette='RdBu_r')plt.xlabel("Survived(0 - Died Vs 1 - Alive)")plt.ylabel("Female Vs Male (Including Other Genders)")
And, the analysis represents through this –
In this case, you have to consider that the Male part includes all the other genders apart from the actual Male. Hence, I believe death for females would be more compared to people who identified themselves as males.
So, finally, we’ve done it.
During this challenging time, I would request you to follow strict health guidelines & stay healthy.
N.B.: All the data that are used here can be found in the public domain. We use this solely for educational purposes. You can find the details here.
Today, We’ll be discussing one more graphical package in Python, which is also known as PyQt. To faster design the GUI, we’ll be exploring another tool called Qt Designer, which is available for multiple OS platforms.
This is similar to any other GUI based IDE like Microsoft Visual Studio, where you can quickly generate your GUI template.
The majority of the internet post talks about using PyQt5 or PyQt4 packages. But, when speaking about using the .ui file inside your Python code – they either demonstrate fundamental options without any event or, they convert & generate the .ui file into .py file & then they use it. This certainly not making it very useful for many of the developers who are trying to use it for the first time. Hence, My main goal is to use the .ui file inside my Python script as it is & use all the components out of it & assign various working events.
In this post, we’ll discuss only with one script & then we’ll showcase the output in the form of video (No audio). You can verify the output for both MAC & Windows.
Before we start, let us check the directory structure between Windows & MAC –
Let us explore how the GUI should look like ->
So, as you can see that this tool is like any other GUI based tool, basically you can create anything by simply drag & drop method.
Before we start discussing our code, here is the sample basicAdv.ui file for your reference.
You need to install the following framework –
pip install PyQt5
1. GUIPyQt5.py (This script contains all the GUI details & it will invoke the instance along with the logic.)
################################################## Written By: SATYAKI DE ######## Written On: 12-Mar-2020 ######## Modified On 12-Mar-2020 ######## ######## Objective: Main calling scripts. ##################################################fromPyQt5import QtWidgets, uic, QtGui, QtCore
fromPyQt5.QtWidgetsimport*importsysclassUi(QtWidgets.QMainWindow):
def__init__(self):
# Instantiating the main classsuper(Ui, self).__init__()
# Loading the Graphical Design without# converting it to any kind of Python code
uic.loadUi('basicAdv.ui', self)
# Adding all the essential buttonsself.prtBtn =self.findChild(QtWidgets.QPushButton, 'prtBtn') # Find the buttonself.prtBtn.clicked.connect(self.printButtonClick) # Remember to pass the definition/method, not the return value!self.clrBtn =self.findChild(QtWidgets.QPushButton, 'clrBtn') # Find the buttonself.clrBtn.clicked.connect(self.clearButtonClick) # Remember to pass the definition/method, not the return value!self.addBtn =self.findChild(QtWidgets.QPushButton, 'addBtn') # Find the buttonself.addBtn.clicked.connect(self.addItem) # Remember to pass the definition/method, not the return value!self.selectImgBtn =self.findChild(QtWidgets.QPushButton, 'selectImgBtn') # Find the buttonself.selectImgBtn.clicked.connect(self.setImage) # Remember to pass the definition/method, not the return value!self.cnfBtn =self.findChild(QtWidgets.QPushButton, 'cnfBtn') # Find the buttonself.cnfBtn.clicked.connect(self.showDialog) # Remember to pass the definition/method, not the return value!# Adding other static input/output elementsself.input =self.findChild(QtWidgets.QLineEdit, 'input')
self.qlabel =self.findChild(QtWidgets.QLabel, 'qlabel')
self.lineEdit =self.findChild(QtWidgets.QLineEdit, 'lineEdit')
self.listWidget =self.findChild(QtWidgets.QListWidget, 'listWidget')
self.imageLbl =self.findChild(QtWidgets.QLabel, 'imageLbl')
# Adding Comboboxself.combo =self.findChild(QtWidgets.QComboBox, 'sComboBox') # Find the ComboBox# Adding static element to itself.combo.addItem("Sourav Ganguly")
self.combo.addItem("Kapil Dev")
self.combo.addItem("Sunil Gavaskar")
self.combo.addItem("M. S. Dhoni")
# Click Eventself.combo.activated[str].connect(self.onChanged) # Remember to pass the definition/method, not the return value!# Adding list Boxself.listwidget2 =self.findChild(QtWidgets.QListWidget, 'listwidget2') # Find the List# Adding static element to itself.listwidget2.insertItem(0, "Aamir Khan")
self.listwidget2.insertItem(1, "Shahruk Khan")
self.listwidget2.insertItem(2, "Salman Khan")
self.listwidget2.insertItem(3, "Hrittik Roshon")
self.listwidget2.insertItem(4, "Amitabh Bachhan")
# Click Eventself.listwidget2.clicked.connect(self.showIndividualElement)
# Adding Group Boxself.groupBox =self.findChild(QtWidgets.QGroupBox, 'groupBox') # Find the ComboBoxself.groupBox.setCheckable(True)
# Adding Individual Radio Buttonself.rdButton1 =self.findChild(QtWidgets.QRadioButton, 'rdButton1') # Find the buttonself.rdButton1.setChecked(True)
self.rdButton1.toggled.connect(lambda: self.printRadioButtonClick(self.rdButton1)) # Remember to pass the definition/method, not the return value!self.rdButton2 =self.findChild(QtWidgets.QRadioButton, 'rdButton2') # Find the buttonself.rdButton2.toggled.connect(lambda: self.printRadioButtonClick(self.rdButton2)) # Remember to pass the definition/method, not the return value!self.rdButton3 =self.findChild(QtWidgets.QRadioButton, 'rdButton3') # Find the buttonself.rdButton3.toggled.connect(lambda: self.printRadioButtonClick(self.rdButton3)) # Remember to pass the definition/method, not the return value!self.rdButton4 =self.findChild(QtWidgets.QRadioButton, 'rdButton4') # Find the buttonself.rdButton4.toggled.connect(lambda: self.printRadioButtonClick(self.rdButton4)) # Remember to pass the definition/method, not the return value!self.show()
defprintRadioButtonClick(self, radioOption):
if radioOption.text() =='China':
if radioOption.isChecked() ==True:
print(radioOption.text() +' is selected')
else:
print(radioOption.text() +' is deselected')
if radioOption.text() =='India':
if radioOption.isChecked() ==True:
print(radioOption.text() +' is selected')
else:
print(radioOption.text() +' is deselected')
if radioOption.text() =='Japan':
if radioOption.isChecked() ==True:
print(radioOption.text() +' is selected')
else:
print(radioOption.text() +' is deselected')
if radioOption.text() =='France':
if radioOption.isChecked() ==True:
print(radioOption.text() +' is selected')
else:
print(radioOption.text() +' is deselected')
defprintButtonClick(self):
# This is executed when the button is pressedprint('Input text:'+self.input.text())
defclearButtonClick(self):
# This is executed when the button is pressedself.input.clear()
defonChanged(self, text):
self.qlabel.setText(text)
self.qlabel.adjustSize()
self.lineEdit.clear() # Clear the textdefaddItem(self):
value =self.lineEdit.text() # Get the value of the lineEditself.lineEdit.clear() # Clear the textself.listWidget.addItem(value) # Add the value we got to the listdefsetImage(self):
fileName, _ = QtWidgets.QFileDialog.getOpenFileName(None, "Select Image", "", "Image Files (*.png *.jpg *jpeg *.bmp);;All Files (*)") # Ask for fileif fileName: # If the user gives a file
pixmap = QtGui.QPixmap(fileName) # Setup pixmap with the provided image
pixmap = pixmap.scaled(self.imageLbl.width(), self.imageLbl.height(), QtCore.Qt.KeepAspectRatio) # Scale pixmapself.imageLbl.setPixmap(pixmap) # Set the pixmap onto the labelself.imageLbl.setAlignment(QtCore.Qt.AlignCenter) # Align the label to centerdefshowDialog(self):
msgBox = QMessageBox()
msgBox.setIcon(QMessageBox.Information)
msgBox.setText("Message box pop up window")
msgBox.setWindowTitle("MessageBox Example")
msgBox.setStandardButtons(QMessageBox.Ok | QMessageBox.Cancel)
msgBox.buttonClicked.connect(self.msgButtonClick)
returnValue = msgBox.exec()
if returnValue == QMessageBox.Ok:
print('OK clicked')
defmsgButtonClick(self, i):
print("Button clicked is:", i.text())
defshowIndividualElement(self, qmodelindex):
item =self.listwidget2.currentItem()
print(item.text())
if __name__ =="__main__":
importsys
app = QtWidgets.QApplication(sys.argv)
window = Ui()
window.show()
sys.exit(app.exec_())
Let us explore a few key lines from this script. Rests are almost identical.
# Loading the Graphical Design without# converting it to any kind of Python codeuic.loadUi('basicAdv.ui', self)
Loading the GUI created using Qt Designer into the Python environment.
# Adding all the essential buttonsself.prtBtn = self.findChild(QtWidgets.QPushButton, 'prtBtn') # Find the buttonself.prtBtn.clicked.connect(self.printButtonClick) # Remember to pass the definition/method, not the return value!
In this case, we’re dynamically binding the component from the GUI by using the findChild method & then on the next line, we’re invoking the appropriate event associated with that. In this case, it is – self.printButtonClick.
The printButtonClick as mentioned earlier is a method & that contains the following snippet –
def printButtonClick(self):
    # This is executed when the button is pressed
    print('Input text:' + self.input.text())
As you can see, this event will capture the text from the input textbox & print it on our terminal.
Here is the snippet for those widgets, which is part of only input/output & they generally don’t have an event of their own. But, we need to bind them with our Python application.
Group Box, along with the radio button, works slightly different than our drop-down list.
For each radio button, we’ll have a dedicated text value that represents a different country in this context.
And, our application will bind all the radio button & then they will use one standard method for all of these four options as shown below –
# Adding Individual Radio Buttonself.rdButton1 = self.findChild(QtWidgets.QRadioButton, 'rdButton1') # Find the buttonself.rdButton1.setChecked(True)self.rdButton1.toggled.connect(lambda: self.printRadioButtonClick(self.rdButton1)) # Remember to pass the definition/method, not the return value!self.rdButton2 = self.findChild(QtWidgets.QRadioButton, 'rdButton2') # Find the buttonself.rdButton2.toggled.connect(lambda: self.printRadioButtonClick(self.rdButton2)) # Remember to pass the definition/method, not the return value!self.rdButton3 = self.findChild(QtWidgets.QRadioButton, 'rdButton3') # Find the buttonself.rdButton3.toggled.connect(lambda: self.printRadioButtonClick(self.rdButton3)) # Remember to pass the definition/method, not the return value!self.rdButton4 = self.findChild(QtWidgets.QRadioButton, 'rdButton4') # Find the buttonself.rdButton4.toggled.connect(lambda: self.printRadioButtonClick(self.rdButton4)) # Remember to pass the definition/method, not the return value!
Also, note that, by default, rdButton1 is set to True i.e., it will be selected when the form load initially.
Let’s explore the printRadioButtonClick event.
def printRadioButtonClick(self, radioOption):

    if radioOption.text() == 'China':
        if radioOption.isChecked() == True:
            print(radioOption.text() + ' is selected')
        else:
            print(radioOption.text() + ' is deselected')

    if radioOption.text() == 'India':
        if radioOption.isChecked() == True:
            print(radioOption.text() + ' is selected')
        else:
            print(radioOption.text() + ' is deselected')

    if radioOption.text() == 'Japan':
        if radioOption.isChecked() == True:
            print(radioOption.text() + ' is selected')
        else:
            print(radioOption.text() + ' is deselected')

    if radioOption.text() == 'France':
        if radioOption.isChecked() == True:
            print(radioOption.text() + ' is selected')
        else:
            print(radioOption.text() + ' is deselected')
This will capture the radio button option & based on the currently clicked button, it will fetch the text out of it. Finally, that will match with the logic here & based on that, our application will display the output.
Finally, the Image process is slightly different.
Initially, our application will load the component from the .ui file & bind them with the Python environment –
Image load option will only work when the user clicks the button that triggers the following sets of actions –
self.selectImgBtn = self.findChild(QtWidgets.QPushButton, 'selectImgBtn') # Find the buttonself.selectImgBtn.clicked.connect(self.setImage) # Remember to pass the definition/method, not the return value!
Let’s explore the setImage method –
def setImage(self):
    fileName, _ = QtWidgets.QFileDialog.getOpenFileName(None, "Select Image", "", "Image Files (*.png *.jpg *jpeg *.bmp);;All Files (*)") # Ask for file
    if fileName: # If the user gives a file
        pixmap = QtGui.QPixmap(fileName) # Setup pixmap with the provided image
        pixmap = pixmap.scaled(self.imageLbl.width(), self.imageLbl.height(), QtCore.Qt.KeepAspectRatio) # Scale pixmap
        self.imageLbl.setPixmap(pixmap) # Set the pixmap onto the label
        self.imageLbl.setAlignment(QtCore.Qt.AlignCenter) # Align the label to center
This will prompt the corresponding dialogue box for choosing the right images out of the respective O/S.
Last but not least, the use of MsgBox, which can be extremely useful for many GUI based programming.
This msgbox doesn’t exist in the form. However, we’re creating it on the event of the “Confirm Button” as shown below –
self.cnfBtn = self.findChild(QtWidgets.QPushButton, 'cnfBtn') # Find the buttonself.cnfBtn.clicked.connect(self.showDialog) # Remember to pass the definition/method, not the return value!
This will prompt the showDialog method to trigger –
def showDialog(self):
    msgBox = QMessageBox()
    msgBox.setIcon(QMessageBox.Information)
    msgBox.setText("Message box pop up window")
    msgBox.setWindowTitle("MessageBox Example")
    msgBox.setStandardButtons(QMessageBox.Ok | QMessageBox.Cancel)
    msgBox.buttonClicked.connect(self.msgButtonClick)

    returnValue = msgBox.exec()
    if returnValue == QMessageBox.Ok:
        print('OK clicked')
And, based on your options (“OK”/”Cancel”), it will prompt the final captured message in your console.
Let’s explore the videos of output from Windows O/S –
Let’s explore the video output from MAC VM –
For more information on this package – please check the following link.
So, as you can see, finally we’ve achieved it. We’ve demonstrated cross-platform GUI applications using native Python. And, here we didn’t even convert the ui design file to python script either.
Please share your feedback.
I’ll be posting another new post in the coming days. Till then, Happy Avenging! 😀
Note: All the data posted here are representational data & available over the internet & for educational purpose only.
Today, I’ll present a way to get the best route from Indian Railways train between two specific sources & destination using third-party API.
This approach is particularly beneficial if you want to integrate this logic in Azure Function or Lambda Function or any serverless functions.
Before we dig into the details. Let us explore what kind of cloud-based architecture we can implement this.
Fig: 1 (Cloud Architecture)
In this case, I’ve considered Azure as the implementation platform.
Let’s discuss how the events will take place. At first, a user searches for the best routes between two fixed stations. The user has to provide the source & destination stations. The request will go through the Azure Firewall after validating the initial authentication. As part of the API service, it will check for similar queries & if it is there, then it will fetch it from the cache & send it back to the user through their mobile application. However, for the first time, it will retrieve the information from the DB & keep a copy in the cache. This part also managed through a load balancer for high-level availability. However, periodically system will push the data from the cache to the DB with the updated information.
Let’s see the program directory structure –
Let’s discuss our code –
1. clsConfig.py (This script contains all the parameters for the main Indian Railway API & try to get the response between two railway stations. Hence, the name comes into the picture.)
################################################## Written By: SATYAKI DE ######## Written On: 12-Oct-2019 ######## ######## Objective: This script is a config ######## file, contains all the keys for ######## azure cosmos db. Application will ######## process these information & perform ######## various CRUD operation on Cosmos DB. ##################################################importosimportplatformasplclassclsConfig(object):
Curr_Path = os.path.dirname(os.path.realpath(__file__))
os_det = pl.system()
if os_det =="Windows":
sep ='\\'else:
sep ='/'
config = {
'APP_ID': 1,
'URL': "https://trains.p.rapidapi.com/",
'RAPID_API_HOST': "trains.p.rapidapi.com",
'RAPID_API_KEY': "hrfjjdfjfjfjfjxxxxxjffjjfjfjfjfjfjfjf",
'RAPID_API_TYPE': "application/json",
'ARCH_DIR': Curr_Path + sep +'arch'+ sep,
'PROFILE_PATH': Curr_Path + sep +'profile'+ sep,
'LOG_PATH': Curr_Path + sep +'log'+ sep,
'REPORT_PATH': Curr_Path + sep +'report',
'APP_DESC_1': 'Indian Railway Train Schedule Search',
'DEBUG_IND': 'N',
'INIT_PATH': Curr_Path,
'COL_LIST': ['name','train_num','train_from','train_to','classes','departTime','arriveTime','Mon','Tue','Wed','Thu','Fri','Sat','Sun']
}
As of now, I’ve replaced the API Key with the dummy value.
2. clsIndianRailway.py (This script will invoke the main Indian Railway API & try to get the response between two railway stations. Hence, the name comes into the picture.)
The first four lines are to receive the parameter values. Our application needs to frame the search query, which is done in the IPayload variable. After that, our app will convert it into a json object type.
Now, the application will prepare the headers & send the request & received the response. Finally, that response will be sent by this script to the main callee application after extracting part of the response & converting that back to JSON are as follows –
3. callIndianRailwayAPI.py (This is the main script which invokes the main Indian Railway API & tries to get the response between two railway stations. Hence, the name comes into the picture.)
################################################## Written By: SATYAKI DE ######## Written On: 20-Dec-2019 ######## Modified On 20-Dec-2019 ######## ######## Objective: Main calling scripts. ##################################################fromclsConfigimport clsConfig as cf
importpandasaspimportclsLasclimportloggingimportdatetimeimportjsonimportclsIndianRailwayasctimportreimportnumpyasnp# Disbling Warningdefwarn(*args, **kwargs):
passimportwarnings
warnings.warn = warn
# Lookup functions from# Azure cloud SQL DB
var = datetime.datetime.now().strftime("%Y-%m-%d_%H-%M-%S")
defgetArriveTimeOnly(row):
try:
# Using regular expression to fetch time part only
lkp_arriveTime =str(row['arriveTime'])
str_arr_time, remain = lkp_arriveTime.split('+')
return str_arr_time
exceptExceptionas e:
x =str(e)
str_arr_time =''return str_arr_time
defgetArriveDateDiff(row):
try:
# Using regular expression to fetch time part only
lkp_arriveTime =str(row['arriveTime'])
first_half, str_date_diff_init = lkp_arriveTime.split('+')
# Replacing the text part from it & only capturing the integer part
str_date_diff =int(re.sub(r"[a-z]","",str_date_diff_init, flags=re.I))
return str_date_diff
exceptExceptionas e:
x =str(e)
str_date_diff =0return str_date_diff
defgetArriveTimeDiff(row):
try:
# Using regular expression to fetch time part only
lkp_arriveTimeM =str(row['arriveTimeM'])
str_time_diff_init =int(re.sub(r'[^\w\s]', '', lkp_arriveTimeM))
# Replacing the text part from it & only capturing the integer part
str_time_diff = (2400- str_time_diff_init)
return str_time_diff
exceptExceptionas e:
x =str(e)
str_time_diff =0return str_time_diff
defmain():
try:
dfSrc = p.DataFrame()
df_ret = p.DataFrame()
ret_2 =''
debug_ind ='Y'
col_list = cf.config['COL_LIST']
general_log_path =str(cf.config['LOG_PATH'])
# Enabling Logging Info
logging.basicConfig(filename=general_log_path +'consolidatedIR.log', level=logging.INFO)
# Initiating Log Class
l = cl.clsL()
# Moving previous day log files to archive directory
arch_dir = cf.config['ARCH_DIR']
log_dir = cf.config['LOG_PATH']
tmpR0 ="*"*157
logging.info(tmpR0)
tmpR9 ='Start Time: '+str(var)
logging.info(tmpR9)
logging.info(tmpR0)
print("Archive Directory:: ", arch_dir)
print("Log Directory::", log_dir)
tmpR1 ='Log Directory::'+ log_dir
logging.info(tmpR1)
# Query using parameters
rawQry =str(input('Please enter the name of the train service that you want to find out (Either by Name or by Number): '))
x1 = ct.clsIndianRailway()
ret_2 = x1.searchQry(rawQry)
# Capturing the JSON Payload
res = json.loads(ret_2)
# Converting dictionary to Pandas Dataframe# df_ret = p.read_json(ret_2, orient='records')
df_ret = p.io.json.json_normalize(res)
df_ret.columns = df_ret.columns.map(lambda x: x.split(".")[-1])
# Resetting the column orders as per JSON# df_ret = df_ret[list(res[0].keys())]
column_order = col_list
df_mod_ret = df_ret.reindex(column_order, axis=1)
# Sorting the source data for better viewing
df_mod_resp = df_mod_ret.sort_values(by=['train_from','train_to','train_num'])
l.logr('1.IndianRailway_'+ var +'.csv', debug_ind, df_mod_resp, 'log')
# Fetching Data for Delhi To Howrah
df_del_how = df_mod_resp[(df_mod_resp['train_from'] =='NDLS') & (df_mod_resp['train_to'] =='HWH')]
l.logr('2.IndianRailway_Delhi2Howrah_'+ var +'.csv', debug_ind, df_del_how, 'log')
# Splitting Arrive time into two separate fields for better calculation
df_del_how['arriveTimeM'] = df_del_how.apply(lambda row: getArriveTimeOnly(row), axis=1)
df_del_how['arriveTimeDayDiff'] = df_del_how.apply(lambda row: getArriveDateDiff(row), axis=1)
df_del_how['arriveTimeDiff'] = df_del_how.apply(lambda row: getArriveTimeDiff(row), axis=1)
l.logr('3.IndianRailway_Del2How_Mod_'+ var +'.csv', debug_ind, df_del_how, 'log')
# To fetch the best route which saves time
lstTimeDayDiff = df_del_how['arriveTimeDayDiff'].values.tolist()
min_lstTimeDayDiff =int(min(lstTimeDayDiff))
df_min_timedaydiff = df_del_how[(df_del_how['arriveTimeDayDiff'] == min_lstTimeDayDiff)]
l.logr('4.IndianRailway_Del2How_TimeCalc_'+ var +'.csv', debug_ind, df_min_timedaydiff, 'log')
# Now application will check the maximum arrivetimediff, this will bring the record# which arrives early at Howrah station
lstTimeDiff = df_min_timedaydiff['arriveTimeDiff'].values.tolist()
max_lstTimeDiff =int(max(lstTimeDiff))
df_best_route = df_min_timedaydiff[(df_min_timedaydiff['arriveTimeDiff'] == max_lstTimeDiff)]
# Dropping unwanted columns
df_best_route.drop(columns=['arriveTimeM'], inplace=True)
df_best_route.drop(columns=['arriveTimeDayDiff'], inplace=True)
df_best_route.drop(columns=['arriveTimeDiff'], inplace=True)
l.logr('5.IndianRailway_Del2How_BestRoute_'+ var +'.csv', debug_ind, df_best_route, 'log')
print("-"*60)
print('Realtime Indian Railway Data:: ')
logging.info('Realtime Indian Railway Data:: ')
print(df_mod_resp)
print()
print('Best Route from Delhi -> Howrah:: ')
print(df_best_route)
print()
# Checking execution status
ret_val_2 = df_best_route.shape[0]
if ret_val_2 ==0:
print("Indian Railway hasn't returned any rows. Please check your queries!")
logging.info("Indian Railway hasn't returned any rows. Please check your queries!")
print("*"*157)
logging.info(tmpR0)
else:
print("Successfuly row feteched!")
logging.info("Successfuly row feteched!")
print("*"*157)
logging.info(tmpR0)
print('Finding Story points..')
print("*"*157)
logging.info('Finding Story points..')
logging.info(tmpR0)
tmpR10 ='End Time: '+str(var)
logging.info(tmpR10)
logging.info(tmpR0)
exceptValueError:
print("No relevant data to proceed!")
logging.info("No relevant data to proceed!")
exceptExceptionas e:
print("Top level Error: args:{0}, message{1}".format(e.args, e.message))
if __name__ =="__main__":
main()
Key snippet to explore –
# Query using parametersrawQry = str(input('Please enter the name of the train service that you want to find out (Either by Name or by Number): '))
In this case, we make it interactive mode. However, in the actual scenario, you would receive these values from your mobile application.
# Capturing the JSON Payload res = json.loads(ret_2)
The above four lines initially invoke the API & receive the JSON response.
# Converting dictionary to Pandas Dataframedf_ret = p.io.json.json_normalize(res)df_ret.columns = df_ret.columns.map(lambda x: x.split(".")[-1])# Resetting the column orders as per JSONcolumn_order = col_listdf_mod_ret = df_ret.reindex(column_order, axis=1)# Sorting the source data for better viewingdf_mod_resp = df_mod_ret.sort_values(by=['train_from','train_to','train_num'])
In these last five lines, our application will convert the JSON & serialize it into pandas dataframe, which is sorted after that.
The result will look like this –
This is exceptionally critical, as this will allow you to achieve your target. Without flattening the data, you won’t get to your goal.
# Fetching Data for Delhi To Howrahdf_del_how = df_mod_resp[(df_mod_resp['train_from'] == 'NDLS') & (df_mod_resp['train_to'] == 'HWH')]
As the line suggested, our application will pick-up only those records between New Delhi & Howrah. Thus, we’ve used our filter to eliminate additional records. And, the data will look like this –
Now, we need to identify the minimum time taken by anyone of the two records. For that, we’ll be doing some calculations to fetch the minimum time taken by the application.
# Splitting Arrive time into two separate fields for better calculationdf_del_how['arriveTimeM'] = df_del_how.apply(lambda row: getArriveTimeOnly(row), axis=1)df_del_how['arriveTimeDayDiff'] = df_del_how.apply(lambda row: getArriveDateDiff(row), axis=1)df_del_how['arriveTimeDiff'] = df_del_how.apply(lambda row: getArriveTimeDiff(row), axis=1)
To do that, we’ll be generating a couple of derived columns (shown above), which we’ll be using the fetch the shortest duration. And, the data should look like this –
These are the two fields, which we’re using for our calculation. First, we’re splitting arriveTime into two separate columns i.e. arriveTimeM & arriveTimeDayDiff. However, arriveTimeDiff is a calculated field.
So, our logic to find the best routes –
arriveTimeDayDiff = Take the minimum of the records. If you have multiple candidates, then we’ll pick all of them. In this case, we’ll get two records.
ArrivalDiff = (24:00 – <Train’s Arrival Time>), then take the maximum of the value
Note that, in this case, we haven’t considered the departure time. You can add that logic to improvise & correct your prediction.
The above steps can be seen in the following snippet –
# To fetch the best route which saves timelstTimeDayDiff = df_del_how['arriveTimeDayDiff'].values.tolist()min_lstTimeDayDiff = int(min(lstTimeDayDiff))df_min_timedaydiff = df_del_how[(df_del_how['arriveTimeDayDiff'] == min_lstTimeDayDiff)]l.logr('4.IndianRailway_Del2How_TimeCalc_' + var + '.csv', debug_ind, df_min_timedaydiff, 'log')# Now application will check the maximum arrivetimediff, this will bring the record# which arrives early at Howrah stationlstTimeDiff = df_min_timedaydiff['arriveTimeDiff'].values.tolist()max_lstTimeDiff = int(max(lstTimeDiff))df_best_route = df_min_timedaydiff[(df_min_timedaydiff['arriveTimeDiff'] == max_lstTimeDiff)]
Let’s see how it runs –
As you can see that NDLS (New Delhi), we’ve three records marked in the GREEN square box. However, as destination HWH (Howrah), we’ve only two records marked in the RED square box. However, as part of our calculation, we’ll pick the record marked with the BLUE square box.
Let’s see how the log directory generates all the files –
Let’s see the final output in our csv file –
So, finally, we’ve achieved it. 😀
Let me know – how do you like this post. Please share your suggestion & comments.
I’ll be back with another installment from the Python verse.
Till then – Happy Avenging!
Note: All the data posted here are representational data & available over the internet & for educational purpose only.
In the above function, we’ve prepared a dummy calculation logic for TAX calculation. And, finally, we’ll be extracting two digits numeric digits after decimal by invoking the two_digit_decimal function.
def two_digit_decimal(self, n1):
    n = round(n1, 2)
    return n
This function will return two digits after decimal places.
In the above function, we’ve prepared a dummy calculation logic for TAX calculation. And, finally, we’ll be extracting two digits numeric digits after decimal by invoking the two_digit_decimal function.
Let’s run our application –
Let’s provide input say 1234 as shown in the above figures & click the Generate Tax button marked in RED. This will prompt the following screen.
Let’s explore if someone provides invalid input –
As expected, this will throw a proper warning to its application user.
So, we’ve done it. Building our first python based GUI application across multiple platforms.
Please share your review.
So, we’ll come out with another new post in the coming days!
N.B.: This is demonstrated for RnD/study purposes. All the data posted here are representational data & available over the internet & for educational purpose only.
Please find the link of the PyPI package of new enhanced JSON library on Python. This is particularly very useful as I’ve accommodated the following features into it.
distinct
nvl
partition_by
regex_like
regex_replace
regex_substr
All these functions can be used over JSON payload through python. I’ll discuss this in details in my next blog post.
However, I would like to suggest this library that will be handy for NoSQL databases like Cosmos DB. Now, you can quickly implement many of these features such as distinct, partitioning & regular expressions with less effort.




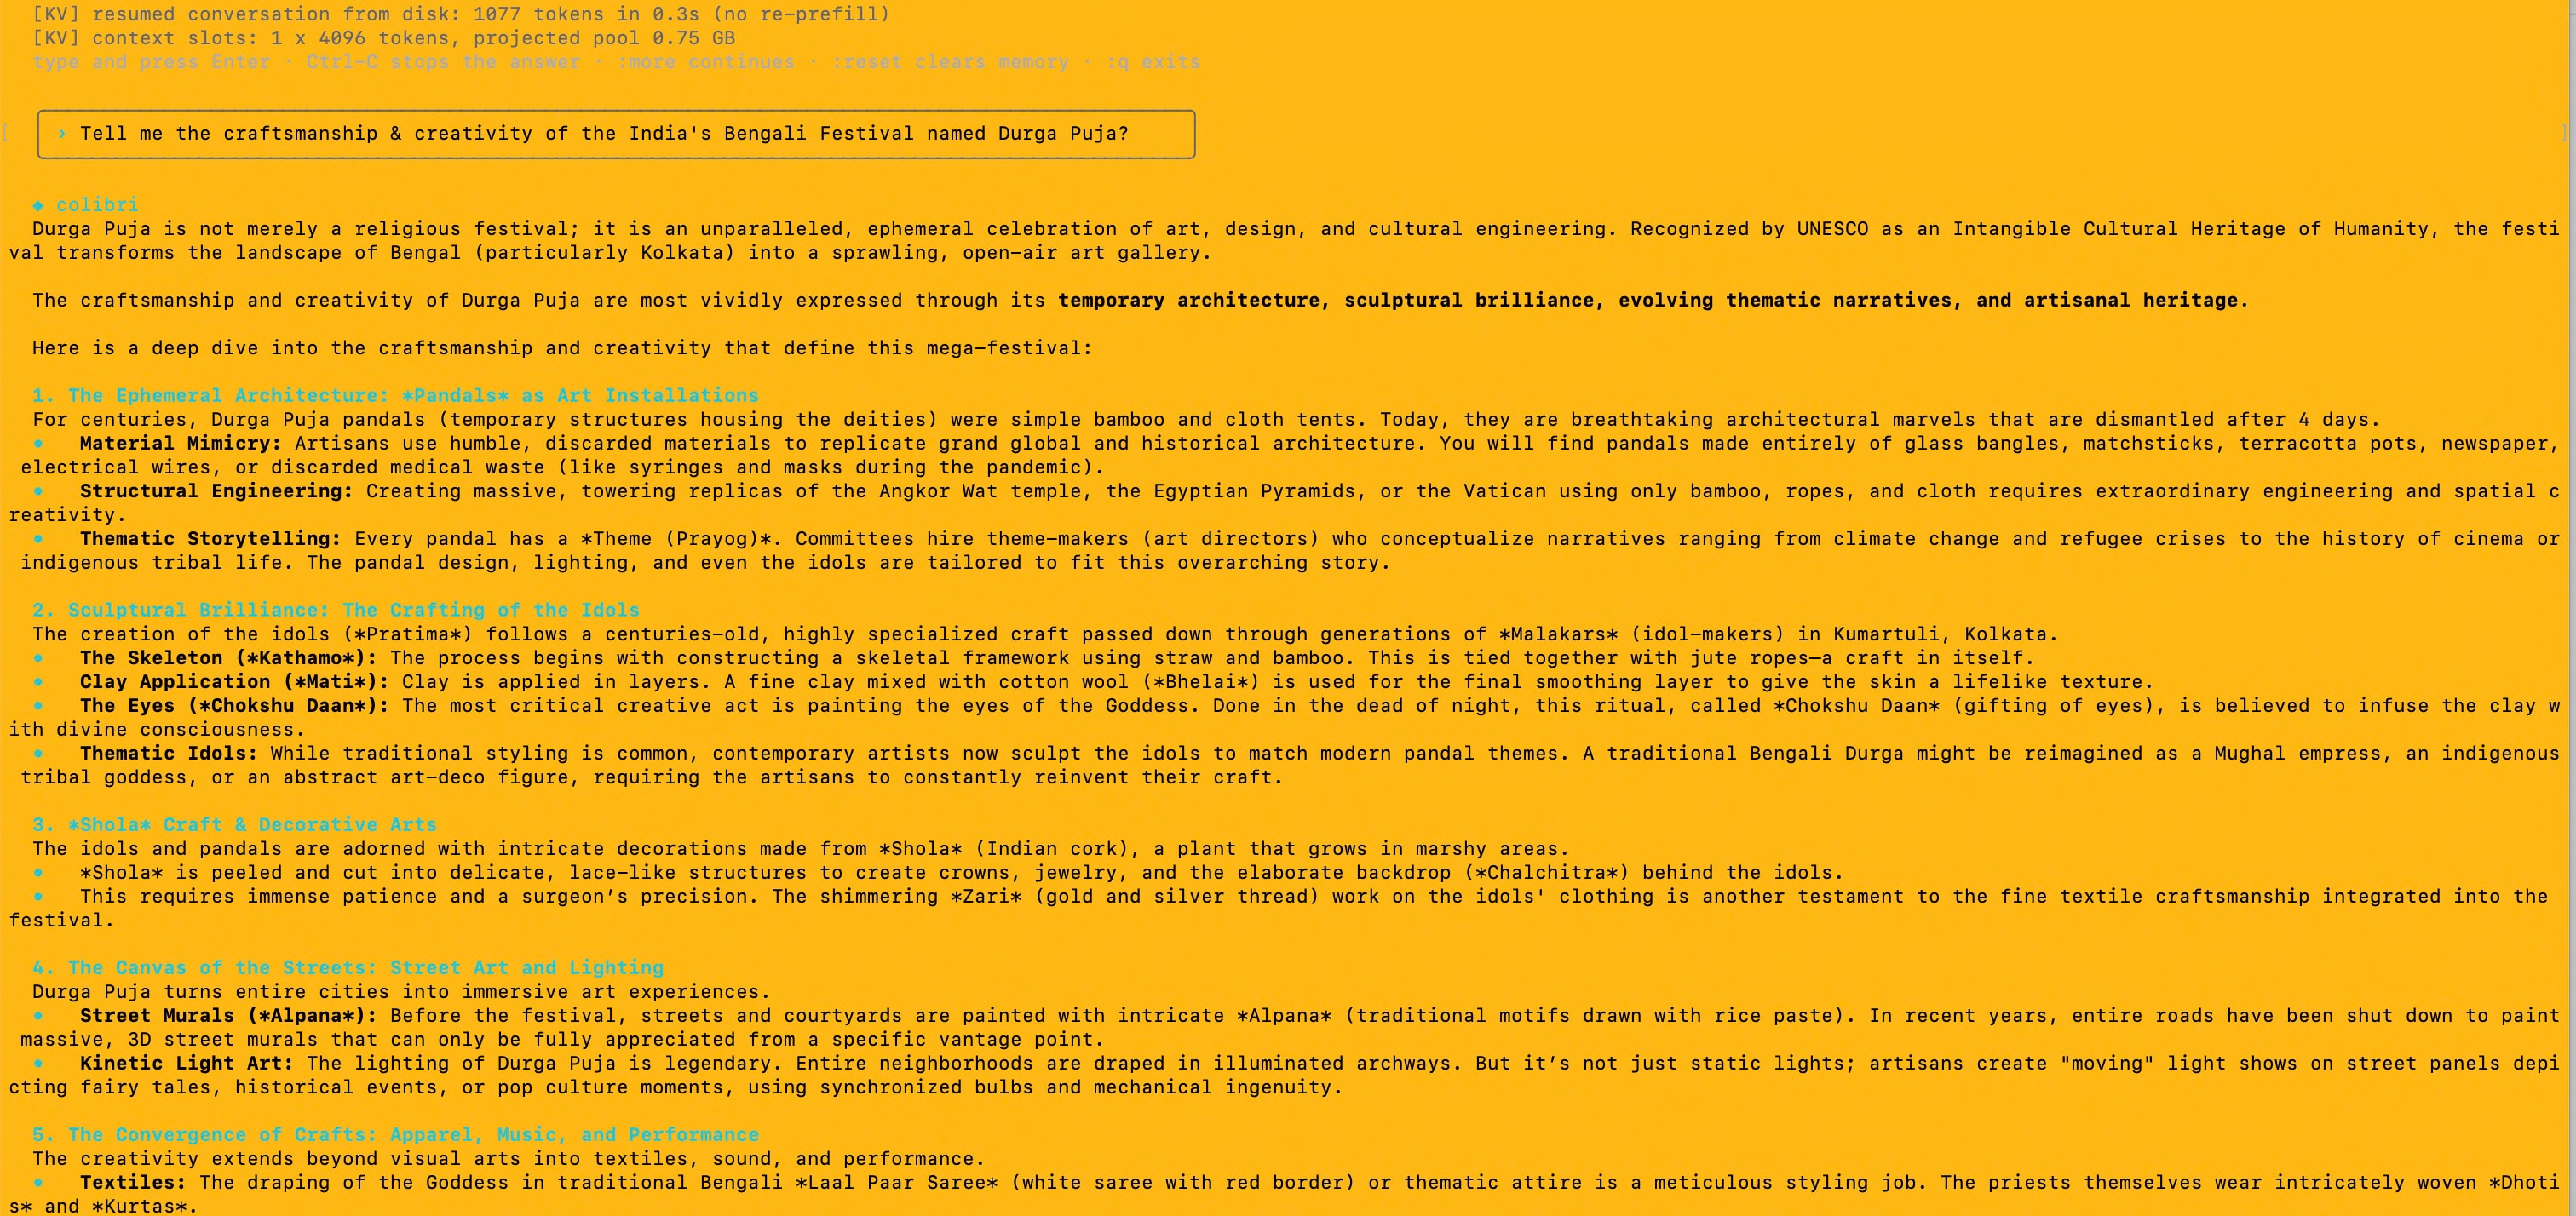


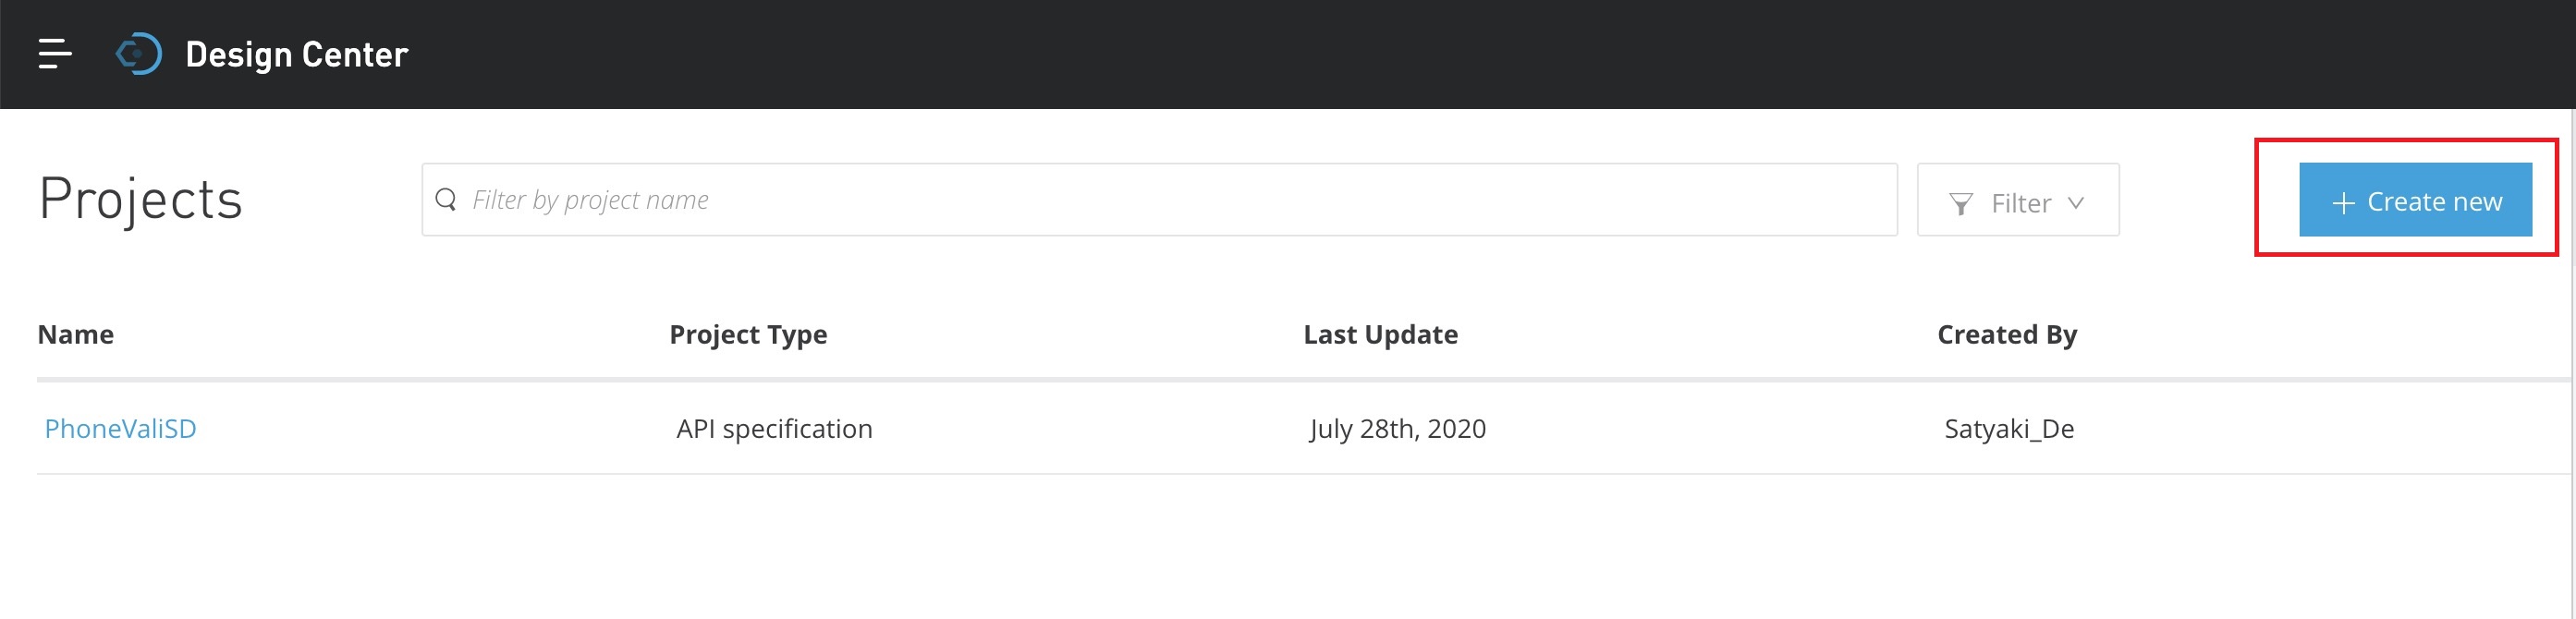
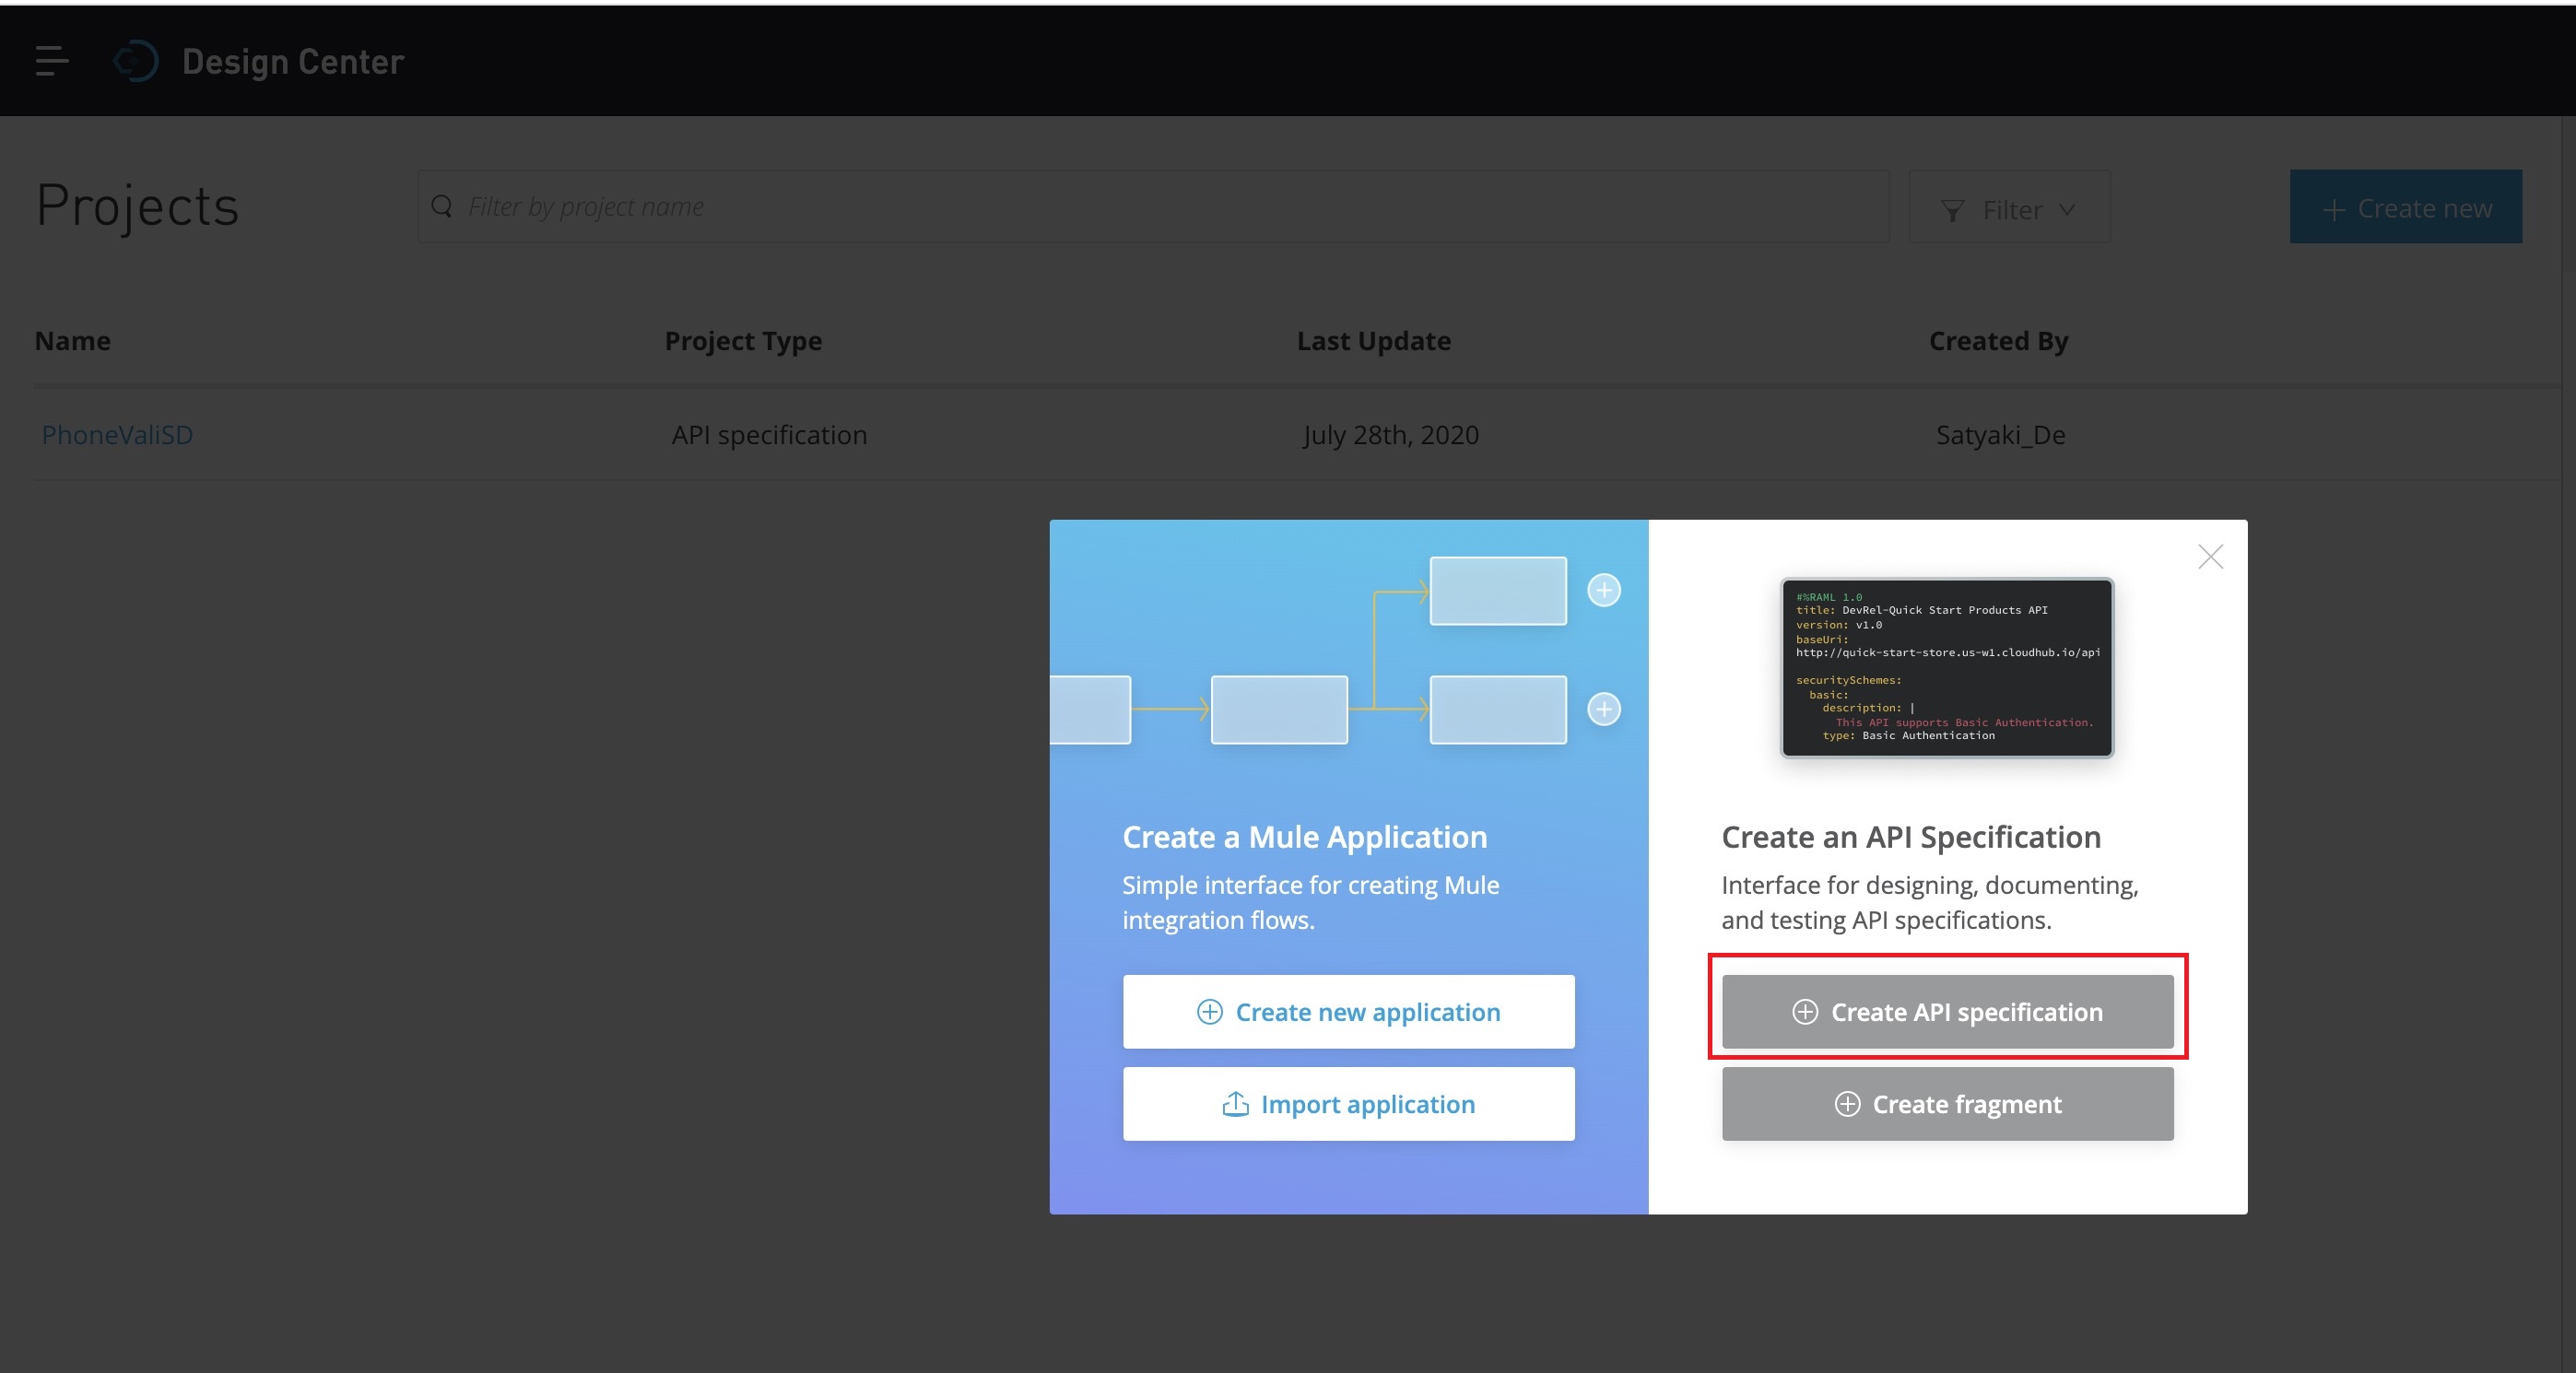
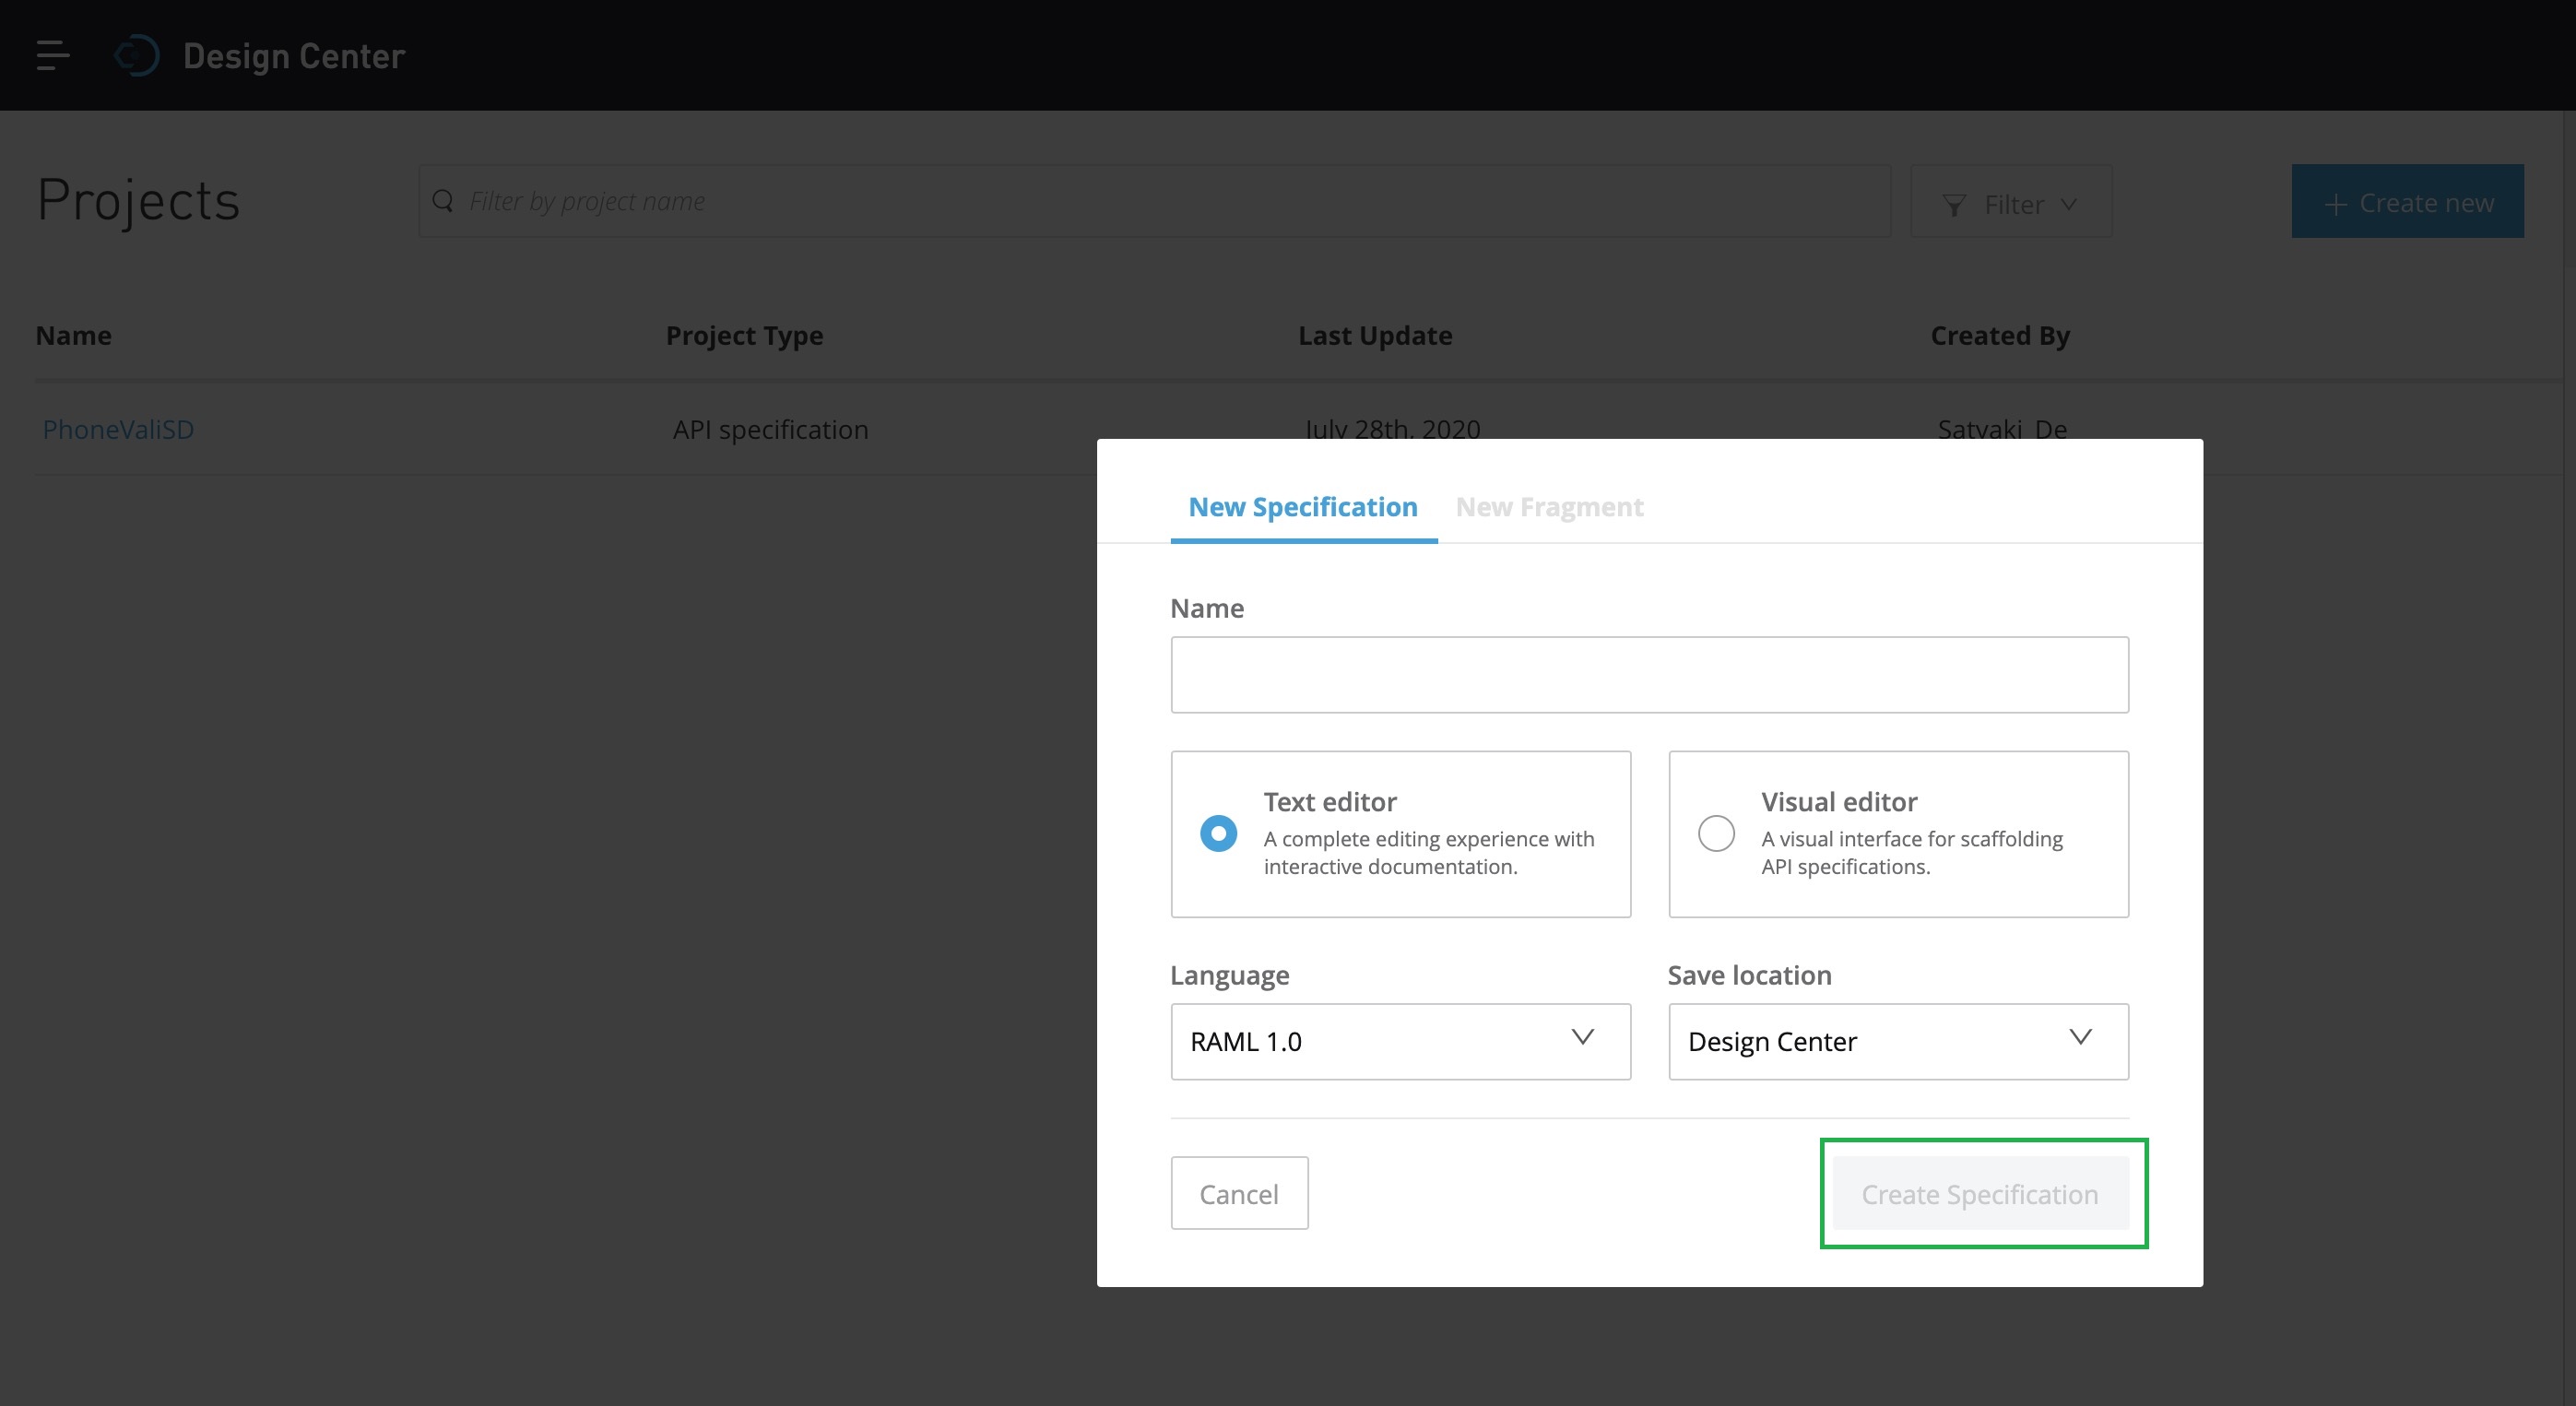
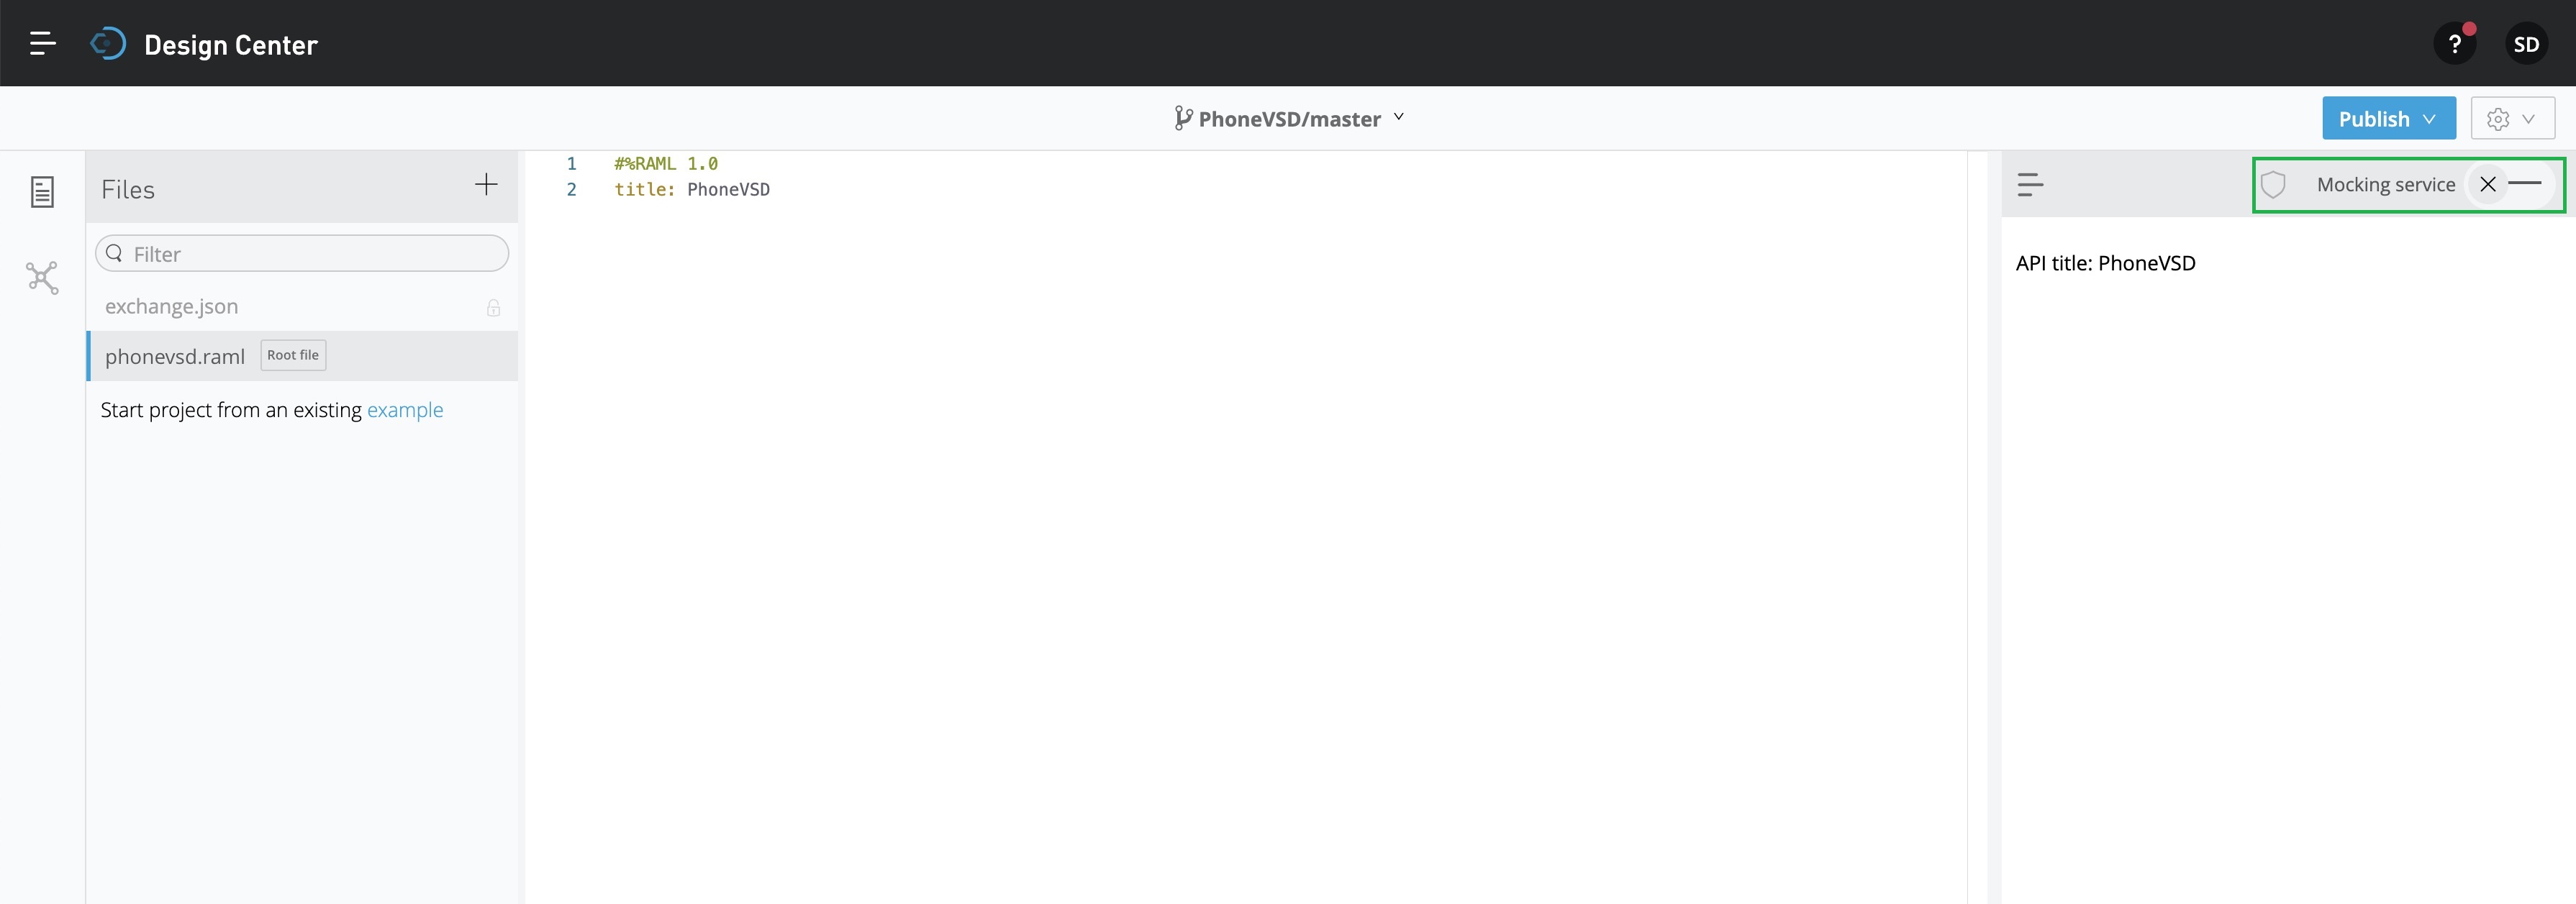
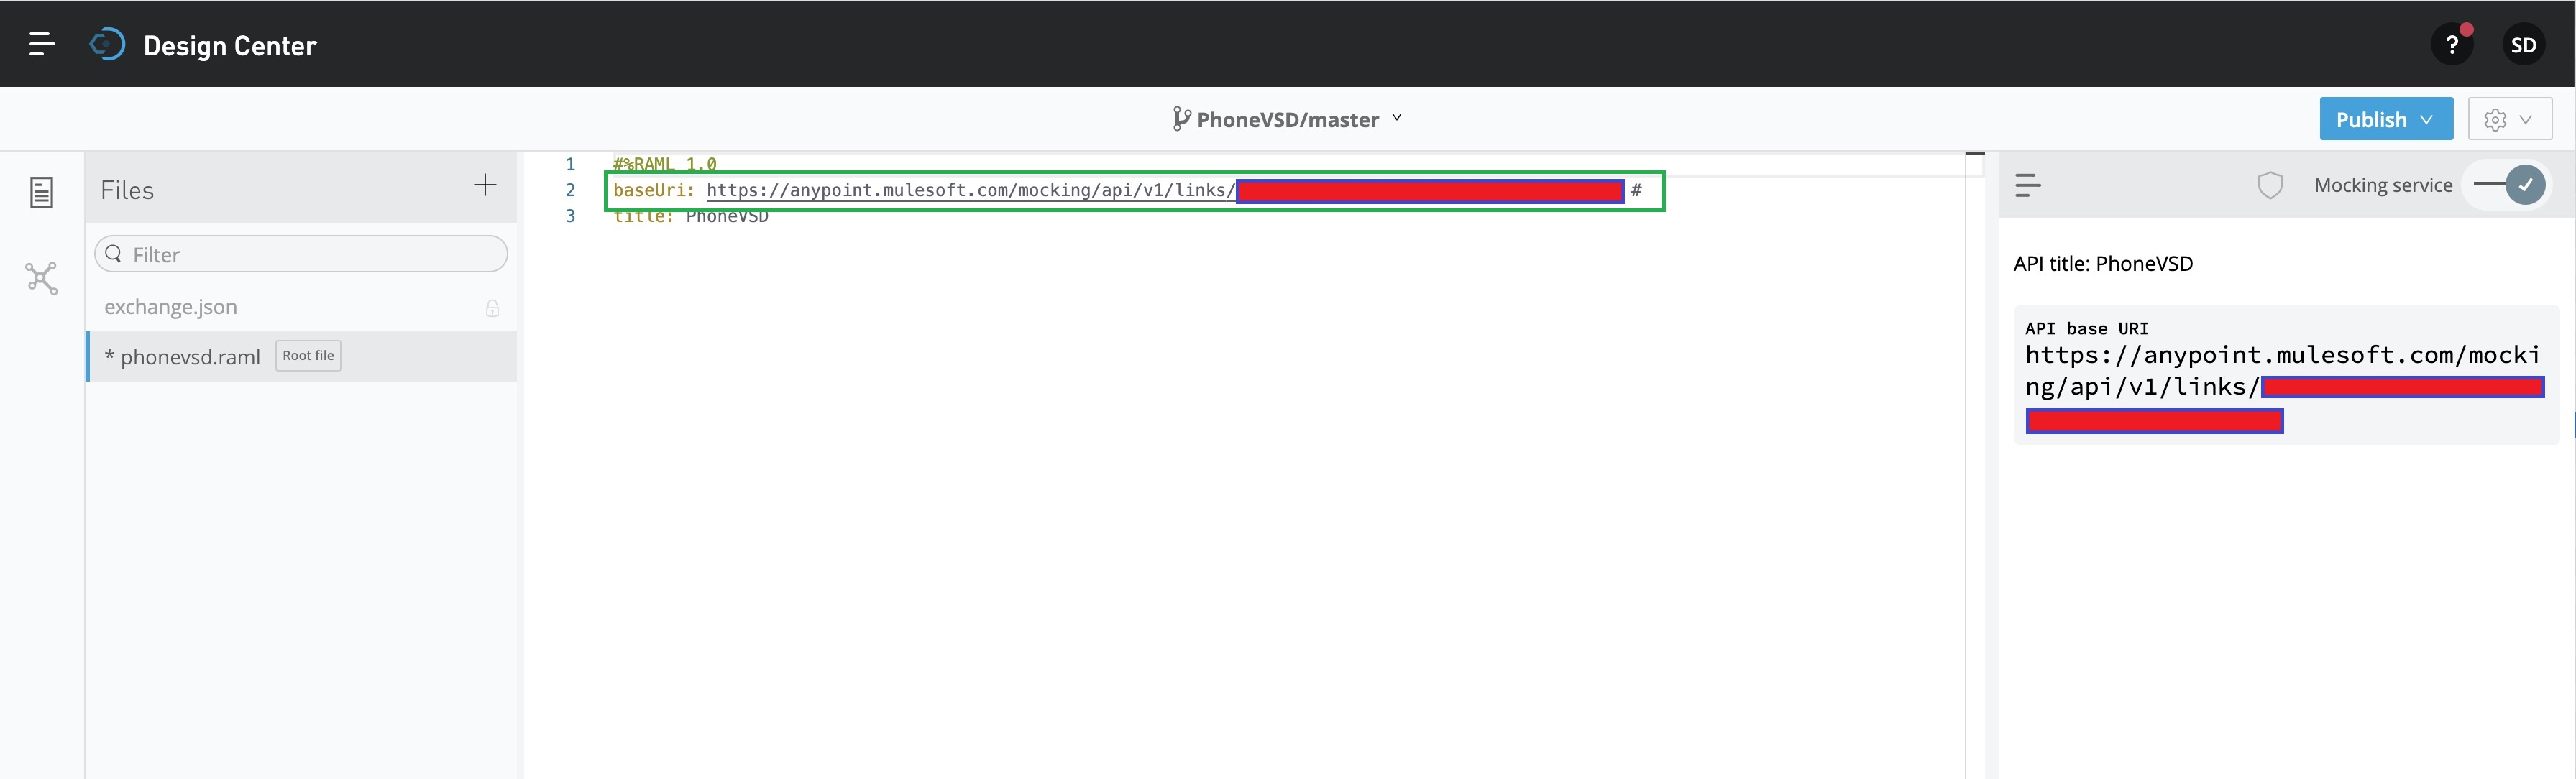
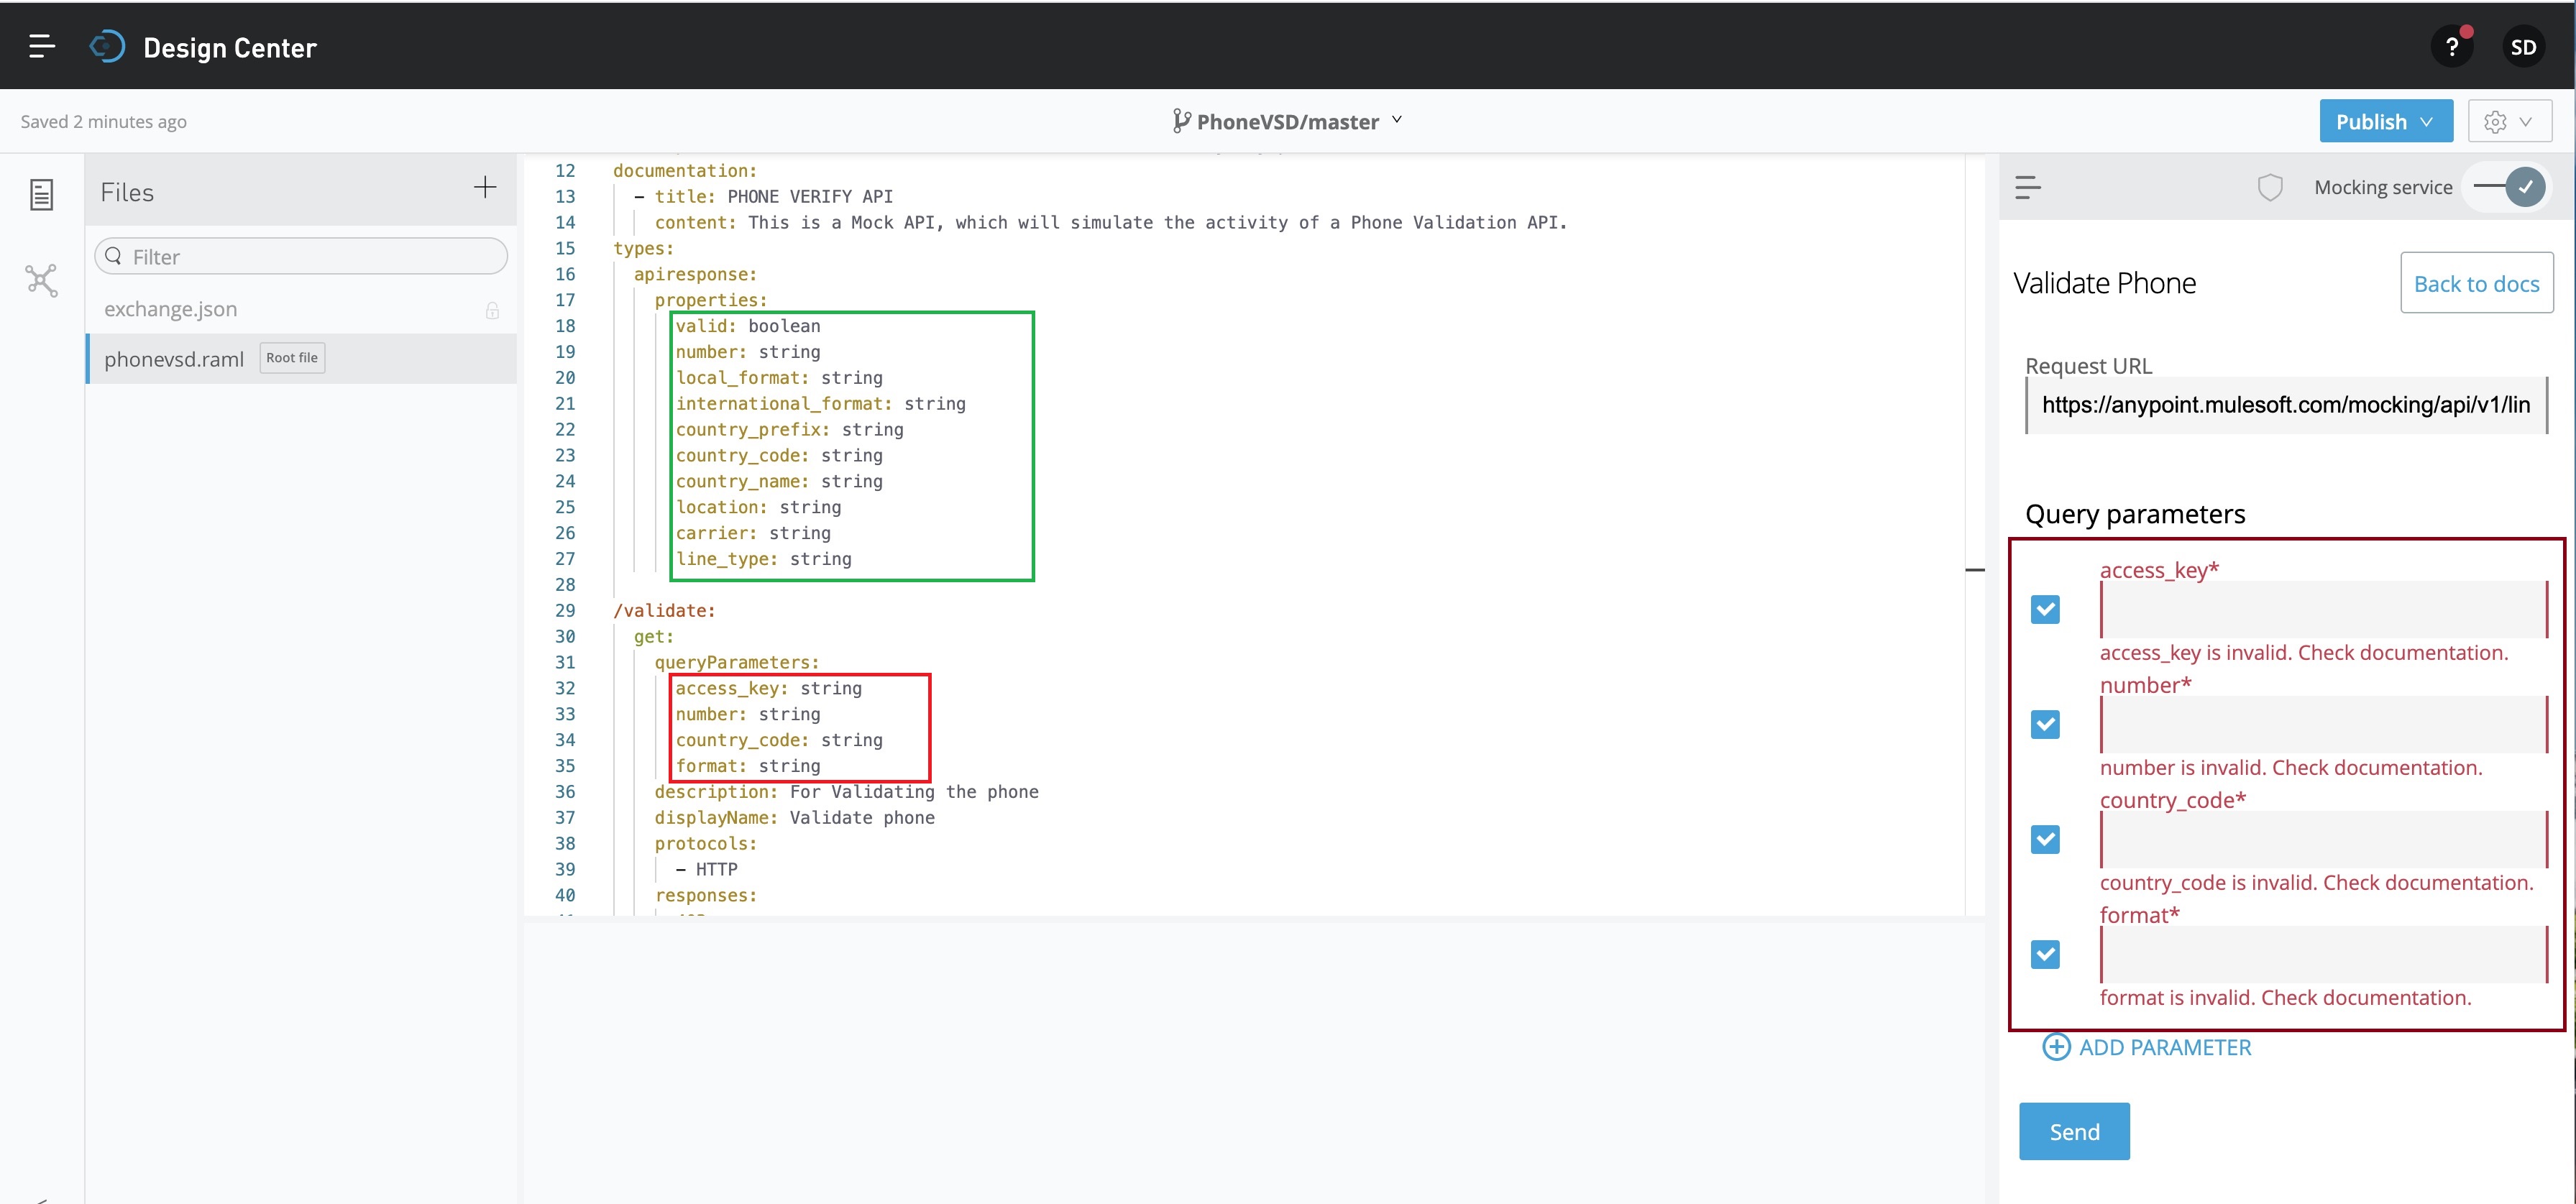
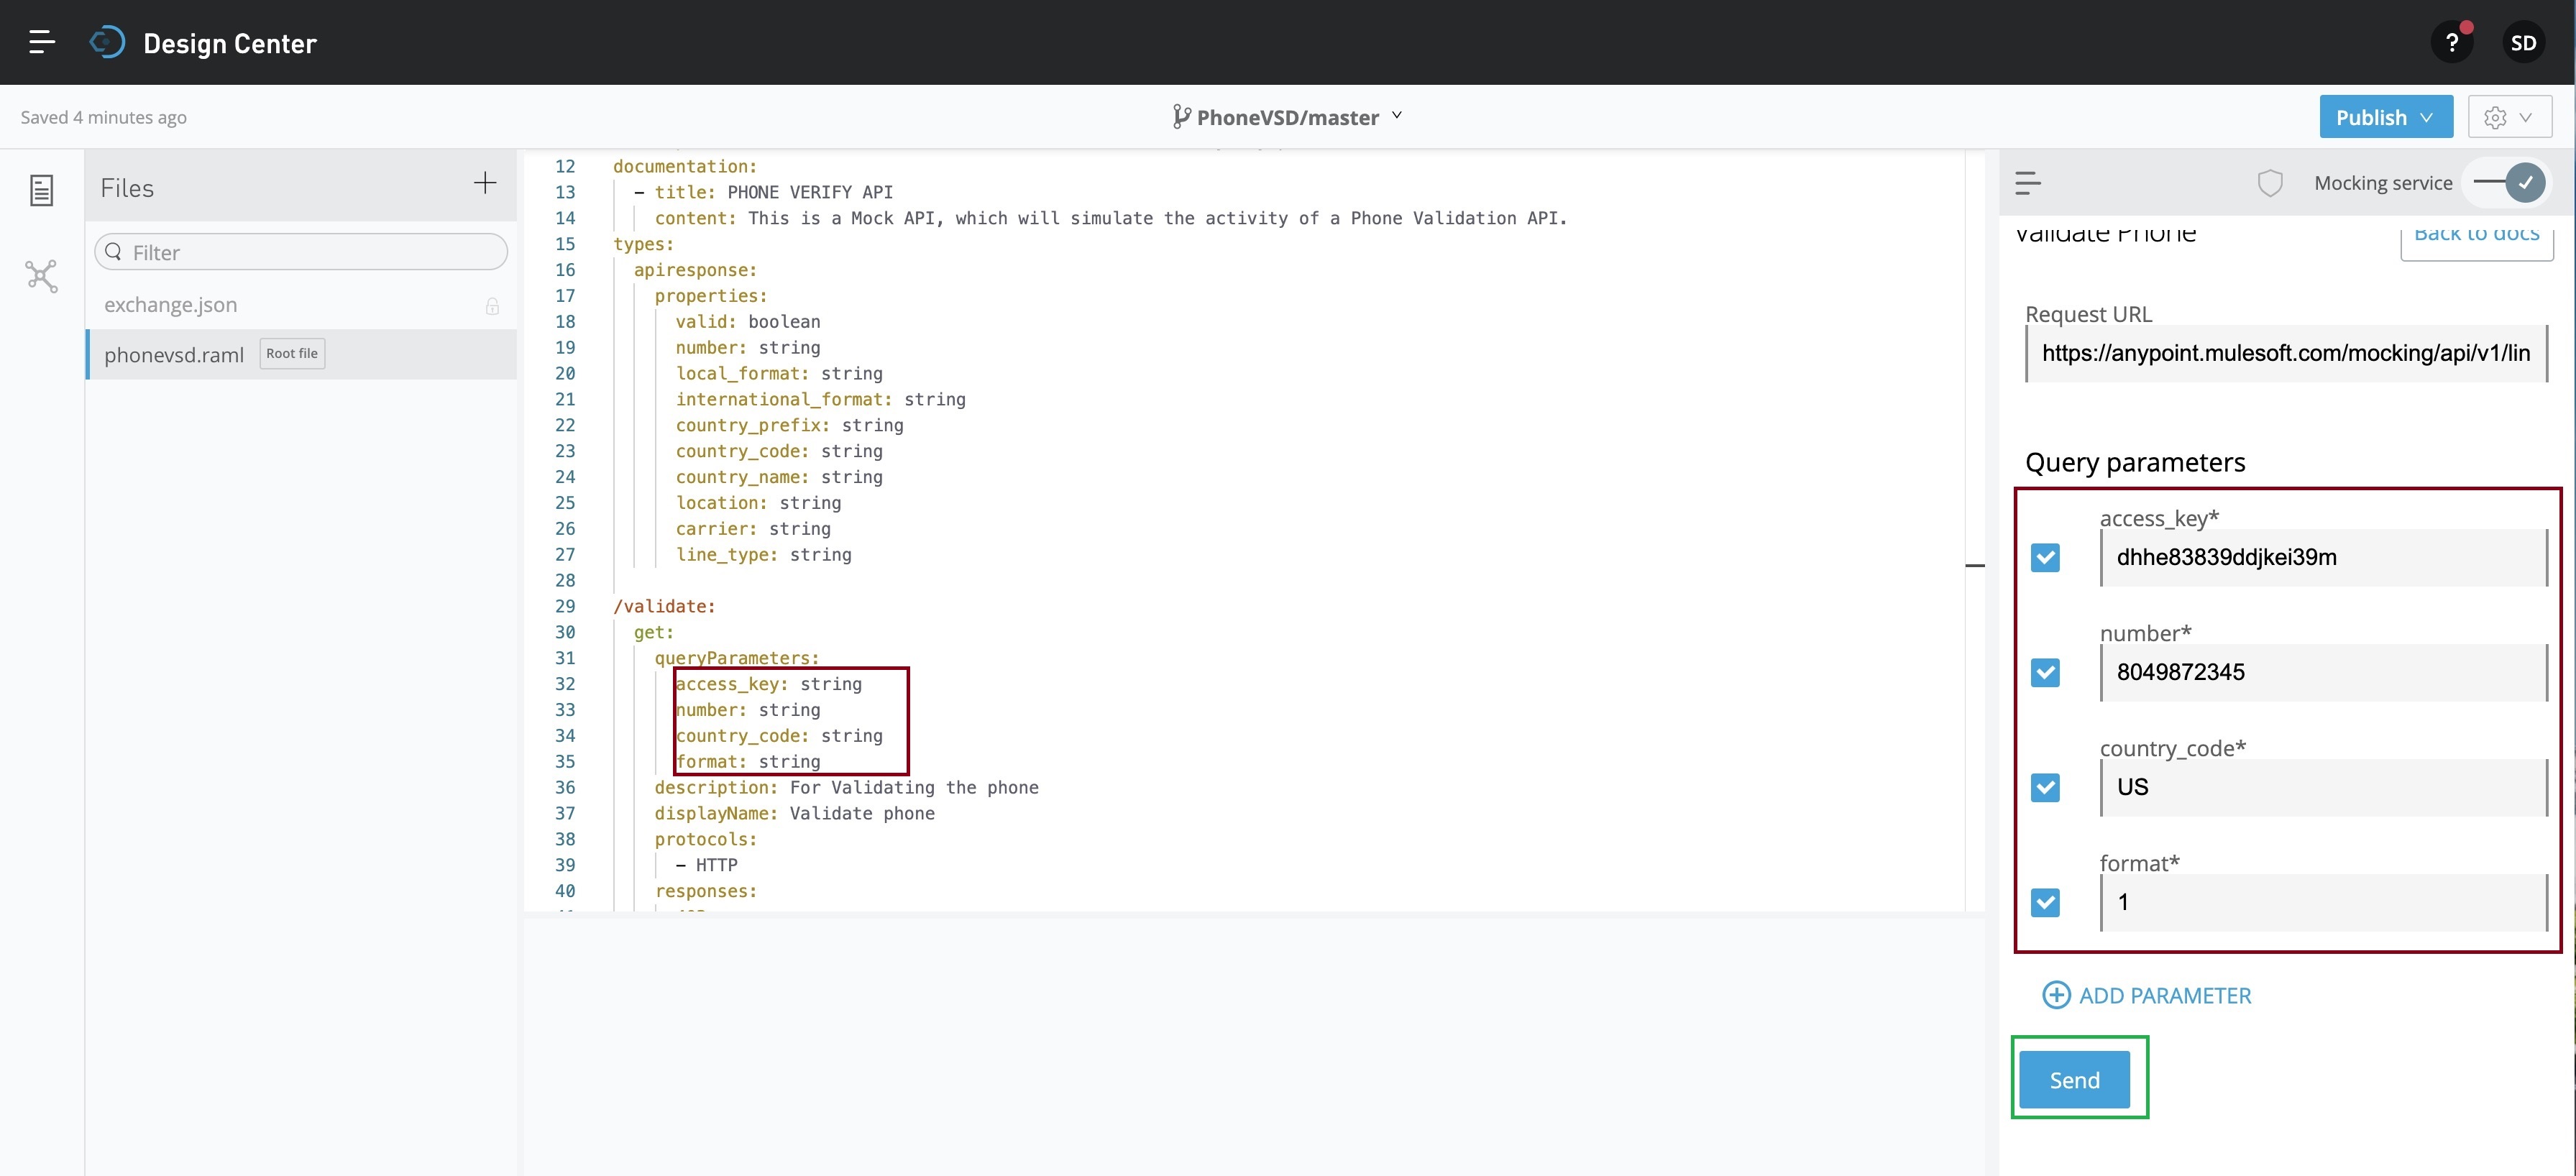

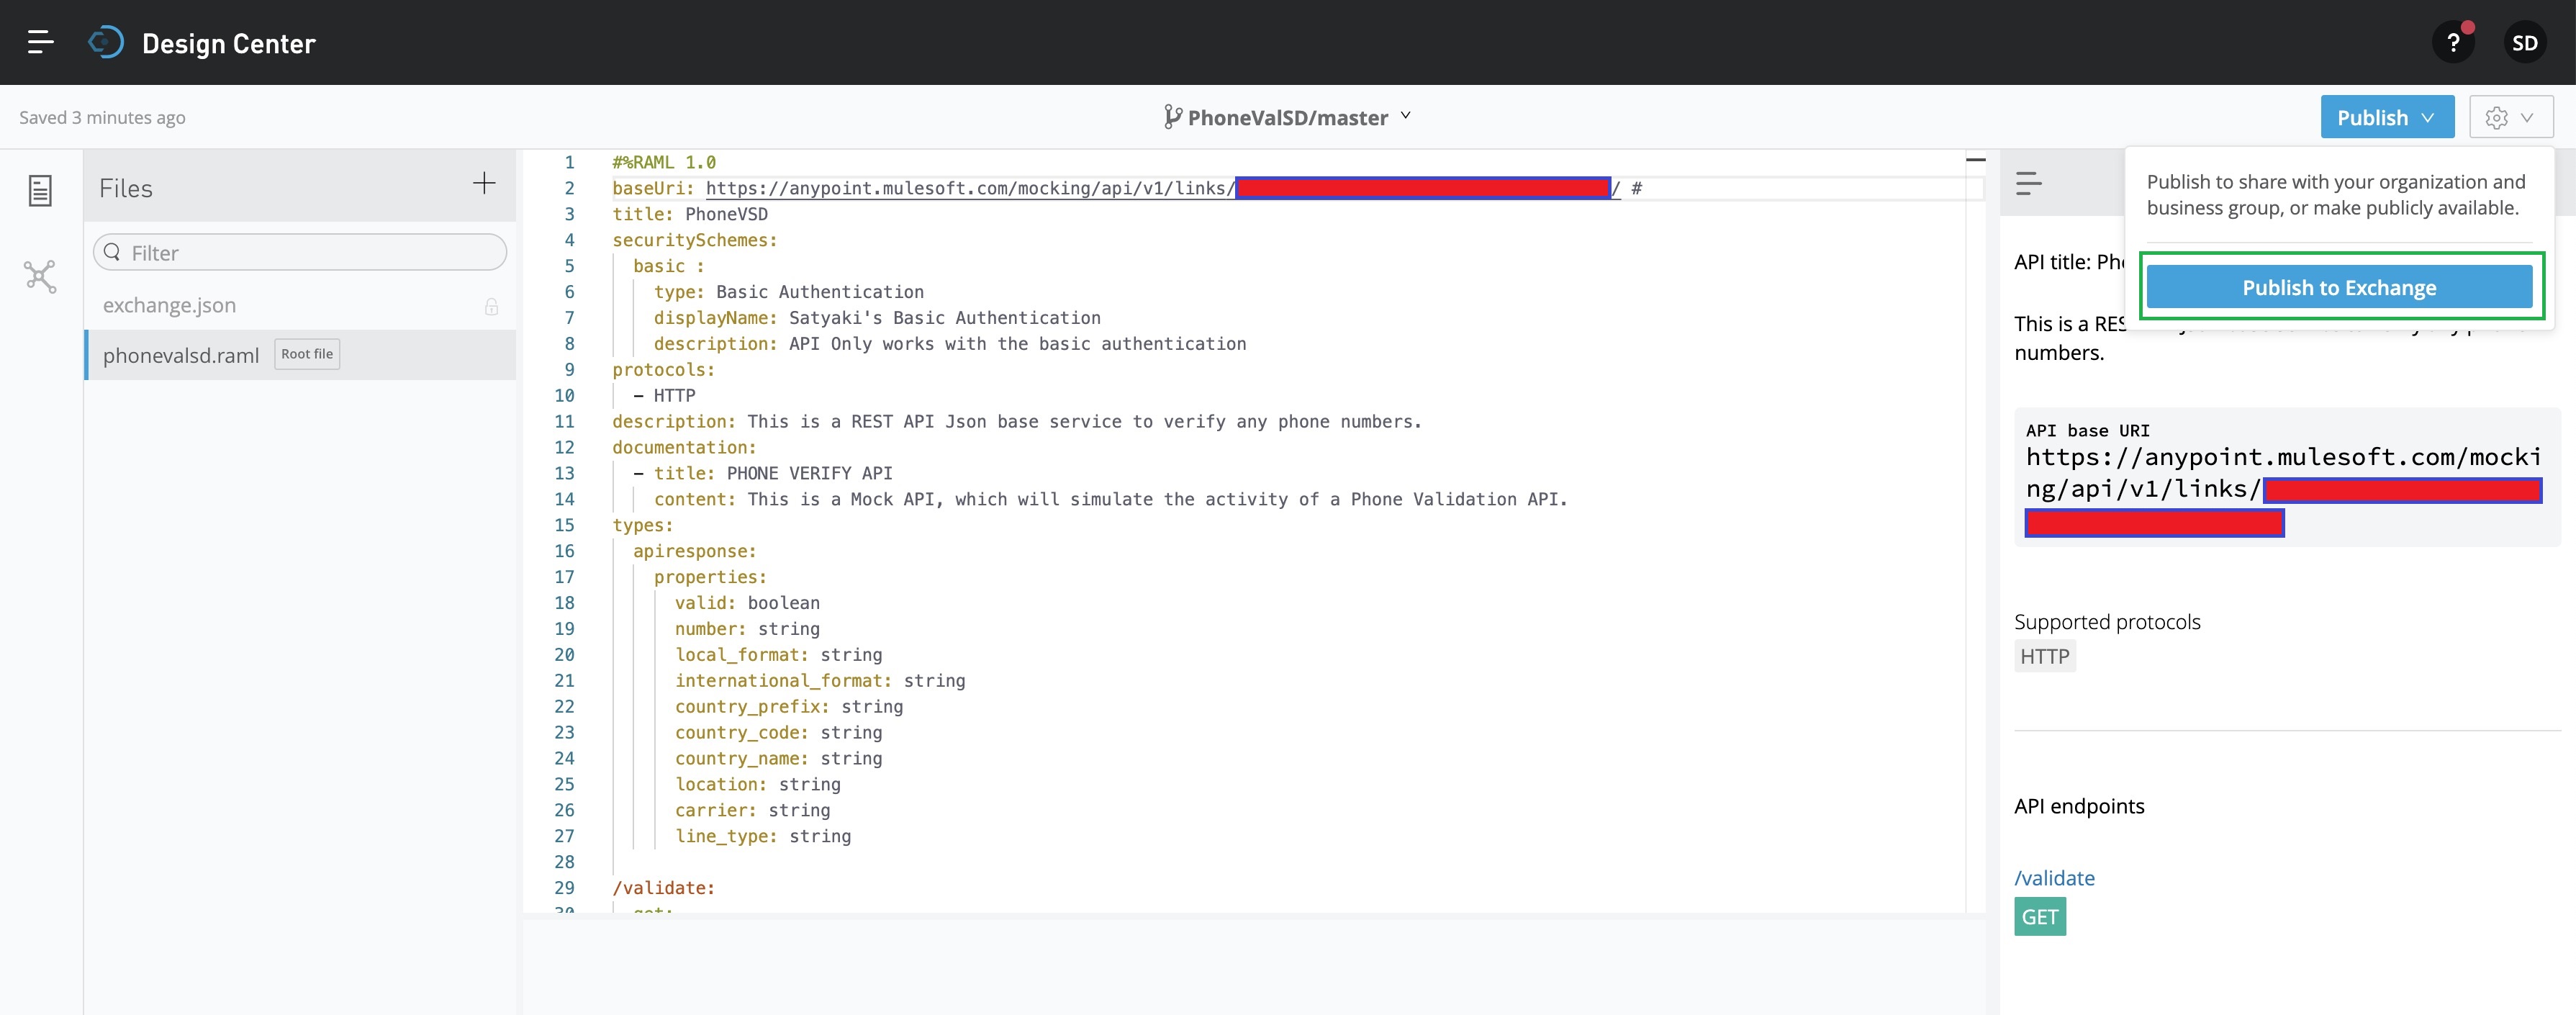
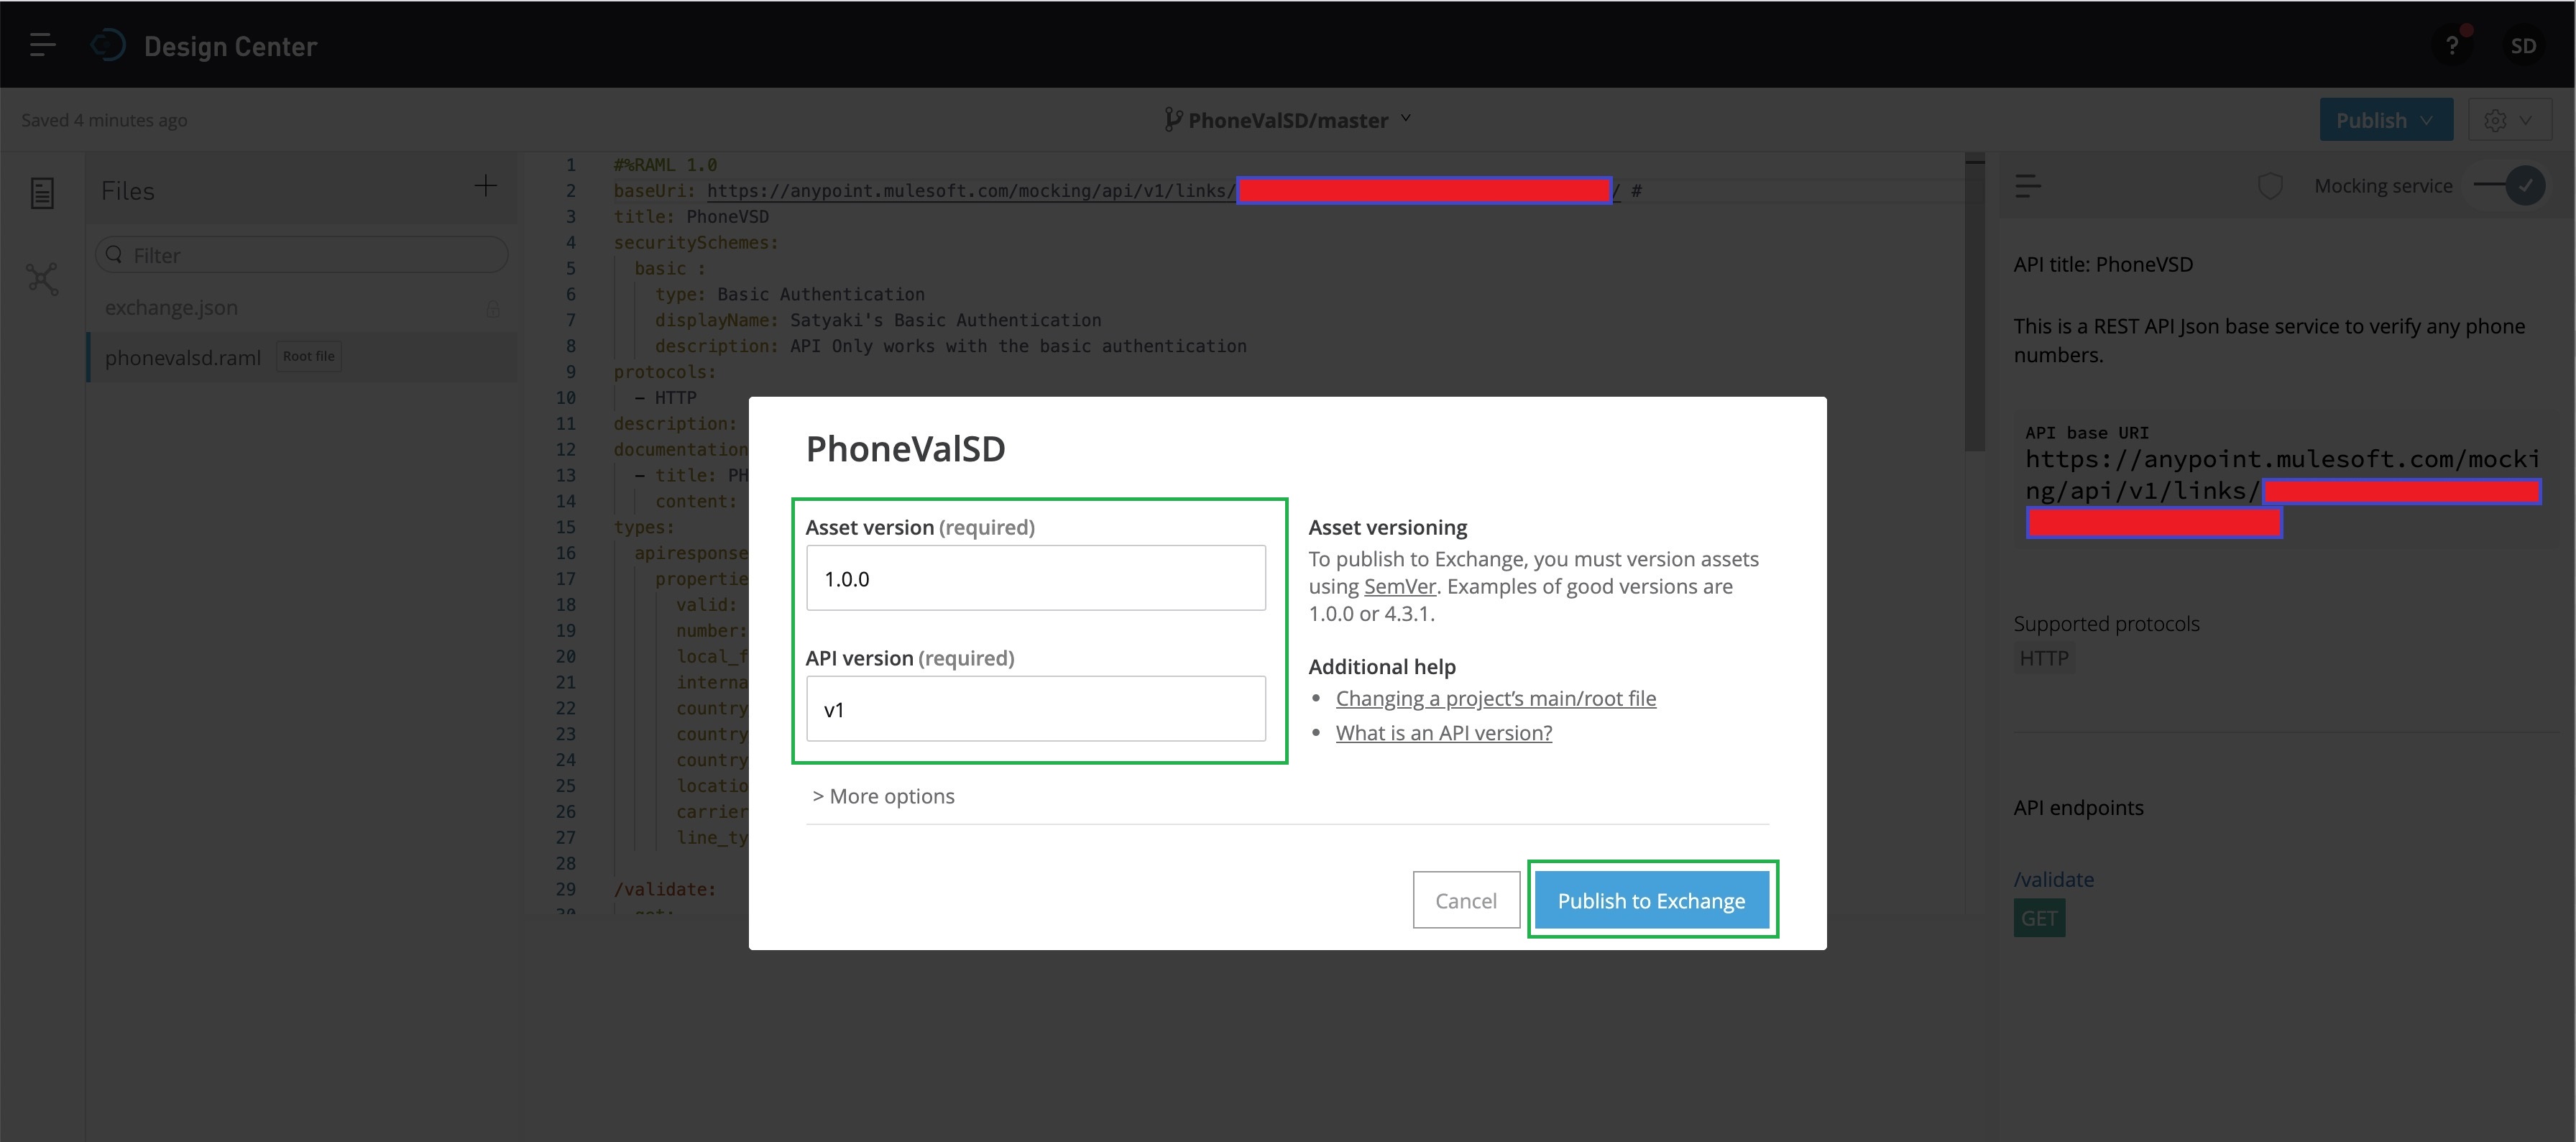
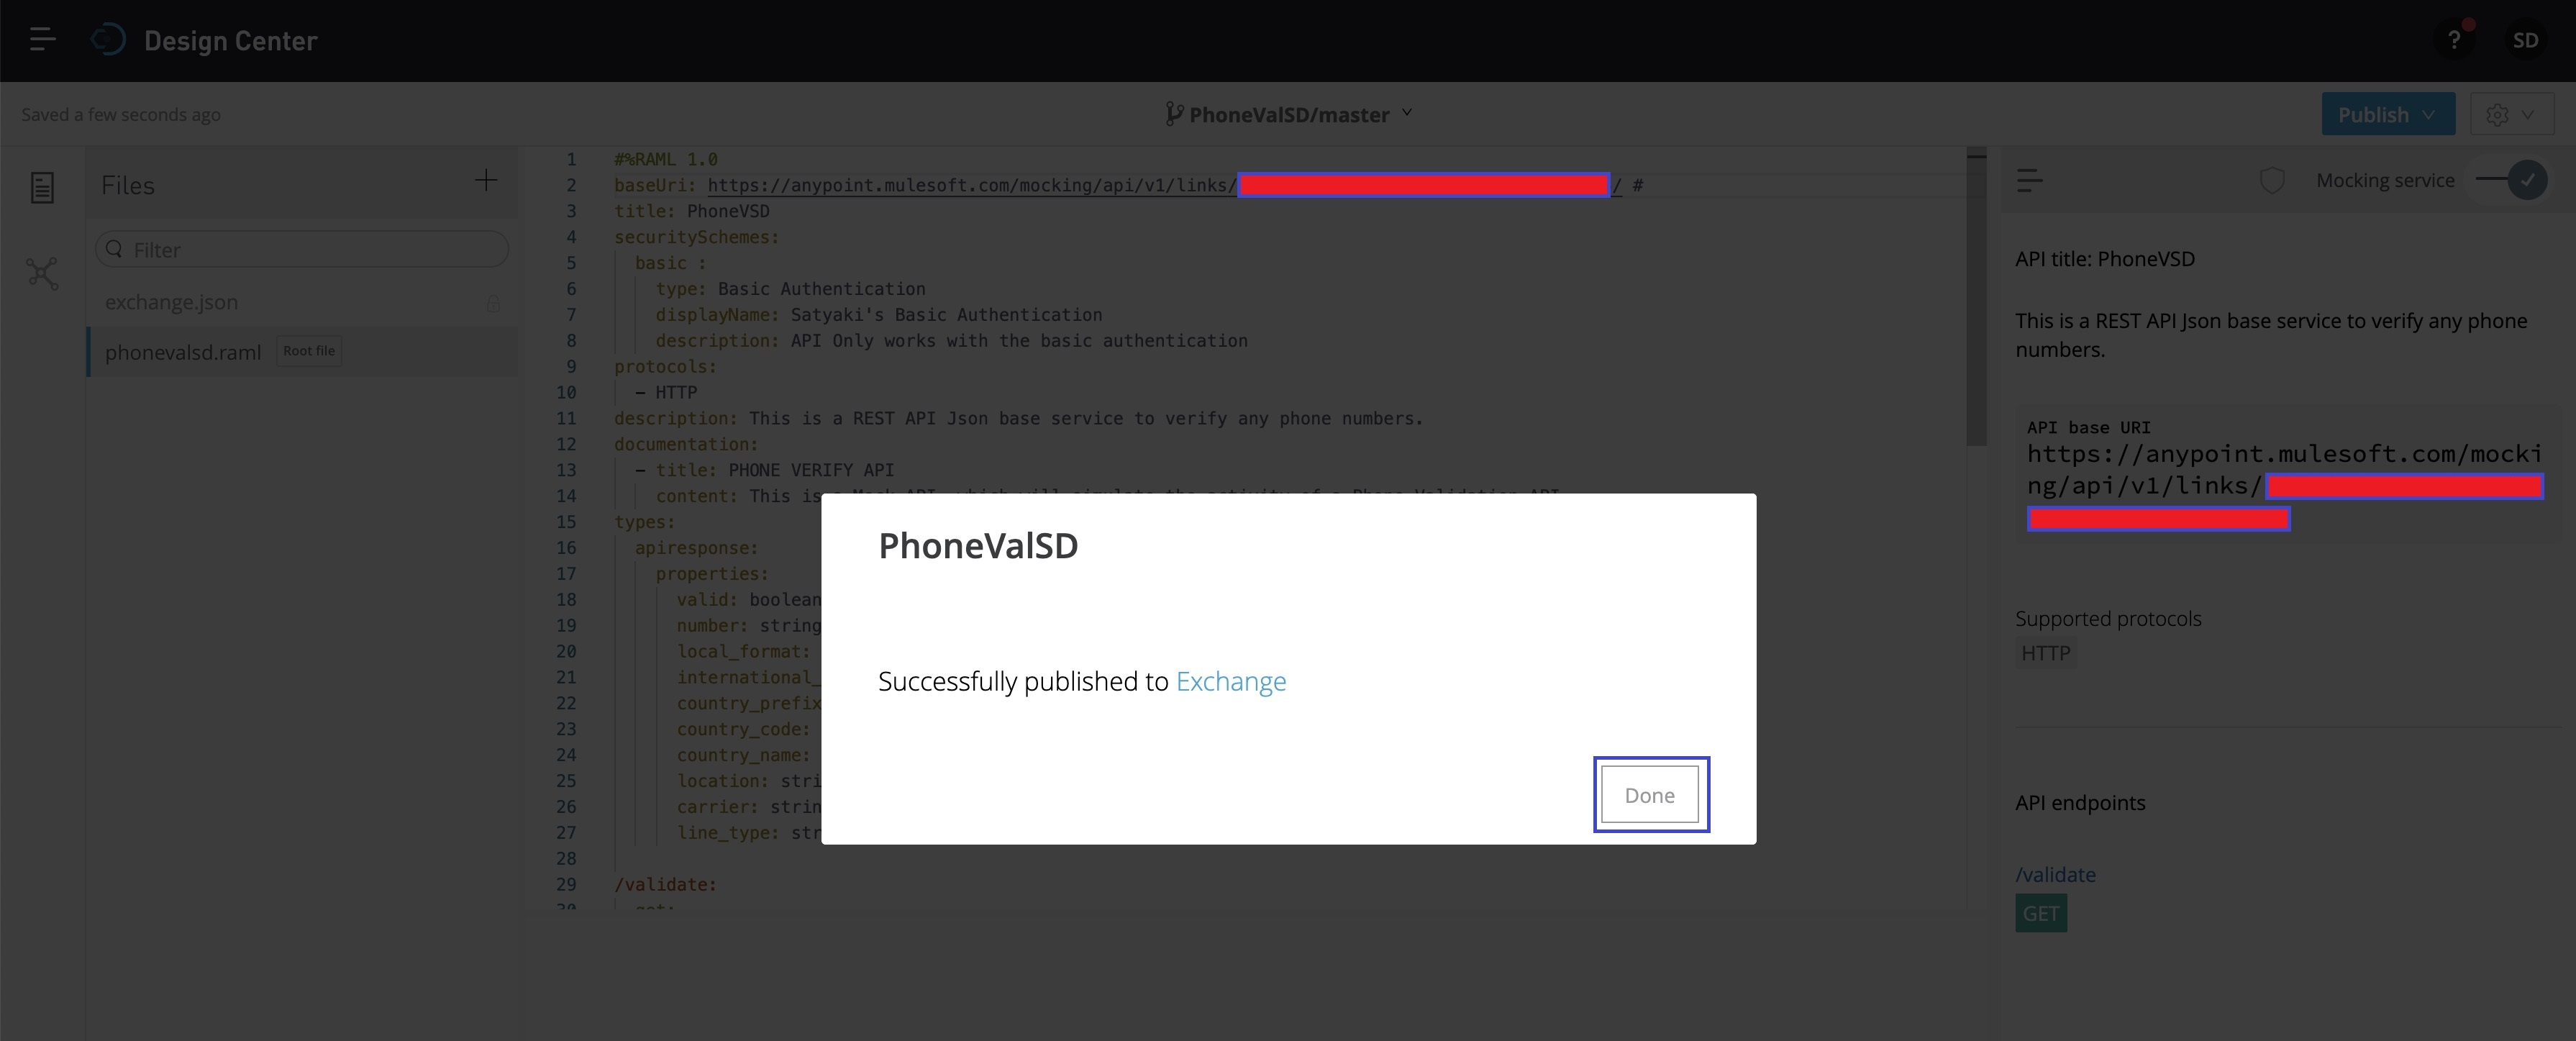


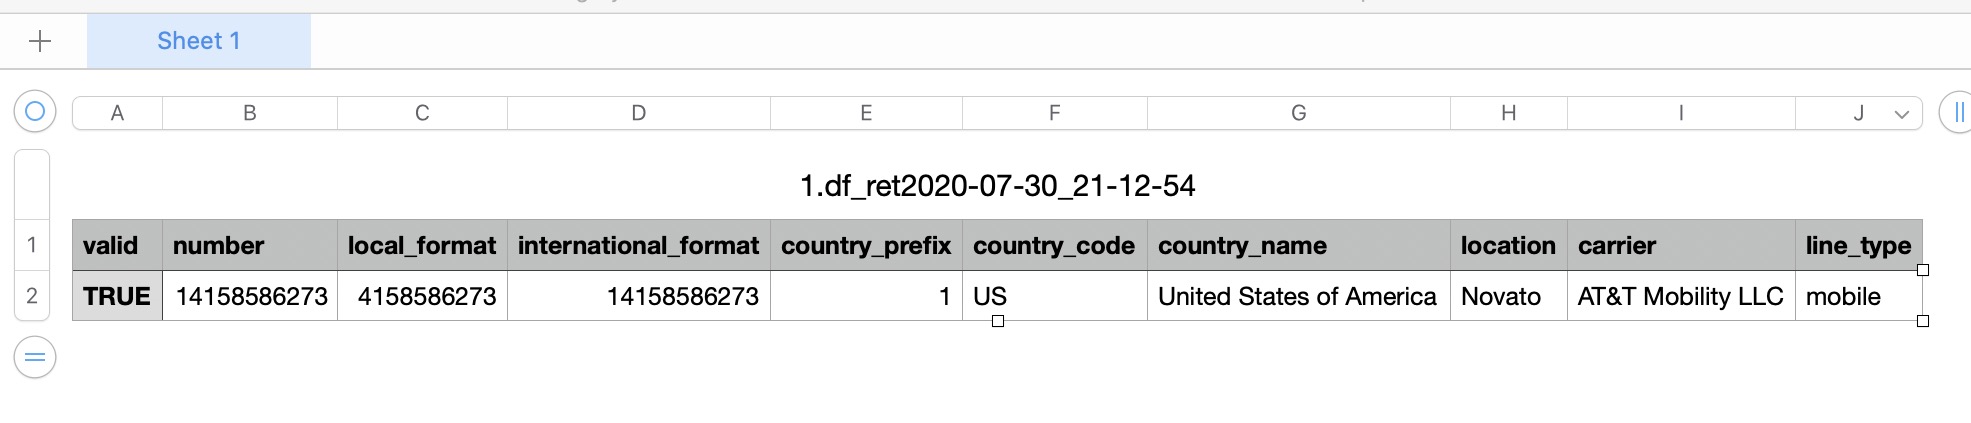


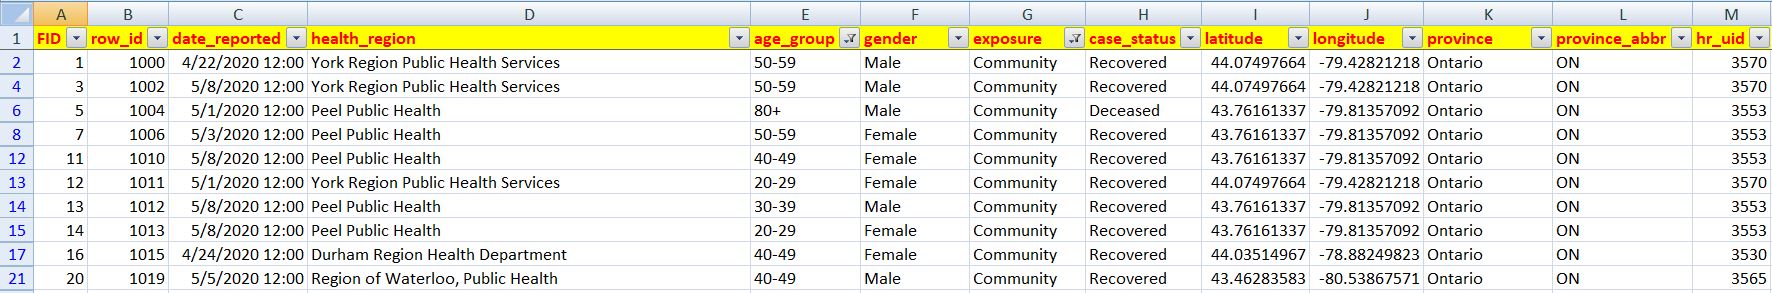




You must be logged in to post a comment.