This site mainly deals with various use cases demonstrated using Python, Data Science, Cloud basics, SQL Server, Oracle, Teradata along with SQL & their implementation. Expecting yours active participation & time. This blog can be access from your TP, Tablet & mobile also. Please provide your feedback.
This is a continuation of my previous post, which can be found here.
Let us recap the key takaways from our previous post –
Enterprise AI, utilizing the Model Context Protocol (MCP), leverages an open standard that enables AI systems to securely and consistently access enterprise data and tools. MCP replaces brittle “N×M” integrations between models and systems with a standardized client–server pattern: an MCP host (e.g., IDE or chatbot) runs an MCP client that communicates with lightweight MCP servers, which wrap external systems via JSON-RPC. Servers expose three assets—Resources (data), Tools (actions), and Prompts (templates)—behind permissions, access control, and auditability. This design enables real-time context, reduces hallucinations, supports model- and cloud-agnostic interoperability, and accelerates “build once, integrate everywhere” deployment. A typical flow (e.g., retrieving a customer’s latest order) encompasses intent parsing, authorized tool invocation, query translation/execution, and the return of a normalized JSON result to the model for natural-language delivery. Performance introduces modest overhead (RPC hops, JSON (de)serialization, network transit) and scale considerations (request volume, significant results, context-window pressure). Mitigations include in-memory/semantic caching, optimized SQL with indexing, pagination, and filtering, connection pooling, and horizontal scaling with load balancing. In practice, small latency costs are often outweighed by the benefits of higher accuracy, stronger governance, and a decoupled, scalable architecture.
How does MCP compare with other AI integration approaches?
Compared to other approaches, the Model Context Protocol (MCP) offers a uniquely standardized and secure framework for AI-tool integration, shifting from brittle, custom-coded connections to a universal plug-and-play model. It is not a replacement for underlying systems, such as APIs or databases, but instead acts as an intelligent, secure abstraction layer designed explicitly for AI agents.
MCP vs. Custom API integrations:
This approach was the traditional method for AI integration before standards like MCP emerged.
Custom API integrations (traditional): Each AI application requires a custom-built connector for every external system it needs to access, leading to an N x M integration problem (the number of connectors grows exponentially with the number of models and systems). This approach is resource-intensive, challenging to maintain, and prone to breaking when underlying APIs change.
MCP: The standardized protocol eliminates the N x M problem by creating a universal interface. Tool creators build a single MCP server for their system, and any MCP-compatible AI agent can instantly access it. This process decouples the AI model from the underlying implementation details, drastically reducing integration and maintenance costs.
For more detailed information, please refer to the following link.
MCP vs. Retrieval-Augmented Generation (RAG):
RAG is a technique that retrieves static documents to augment an LLM’s knowledge, while MCP focuses on live interactions. They are complementary, not competing.
RAG:
Focus: Retrieving and summarizing static, unstructured data, such as documents, manuals, or knowledge bases.
Best for: Providing background knowledge and general information, as in a policy lookup tool or customer service bot.
Data type: Unstructured, static knowledge.
MCP:
Focus: Accessing and acting on real-time, structured, and dynamic data from databases, APIs, and business systems.
Best for: Agentic use cases involving real-world actions, like pulling live sales reports from a CRM or creating a ticket in a project management tool.
Data type: Structured, real-time, and dynamic data.
MCP vs. LLM plugins and extensions:
Before MCP, platforms like OpenAI offered proprietary plugin systems to extend LLM capabilities.
LLM plugins:
Proprietary: Tied to a specific AI vendor (e.g., OpenAI).
Limited: Rely on the vendor’s API function-calling mechanism, which focuses on call formatting but not standardized execution.
Centralized: Managed by the AI vendor, creating a risk of vendor lock-in.
MCP:
Open standard: Based on a public, interoperable protocol (JSON-RPC 2.0), making it model-agnostic and usable across different platforms.
Infrastructure layer: Provides a standardized infrastructure for agents to discover and use any compliant tool, regardless of the underlying LLM.
Decentralized: Promotes a flexible ecosystem and reduces the risk of vendor lock-in.
How enterprise AI with MCP has opened up a specific Architecture pattern for Azure, AWS & GCP?
Microsoft Azure:
The “agent factory” pattern: Azure focuses on providing managed services for building and orchestrating AI agents, tightly integrated with its enterprise security and governance features. The MCP architecture is a core component of the Azure AI Foundry, serving as a secure, managed “agent factory.”
Azure architecture pattern with MCP:
AI orchestration layer: The Azure AI Agent Service, within Azure AI Foundry, acts as the central host and orchestrator. It provides the control plane for creating, deploying, and managing multiple specialized agents, and it natively supports the MCP standard.
AI model layer: Agents in the Foundry can be powered by various models, including those from Azure OpenAI Service, commercial models from partners, or open-source models.
MCP server and tool layer: MCP servers are deployed using serverless functions, such as Azure Functions or Azure Logic Apps, to wrap existing enterprise systems. These servers expose tools for interacting with enterprise data sources like SharePoint, Azure AI Search, and Azure Blob Storage.
Data and security layer: Data is secured using Microsoft Entra ID (formerly Azure AD) for authentication and access control, with robust security policies enforced via Azure API Management. Access to data sources, such as databases and storage, is managed securely through private networks and Managed Identity.
Amazon Web Services (AWS):
The “composable serverless agent” pattern: AWS emphasizes a modular, composable, and serverless approach, leveraging its extensive portfolio of services to build sophisticated, flexible, and scalable AI solutions. The MCP architecture here aligns with the principle of creating lightweight, event-driven services that AI agents can orchestrate.
AWS architecture pattern with MCP:
The AI orchestration layer, which includesAmazon Bedrock Agents or custom agent frameworks deployed via AWS Fargate or Lambda, acts as the MCP hosts. Bedrock Agents provide built-in orchestration, while custom agents offer greater flexibility and customization options.
AI model layer: The models are sourced from Amazon Bedrock, which provides a wide selection of foundation models.
MCP server and tool layer: MCP servers are deployed as serverless AWS Lambda functions. AWS offers pre-built MCP servers for many of its services, including the AWS Serverless MCP Server for managing serverless applications and the AWS Lambda Tool MCP Server for invoking existing Lambda functions as tools.
Data and security layer: Access is tightly controlled using AWS Identity and Access Management (IAM) roles and policies, with fine-grained permissions for each MCP server. Private data sources like databases (Amazon DynamoDB) and storage (Amazon S3) are accessed securely within a Virtual Private Cloud (VPC).
Google Cloud Platform (GCP):
The “unified workbench” pattern: GCP focuses on providing a unified, open, and data-centric platform for AI development. The MCP architecture on GCP integrates natively with the Vertex AI platform, treating MCP servers as first-class tools that can be dynamically discovered and used within a single workbench.
GCP architecture pattern with MCP:
AI orchestration layer: The Vertex AI Agent Builder serves as the central environment for building and managing conversational AI and other agents. It orchestrates workflows and manages tool invocation for agents.
AI model layer: Agents use foundation models available through the Vertex AI Model Garden or the Gemini API.
MCP server and tool layer: MCP servers are deployed as containerized microservices on Cloud Run or managed by services like App Engine. These servers contain tools that interact with GCP services, such as BigQuery, Cloud Storage, and Cloud SQL. GCP offers pre-built MCP server implementations, such as the GCP MCP Toolbox, for integration with its databases.
Data and security layer:Vertex AI Vector Search and other data sources are encapsulated within the MCP server tools to provide contextual information. Access to these services is managed by Identity and Access Management (IAM) and secured through virtual private clouds. The MCP server can leverage Vertex AI Context Caching for improved performance.
Note that all the native technology is referred to in each respective cloud. Hence, some of the better technologies can be used in place of the tool mentioned here. This is more of a concept-level comparison rather than industry-wise implementation approaches.
We’ll go ahead and conclude this post here & continue discussing on a further deep dive in the next post.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
This is a continuation of my previous post, which can be found here.
Let us recap the key takaways from our previous post –
Agentic AI refers to autonomous systems that pursue goals with minimal supervision by planning, reasoning about next steps, utilizing tools, and maintaining context across sessions. Core capabilities include goal-directed autonomy, interaction with tools and environments (e.g., APIs, databases, devices), multi-step planning and reasoning under uncertainty, persistence, and choiceful decision-making.
Architecturally, three modules coordinate intelligent behavior: Sensing (perception pipelines that acquire multimodal data, extract salient patterns, and recognize entities/events); Observation/Deliberation (objective setting, strategy formation, and option evaluation relative to resources and constraints); and Action (execution via software interfaces, communications, or physical actuation to deliver outcomes). These functions are enabled by machine learning, deep learning, computer vision, natural language processing, planning/decision-making, uncertainty reasoning, and simulation/modeling.
At enterprise scale, open standards align autonomy with governance: the Model Context Protocol (MCP) grants an agent secure, principled access to enterprise tools and data (vertical integration), while Agent-to-Agent (A2A) enables specialized agents to coordinate, delegate, and exchange information (horizontal collaboration). Together, MCP and A2A help organizations transition from isolated pilots to scalable programs, delivering end-to-end automation, faster integration, enhanced security and auditability, vendor-neutral interoperability, and adaptive problem-solving that responds to real-time context.
Great! Let’s dive into this topic now.
Enterprise AI with MCP refers to the application of the Model Context Protocol (MCP), an open standard, to enable AI systems to securely and consistently access external enterprise data and applications.
The problem MCP solves in enterprise AI:
Before MCP, enterprise AI integration was characterized by a “many-to-many” or “N x M” problem. Companies had to build custom, fragile, and costly integrations between each AI model and every proprietary data source, which was not scalable. These limitations left AI agents with limited, outdated, or siloed information, restricting their potential impact. MCP addresses this by offering a standardized architecture for AI and data systems to communicate with each other.
How does MCP work?
The MCP framework uses a client-server architecture to enable communication between AI models and external tools and data sources.
MCP Host: The AI-powered application or environment, such as an AI-enhanced IDE or a generative AI chatbot like Anthropic’s Claude or OpenAI’s ChatGPT, where the user interacts.
MCP Client: A component within the host application that manages the connection to MCP servers.
MCP Server: A lightweight service that wraps around an external system (e.g., a CRM, database, or API) and exposes its capabilities to the AI client in a standardized format, typically using JSON-RPC 2.0.
An MCP server provides AI clients with three key resources:
Resources: Structured or unstructured data that an AI can access, such as files, documents, or database records.
Tools: The functionality to perform specific actions within an external system, like running a database query or sending an email.
Prompts: Pre-defined text templates or workflows to help guide the AI’s actions.
Benefits of MCP for enterprise AI:
Standardized integration: Developers can build integrations against a single, open standard, which dramatically reduces the complexity and time required to deploy and scale AI initiatives.
Enhanced security and governance: MCP incorporates native support for security and compliance measures. It provides permission models, access control, and auditing capabilities to ensure AI systems only access data and tools within specified boundaries.
Real-time contextual awareness: By connecting AI agents to live enterprise data sources, MCP ensures they have access to the most current and relevant information, which reduces hallucinations and improves the accuracy of AI outputs.
Greater interoperability: MCP is model-agnostic & can be used with a variety of AI models (e.g., Anthropic’s Claude or OpenAI’s models) and across different cloud environments. This approach helps enterprises avoid vendor lock-in.
Accelerated development: The “build once, integrate everywhere” approach enables internal teams to focus on innovation instead of writing custom connectors for every system.
Flow of activities:
Let us understand one sample case & the flow of activities.
A customer support agent uses an AI assistant to get information about a customer’s recent orders. The AI assistant utilizes an MCP-compliant client to communicate with an MCP server, which is connected to the company’s PostgreSQL database.
The interaction flow:
1. User request: The support agent asks the AI assistant, “What was the most recent order placed by Priyanka Chopra Jonas?”
2. AI model processes intent: The AI assistant, running on an MCP host, analyzes the natural language query. It recognizes that to answer this question, it needs to perform a database query. It then identifies the appropriate tool from the MCP server’s capabilities.
3. Client initiates tool call: The AI assistant’s MCP client sends a JSON-RPC request to the MCP server connected to the PostgreSQL database. The request specifies the tool to be used, such as get_customer_orders, and includes the necessary parameters:
5. Database returns data: The PostgreSQL database executes the query and returns the requested data to the MCP server.
6. Server formats the response: The MCP server receives the raw database output and formats it into a standardized JSON response that the MCP client can understand.
7. Client returns data to the model: The MCP client receives the JSON response and passes it back to the AI assistant’s language model.
8. AI model generates final response: The language model incorporates this real-time data into its response and presents it to the user in a natural, conversational format.
“Priyanka Chopra Jonas’s most recent order was placed on August 25, 2025, with an order ID of 98765, for a total of $11025.50.”
What are the performance implications of using MCP for database access?
Using the Model Context Protocol (MCP) for database access introduces a layer of abstraction that affects performance in several ways. While it adds some latency and processing overhead, strategic implementation can mitigate these effects. For AI applications, the benefits often outweigh the costs, particularly in terms of improved accuracy, security, and scalability.
Sources of performance implications::
Added latency and processing overhead:
The MCP architecture introduces extra communication steps between the AI agent and the database, each adding a small amount of latency.
RPC overhead: The JSON-RPC call from the AI’s client to the MCP server adds a small processing and network delay. This is an out-of-process request, as opposed to a simple local function call.
JSON serialization: Request and response data must be serialized and deserialized into JSON format, which requires processing time.
Network transit: For remote MCP servers, the data must travel over the network, adding latency. However, for a local or on-premise setup, this is minimal. The physical location of the MCP server relative to the AI model and the database is a significant factor.
Scalability and resource consumption:
The performance impact scales with the complexity and volume of the AI agent’s interactions.
High request volume: A single AI agent working on a complex task might issue dozens of parallel database queries. In high-traffic scenarios, managing numerous simultaneous connections can strain system resources and require robust infrastructure.
Excessive data retrieval: A significant performance risk is an AI agent retrieving a massive dataset in a single query. This process can consume a large number of tokens, fill the AI’s context window, and cause bottlenecks at the database and client levels.
Context window usage: Tool definitions and the results of tool calls consume space in the AI’s context window. If a large number of tools are in use, this can limit the AI’s “working memory,” resulting in slower and less effective reasoning.
Optimizations for high performance::
Caching:
Caching is a crucial strategy for mitigating the performance overhead of MCP.
In-memory caching: The MCP server can cache results from frequent or expensive database queries in memory (e.g., using Redis or Memcached). This approach enables repeat requests to be served almost instantly without requiring a database hit.
Semantic caching: Advanced techniques can cache the results of previous queries and serve them for semantically similar future requests, reducing token consumption and improving speed for conversational applications.
Efficient queries and resource management:
Designing the MCP server and its database interactions for efficiency is critical.
Optimized SQL: The MCP server should generate optimized SQL queries. Database indexes should be utilized effectively to expedite lookups and minimize load.
Pagination and filtering: To prevent a single query from overwhelming the system, the MCP server should implement pagination. The AI agent can be prompted to use filtering parameters to retrieve only the necessary data.
Connection pooling: This technique reuses existing database connections instead of opening a new one for each request, thereby reducing latency and database load.
Load balancing and scaling:
For large-scale enterprise deployments, scaling is essential for maintaining performance.
Multiple servers: The workload can be distributed across various MCP servers. One server could handle read requests, and another could handle writes.
Load balancing: A reverse proxy or other load-balancing solution can distribute incoming traffic across MCP server instances. Autoscaling can dynamically add or remove servers in response to demand.
The performance trade-off in perspective:
For AI-driven tasks, a slight increase in latency for database access is often a worthwhile trade-off for significant gains.
Improved accuracy: Accessing real-time, high-quality data through MCP leads to more accurate and relevant AI responses, reducing “hallucinations”.
Scalable ecosystem: The standardization of MCP reduces development overhead and allows for a more modular, scalable ecosystem, which saves significant engineering resources compared to building custom integrations.
Decoupled architecture: The MCP server decouples the AI model from the database, allowing each to be optimized and scaled independently.
We’ll go ahead and conclude this post here & continue discussing on a further deep dive in the next post.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
Today, we won’t be discussing any solutions. Today, we’ll be discussing the Agentic AI & its implementation in the Enterprise landscape in a series of upcoming posts.
So, hang tight! We’re about to launch a new venture as part of our knowledge drive.
What is Agentic AI?
Agentic AI refers to artificial intelligence systems that can act autonomously to achieve goals, making decisions and taking actions without constant human oversight. Unlike traditional AI, which responds to prompts, agentic AI can plan, reason about next steps, utilize tools, and work toward objectives over extended periods of time.
Key characteristics of agentic AI include:
Autonomy and Goal-Directed Behavior: These systems can pursue objectives independently, breaking down complex tasks into smaller steps and executing them sequentially.
Tool Use and Environment Interaction: Agentic AI can interact with external systems, APIs, databases, and software tools to gather information and perform actions in the real world.
Planning and Reasoning: They can develop multi-step strategies, adapt their approach based on feedback, and reason through problems to find solutions.
Persistence: Unlike single-interaction AI, agentic systems can maintain context and continue working on tasks across multiple interactions or sessions.
Decision Making: They can evaluate options, weigh trade-offs, and make choices about how to proceed when faced with uncertainty.
Foundational Elements of Agentic AI Architectures:
Agentic AI systems have several interconnected components that work together to enable intelligent behaviour. Each element plays a crucial role in the overall functioning of the AI system, and they must interact seamlessly to achieve desired outcomes. Let’s explore each of these components in more detail.
Sensing:
The sensing module serves as the AI’s eyes and ears, enabling it to understand its surroundings and make informed decisions. Think of it as the system that helps the AI “see” and “hear” the world around it, much like how humans use their senses.
Gathering Information: The system collects data from multiple sources, including cameras for visual information, microphones for audio, sensors for physical touch, and digital systems for data. This step provides the AI with a comprehensive understanding of what’s happening.
Making Sense of Data: Raw information from sensors can be messy and overwhelming. This component processes the data to identify the essential patterns and details that actually matter for making informed decisions.
Recognizing What’s Important: Utilizing advanced techniques such as computer vision (for images), natural language processing (for text and speech), and machine learning (for data patterns), the system identifies and understands objects, people, events, and situations within the environment.
This sensing capability enables AI systems to transition from merely following pre-programmed instructions to genuinely understanding their environment and making informed decisions based on real-world conditions. It’s the difference between a basic automated system and an intelligent agent that can adapt to changing situations.
Observation:
The observation module serves as the AI’s decision-making center, where it sets objectives, develops strategies, and selects the most effective actions to take. This step is where the AI transforms what it perceives into purposeful action, much like humans think through problems and devise plans.
Setting Clear Objectives: The system establishes specific goals and desired outcomes, giving the AI a clear sense of direction and purpose. This approach helps ensure all actions are working toward meaningful results rather than random activity.
Strategic Planning: Using information about its own capabilities and the current situation, the AI creates step-by-step plans to reach its goals. It considers potential obstacles, available resources, and different approaches to find the most effective path forward.
Intelligent Decision-Making: When faced with multiple options, the system evaluates each choice against the current circumstances, established goals, and potential outcomes. It then selects the action most likely to move the AI closer to achieving its objectives.
This observation capability is what transforms an AI from a simple tool that follows commands into an intelligent system that can work independently toward business goals. It enables the AI to handle complex, multi-step tasks and adapt its approach when conditions change, making it valuable for a wide range of applications, from customer service to project management.
Action:
The action module serves as the AI’s hands and voice, turning decisions into real-world results. This step is where the AI actually puts its thinking and planning into action, carrying out tasks that make a tangible difference in the environment.
Control Systems: The system utilizes various tools to interact with the world, including motors for physical movement, speakers for communication, network connections for digital tasks, and software interfaces for system operation. These serve as the AI’s means of reaching out and making adjustments.
Task Implementation: Once the cognitive module determines the action to take, this component executes the actual task. Whether it’s sending an email, moving a robotic arm, updating a database, or scheduling a meeting, this module handles the execution from start to finish.
This action capability is what makes AI systems truly useful in business environments. Without it, an AI could analyze data and make significant decisions, but it couldn’t help solve problems or complete tasks. The action module bridges the gap between artificial intelligence and real-world impact, enabling AI to automate processes, respond to customers, manage systems, and deliver measurable business value.
Technology that is primarily involved in the Agentic AI is as follows –
1. Machine Learning
2. Deep Learning
3. Computer Vision
4. Natural Language Processing (NLP)
5. Planning and Decision-Making
6. Uncertainty and Reasoning
7. Simulation and Modeling
Agentic AI at Scale: MCP + A2A:
In an enterprise setting, agentic AI systems utilize the Model Context Protocol (MCP) and the Agent-to-Agent (A2A) protocol as complementary, open standards to achieve autonomous, coordinated, and secure workflows. An MCP-enabled agent gains the ability to access and manipulate enterprise tools and data. At the same time, A2A allows a network of these agents to collaborate on complex tasks by delegating and exchanging information.
This combined approach allows enterprises to move from isolated AI experiments to strategic, scalable, and secure AI programs.
How do the protocols work together in an enterprise?
Protocol
Function in Agentic AI
Focus
Example use case
Model Context Protocol (MCP)
Equips a single AI agent with the tools and data it needs to perform a specific job.
Vertical integration: connecting agents to enterprise systems like databases, CRMs, and APIs.
A sales agent uses MCP to query the company CRM for a client’s recent purchase history.
Agent-to-Agent (A2A)
Enables multiple specialized agents to communicate, delegate tasks, and collaborate on a larger, multi-step goal.
Horizontal collaboration: allowing agents from different domains to work together seamlessly.
An orchestrating agent uses A2A to delegate parts of a complex workflow to specialized HR, IT, and sales agents.
Advantages for the enterprise:
End-to-end automation: Agents can handle tasks from start to finish, including complex, multi-step workflows, autonomously.
Greater agility and speed: Enterprise-wide adoption of these protocols reduces the cost and complexity of integrating AI, accelerating deployment timelines for new applications.
Enhanced security and governance: Enterprise AI platforms built on these open standards incorporate robust security policies, centralized access controls, and comprehensive audit trails.
Vendor neutrality and interoperability: As open standards, MCP and A2A allow AI agents to work together seamlessly, regardless of the underlying vendor or platform.
Adaptive problem-solving: Agents can dynamically adjust their strategies and collaborate based on real-time data and contextual changes, leading to more resilient and efficient systems.
We will discuss this topic further in our upcoming posts.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
As a continuation of the previous post, I would like to continue my discussion about the implementation of MCP protocols among agents. But before that, I want to add the quick demo one more time to recap our objectives.
Let us recap the process flow –
Also, understand the groupings of scripts by each group as posted in the previous post –
Great! Now, we’ll continue with the main discussion.
CODE:
clsYouTubeVideoProcessor.py (This class processes the transcripts from YouTube. It may also translate them into English for non-native speakers.)
defextract_youtube_id(youtube_url):"""Extract YouTube video ID from URL""" youtube_id_match = re.search(r'(?:v=|\/)([0-9A-Za-z_-]{11}).*', youtube_url)if youtube_id_match:return youtube_id_match.group(1)returnNonedefget_youtube_transcript(youtube_url):"""Get transcript from YouTube video""" video_id =extract_youtube_id(youtube_url)ifnot video_id:return{"error":"Invalid YouTube URL or ID"}try: transcript_list = YouTubeTranscriptApi.list_transcripts(video_id)# First try to get manual transcriptstry: transcript = transcript_list.find_manually_created_transcript(["en"]) transcript_data = transcript.fetch()print(f"Debug - Manual transcript format: {type(transcript_data)}")if transcript_data andlen(transcript_data)>0:print(f"Debug - First item type: {type(transcript_data[0])}")print(f"Debug - First item sample: {transcript_data[0]}")return{"text": transcript_data,"language":"en","auto_generated":False}exceptExceptionas e:print(f"Debug - No manual transcript: {str(e)}")# If no manual English transcript, try any available transcripttry: available_transcripts =list(transcript_list)if available_transcripts: transcript = available_transcripts[0]print(f"Debug - Using transcript in language: {transcript.language_code}") transcript_data = transcript.fetch()print(f"Debug - Auto transcript format: {type(transcript_data)}")if transcript_data andlen(transcript_data)>0:print(f"Debug - First item type: {type(transcript_data[0])}")print(f"Debug - First item sample: {transcript_data[0]}")return{"text": transcript_data,"language": transcript.language_code,"auto_generated": transcript.is_generated}else:return{"error":"No transcripts available for this video"}exceptExceptionas e:return{"error":f"Error getting transcript: {str(e)}"}exceptExceptionas e:return{"error":f"Error getting transcript list: {str(e)}"}# ----------------------------------------------------------------------------------# YouTube Video Processor# ----------------------------------------------------------------------------------classclsYouTubeVideoProcessor:"""Process YouTube videos using the agent system"""def__init__(self,documentation_agent,translation_agent,research_agent):self.documentation_agent = documentation_agentself.translation_agent = translation_agentself.research_agent = research_agentdefprocess_youtube_video(self,youtube_url):"""Process a YouTube video"""print(f"Processing YouTube video: {youtube_url}")# Extract transcript transcript_result =get_youtube_transcript(youtube_url)if"error"in transcript_result:return{"error": transcript_result["error"]}# Start a new conversation conversation_id =self.documentation_agent.start_processing()# Process transcript segments transcript_data = transcript_result["text"] transcript_language = transcript_result["language"]print(f"Debug - Type of transcript_data: {type(transcript_data)}")# For each segment, detect language and translate if needed processed_segments =[]try:# Make sure transcript_data is a list of dictionaries with text and start fieldsifisinstance(transcript_data,list):for idx, segment inenumerate(transcript_data):print(f"Debug - Processing segment {idx}, type: {type(segment)}")# Extract text properly based on the typeifisinstance(segment,dict)and"text"in segment: text = segment["text"] start = segment.get("start",0)else:# Try to access attributes for non-dict typestry: text = segment.text start =getattr(segment,"start",0)exceptAttributeError:# If all else fails, convert to string text =str(segment) start = idx *5# Arbitrary timestampprint(f"Debug - Extracted text: {text[:30]}...")# Create a standardized segment std_segment ={"text": text,"start": start}# Process through translation agent translation_result =self.translation_agent.process_text(text, conversation_id)# Update segment with translation information segment_with_translation ={**std_segment,"translation_info": translation_result}# Use translated text for documentationif"final_text"in translation_result and translation_result["final_text"]!= text: std_segment["processed_text"]= translation_result["final_text"]else: std_segment["processed_text"]= text processed_segments.append(segment_with_translation)else:# If transcript_data is not a list, treat it as a single text blockprint(f"Debug - Transcript is not a list, treating as single text") text =str(transcript_data) std_segment ={"text": text,"start":0} translation_result =self.translation_agent.process_text(text, conversation_id) segment_with_translation ={**std_segment,"translation_info": translation_result}if"final_text"in translation_result and translation_result["final_text"]!= text: std_segment["processed_text"]= translation_result["final_text"]else: std_segment["processed_text"]= text processed_segments.append(segment_with_translation)exceptExceptionas e:print(f"Debug - Error processing transcript: {str(e)}")return{"error":f"Error processing transcript: {str(e)}"}# Process the transcript with the documentation agent documentation_result =self.documentation_agent.process_transcript( processed_segments, conversation_id)return{"youtube_url": youtube_url,"transcript_language": transcript_language,"processed_segments": processed_segments,"documentation": documentation_result,"conversation_id": conversation_id}
Let us understand this step-by-step:
Part 1: Getting the YouTube Transcript
defextract_youtube_id(youtube_url): ...
This extracts the unique video ID from any YouTube link.
defget_youtube_transcript(youtube_url): ...
This gets the actual spoken content of the video.
It tries to get a manual transcript first (created by humans).
If not available, it falls back to an auto-generated version (created by YouTube’s AI).
If nothing is found, it gives back an error message like: “Transcript not available.”
Part 2: Processing the Video with Agents
classclsYouTubeVideoProcessor: ...
This is like the control center that tells each intelligent agent what to do with the transcript. Here are the detailed steps:
1. Start the Process
defprocess_youtube_video(self,youtube_url): ...
The system starts with a YouTube video link.
It prints a message like: “Processing YouTube video: [link]”
2. Extract the Transcript
The system runs the get_youtube_transcript() function.
If it fails, it returns an error (e.g., invalid link or no subtitles available).
3. Start a “Conversation”
The documentation agent begins a new session, tracked by a unique conversation ID.
Think of this like opening a new folder in a shared team workspace to store everything related to this video.
4. Go Through Each Segment of the Transcript
The spoken text is often broken into small parts (segments), like subtitles.
For each part:
It checks the text.
It finds out the time that part was spoken.
It sends it to the translation agent to clean up or translate the text.
5. Translate (if needed)
If the translation agent finds a better or translated version, it replaces the original.
Otherwise, it keeps the original.
6. Prepare for Documentation
After translation, the segment is passed to the documentation agent.
This agent might:
Summarize the content,
Highlight important terms,
Structure it into a readable format.
7. Return the Final Result
The system gives back a structured package with:
The video link
The original language
The transcript in parts (processed and translated)
A documentation summary
The conversation ID (for tracking or further updates)
clsDocumentationAgent.py (This is the main class that will be part of the document agents.)
classclsDocumentationAgent:"""Documentation Agent built with LangChain"""def__init__(self,agent_id:str,broker: clsMCPBroker):self.agent_id = agent_idself.broker = brokerself.broker.register_agent(agent_id)# Initialize LangChain componentsself.llm =ChatOpenAI(model="gpt-4-0125-preview",temperature=0.1,api_key=OPENAI_API_KEY)# Create toolsself.tools =[clsSendMessageTool(sender_id=self.agent_id,broker=self.broker)]# Set up LLM with toolsself.llm_with_tools =self.llm.bind(tools=[tool.tool_config for tool inself.tools])# Setup memoryself.memory =ConversationBufferMemory(memory_key="chat_history",return_messages=True)# Create promptself.prompt = ChatPromptTemplate.from_messages([("system","""You are a Documentation Agent for YouTube video transcripts. Your responsibilities include: 1. Process YouTube video transcripts 2. Identify key points, topics, and main ideas 3. Organize content into a coherent and structured format 4. Create concise summaries 5. Request research information when necessary When you need additional context or research, send a request to the Research Agent. Always maintain a professional tone and ensure your documentation is clear and organized."""),MessagesPlaceholder(variable_name="chat_history"),("human","{input}"),MessagesPlaceholder(variable_name="agent_scratchpad"),])# Create agentself.agent =({"input":lambdax: x["input"],"chat_history":lambdax:self.memory.load_memory_variables({})["chat_history"],"agent_scratchpad":lambdax:format_to_openai_tool_messages(x["intermediate_steps"]),}|self.prompt|self.llm_with_tools|OpenAIToolsAgentOutputParser())# Create agent executorself.agent_executor =AgentExecutor(agent=self.agent,tools=self.tools,verbose=True,memory=self.memory)# Video dataself.current_conversation_id =Noneself.video_notes ={}self.key_points =[]self.transcript_segments =[]defstart_processing(self)->str:"""Start processing a new video"""self.current_conversation_id =str(uuid.uuid4())self.video_notes ={}self.key_points =[]self.transcript_segments =[]returnself.current_conversation_iddefprocess_transcript(self,transcript_segments,conversation_id=None):"""Process a YouTube transcript"""ifnot conversation_id: conversation_id =self.start_processing()self.current_conversation_id = conversation_id# Store transcript segmentsself.transcript_segments = transcript_segments# Process segments processed_segments =[]for segment in transcript_segments: processed_result =self.process_segment(segment) processed_segments.append(processed_result)# Generate summary summary =self.generate_summary()return{"processed_segments": processed_segments,"summary": summary,"conversation_id": conversation_id}defprocess_segment(self,segment):"""Process individual transcript segment""" text = segment.get("text","") start = segment.get("start",0)# Use LangChain agent to process the segment result =self.agent_executor.invoke({"input":f"Process this video transcript segment at timestamp {start}s: {text}. If research is needed, send a request to the research_agent."})# Update video notes timestamp = startself.video_notes[timestamp]={"text": text,"analysis": result["output"]}return{"timestamp": timestamp,"text": text,"analysis": result["output"]}defhandle_mcp_message(self,message: clsMCPMessage)-> Optional[clsMCPMessage]:"""Handle an incoming MCP message"""if message.message_type =="research_response":# Process research information received from Research Agent research_info = message.content.get("text","") result =self.agent_executor.invoke({"input":f"Incorporate this research information into video analysis: {research_info}"})# Send acknowledgment back to Research Agent response =clsMCPMessage(sender=self.agent_id,receiver=message.sender,message_type="acknowledgment",content={"text":"Research information incorporated into video analysis."},reply_to=message.id,conversation_id=message.conversation_id)self.broker.publish(response)return responseelif message.message_type =="translation_response":# Process translation response from Translation Agent translation_result = message.content# Process the translated textif"final_text"in translation_result: text = translation_result["final_text"] original_text = translation_result.get("original_text","") language_info = translation_result.get("language",{}) result =self.agent_executor.invoke({"input":f"Process this translated text: {text}\nOriginal language: {language_info.get('language','unknown')}\nOriginal text: {original_text}"})# Update notes with translation informationfor timestamp, note inself.video_notes.items():if note["text"]== original_text: note["translated_text"]= text note["language"]= language_infobreakreturnNonereturnNonedefrun(self):"""Run the agent to listen for MCP messages"""print(f"Documentation Agent {self.agent_id} is running...")whileTrue: message =self.broker.get_message(self.agent_id,timeout=1)if message:self.handle_mcp_message(message) time.sleep(0.1)defgenerate_summary(self)->str:"""Generate a summary of the video"""ifnotself.video_notes:return"No video data available to summarize." all_notes ="\n".join([f"{ts}: {note['text']}"for ts, note inself.video_notes.items()]) result =self.agent_executor.invoke({"input":f"Generate a concise summary of this YouTube video, including key points and topics:\n{all_notes}"})return result["output"]
Let us understand the key methods in a step-by-step manner:
The Documentation Agent is like a smart assistant that watches a YouTube video, takes notes, pulls out important ideas, and creates a summary — almost like a professional note-taker trained to help educators, researchers, and content creators. It works with a team of other assistants, like a Translator Agent and a Research Agent, and they all talk to each other through a messaging system.
1. Starting to Work on a New Video
defstart_processing(self)->str
When a new video is being processed:
A new project ID is created.
Old notes and transcripts are cleared to start fresh.
2. Processing the Whole Transcript
defprocess_transcript(...)
This is where the assistant:
Takes in the full transcript (what was said in the video).
Breaks it into small parts (like subtitles).
Sends each part to the smart brain for analysis.
Collects the results.
Finally, a summary of all the main ideas is created.
3. Processing One Transcript Segment at a Time
defprocess_segment(self,segment)
For each chunk of the video:
The assistant reads the text and timestamp.
It asks GPT-4 to analyze it and suggest important insights.
It saves that insight along with the original text and timestamp.
4. Handling Incoming Messages from Other Agents
defhandle_mcp_message(self,message)
The assistant can also receive messages from teammates (other agents):
If the message is from the Research Agent:
It reads new information and adds it to its notes.
It replies with a thank-you message to say it got the research.
If the message is from the Translation Agent:
It takes the translated version of a transcript.
Updates its notes to reflect the translated text and its language.
This is like a team of assistants emailing back and forth to make sure the notes are complete and accurate.
5. Summarizing the Whole Video
defgenerate_summary(self)
After going through all the transcript parts, the agent asks GPT-4 to create a short, clean summary — identifying:
Main ideas
Key talking points
Structure of the content
The final result is clear, professional, and usable in learning materials or documentation.
clsResearchAgent.py (This is the main class that implements the research agent.)
classclsResearchAgent:"""Research Agent built with AutoGen"""def__init__(self,agent_id:str,broker: clsMCPBroker):self.agent_id = agent_idself.broker = brokerself.broker.register_agent(agent_id)# Configure AutoGen directly with API keyifnot OPENAI_API_KEY:print("Warning: OPENAI_API_KEY not set for ResearchAgent")# Create config list directly instead of loading from file config_list =[{"model":"gpt-4-0125-preview","api_key": OPENAI_API_KEY}]# Create AutoGen assistant for researchself.assistant =AssistantAgent(name="research_assistant",system_message="""You are a Research Agent for YouTube videos. Your responsibilities include: 1. Research topics mentioned in the video 2. Find relevant information, facts, references, or context 3. Provide concise, accurate information to support the documentation 4. Focus on delivering high-quality, relevant information Respond directly to research requests with clear, factual information.""",llm_config={"config_list": config_list,"temperature":0.1})# Create user proxy to handle message passingself.user_proxy =UserProxyAgent(name="research_manager",human_input_mode="NEVER",code_execution_config={"work_dir":"coding","use_docker":False},default_auto_reply="Working on the research request...")# Current conversation trackingself.current_requests ={}defhandle_mcp_message(self,message: clsMCPMessage)-> Optional[clsMCPMessage]:"""Handle an incoming MCP message"""if message.message_type =="request":# Process research request from Documentation Agent request_text = message.content.get("text","")# Use AutoGen to process the research requestdefresearch_task():self.user_proxy.initiate_chat(self.assistant,message=f"Research request for YouTube video content: {request_text}. Provide concise, factual information.")# Return last assistant messagereturnself.assistant.chat_messages[self.user_proxy.name][-1]["content"]# Execute research task research_result =research_task()# Send research results back to Documentation Agent response =clsMCPMessage(sender=self.agent_id,receiver=message.sender,message_type="research_response",content={"text": research_result},reply_to=message.id,conversation_id=message.conversation_id)self.broker.publish(response)return responsereturnNonedefrun(self):"""Run the agent to listen for MCP messages"""print(f"Research Agent {self.agent_id} is running...")whileTrue: message =self.broker.get_message(self.agent_id,timeout=1)if message:self.handle_mcp_message(message) time.sleep(0.1)
Let us understand the key methods in detail.
1. Receiving and Responding to Research Requests
defhandle_mcp_message(self,message)
When the Research Agent gets a message (like a question or request for info), it:
Reads the message to see what needs to be researched.
Asks GPT-4 to find helpful, accurate info about that topic.
Sends the answer back to whoever asked the question (usually the Documentation Agent).
clsTranslationAgent.py (This is the main class that represents the translation agent)
classclsTranslationAgent:"""Agent for language detection and translation"""def__init__(self,agent_id:str,broker: clsMCPBroker):self.agent_id = agent_idself.broker = brokerself.broker.register_agent(agent_id)# Initialize language detectorself.language_detector =clsLanguageDetector()# Initialize translation serviceself.translation_service =clsTranslationService()defprocess_text(self,text,conversation_id=None):"""Process text: detect language and translate if needed, handling mixed language content"""ifnot conversation_id: conversation_id =str(uuid.uuid4())# Detect language with support for mixed language content language_info =self.language_detector.detect(text)# Decide if translation is needed needs_translation =True# Pure English content doesn't need translationif language_info["language_code"]=="en-IN"or language_info["language_code"]=="unknown": needs_translation =False# For mixed language, check if it's primarily Englishif language_info.get("is_mixed",False)and language_info.get("languages",[]): english_langs =[ lang for lang in language_info.get("languages",[])if lang["language_code"]=="en-IN"or lang["language_code"].startswith("en-")]# If the highest confidence language is English and > 60% confident, don't translateif english_langs and english_langs[0].get("confidence",0)>0.6: needs_translation =Falseif needs_translation:# Translate using the appropriate service based on language detection translation_result =self.translation_service.translate(text, language_info)return{"original_text": text,"language": language_info,"translation": translation_result,"final_text": translation_result.get("translated_text", text),"conversation_id": conversation_id}else:# Already English or unknown language, return as isreturn{"original_text": text,"language": language_info,"translation":{"provider":"none"},"final_text": text,"conversation_id": conversation_id}defhandle_mcp_message(self,message: clsMCPMessage)-> Optional[clsMCPMessage]:"""Handle an incoming MCP message"""if message.message_type =="translation_request":# Process translation request from Documentation Agent text = message.content.get("text","")# Process the text result =self.process_text(text, message.conversation_id)# Send translation results back to requester response =clsMCPMessage(sender=self.agent_id,receiver=message.sender,message_type="translation_response",content=result,reply_to=message.id,conversation_id=message.conversation_id)self.broker.publish(response)return responsereturnNonedefrun(self):"""Run the agent to listen for MCP messages"""print(f"Translation Agent {self.agent_id} is running...")whileTrue: message =self.broker.get_message(self.agent_id,timeout=1)if message:self.handle_mcp_message(message) time.sleep(0.1)
Let us understand the key methods in step-by-step manner:
1. Understanding and Translating Text:
defprocess_text(...)
This is the core job of the agent. Here’s what it does with any piece of text:
Step 1: Detect the Language
It tries to figure out the language of the input text.
It can handle cases where more than one language is mixed together, which is common in casual speech or subtitles.
Step 2: Decide Whether to Translate
If the text is clearly in English, or it’s unclear what the language is, it decides not to translate.
If the text is mostly in another language or has less than 60% confidence in being English, it will translate it into English.
Step 3: Translate (if needed)
If translation is required, it uses the translation service to do the job.
Then it packages all the information: the original text, detected language, the translated version, and a unique conversation ID.
Step 4: Return the Results
If no translation is needed, it returns the original text and a note saying “no translation was applied.”
2. Receiving Messages and Responding
defhandle_mcp_message(...)
The agent listens for messages from other agents. When someone asks it to translate something:
It takes the text from the message.
Runs it through the process_text function (as explained above).
Sends the translated (or original) result to the person who asked.
clsTranslationService.py (This is the actual work process of translation by the agent)
classclsTranslationService:"""Translation service using multiple providers with support for mixed languages"""def__init__(self):# Initialize Sarvam AI clientself.sarvam_api_key = SARVAM_API_KEYself.sarvam_url ="https://api.sarvam.ai/translate"# Initialize Google Cloud Translation client using simple HTTP requestsself.google_api_key = GOOGLE_API_KEYself.google_translate_url ="https://translation.googleapis.com/language/translate/v2"deftranslate_with_sarvam(self,text,source_lang,target_lang="en-IN"):"""Translate text using Sarvam AI (for Indian languages)"""ifnotself.sarvam_api_key:return{"error":"Sarvam API key not set"} headers ={"Content-Type":"application/json","api-subscription-key":self.sarvam_api_key} payload ={"input": text,"source_language_code": source_lang,"target_language_code": target_lang,"speaker_gender":"Female","mode":"formal","model":"mayura:v1"}try: response = requests.post(self.sarvam_url,headers=headers,json=payload)if response.status_code ==200:return{"translated_text": response.json().get("translated_text",""),"provider":"sarvam"}else:return{"error":f"Sarvam API error: {response.text}","provider":"sarvam"}exceptExceptionas e:return{"error":f"Error calling Sarvam API: {str(e)}","provider":"sarvam"}deftranslate_with_google(self,text,target_lang="en"):"""Translate text using Google Cloud Translation API with direct HTTP request"""ifnotself.google_api_key:return{"error":"Google API key not set"}try:# Using the translation API v2 with API key params ={"key":self.google_api_key,"q": text,"target": target_lang} response = requests.post(self.google_translate_url,params=params)if response.status_code ==200: data = response.json() translation = data.get("data",{}).get("translations",[{}])[0]return{"translated_text": translation.get("translatedText",""),"detected_source_language": translation.get("detectedSourceLanguage",""),"provider":"google"}else:return{"error":f"Google API error: {response.text}","provider":"google"}exceptExceptionas e:return{"error":f"Error calling Google Translation API: {str(e)}","provider":"google"}deftranslate(self,text,language_info):"""Translate text to English based on language detection info"""# If already English or unknown language, return as isif language_info["language_code"]=="en-IN"or language_info["language_code"]=="unknown":return{"translated_text": text,"provider":"none"}# Handle mixed language contentif language_info.get("is_mixed",False)and language_info.get("languages",[]):# Strategy for mixed language: # 1. If one of the languages is English, don't translate the entire text, as it might distort English portions# 2. If no English but contains Indian languages, use Sarvam as it handles code-mixing better# 3. Otherwise, use Google Translate for the primary detected language has_english =False has_indian =Falsefor lang in language_info.get("languages",[]):if lang["language_code"]=="en-IN"or lang["language_code"].startswith("en-"): has_english =Trueif lang.get("is_indian",False): has_indian =Trueif has_english:# Contains English - use Google for full text as it handles code-mixing wellreturnself.translate_with_google(text)elif has_indian:# Contains Indian languages - use Sarvam# Use the highest confidence Indian language as source indian_langs =[lang for lang in language_info.get("languages",[])if lang.get("is_indian",False)]if indian_langs:# Sort by confidence indian_langs.sort(key=lambdax: x.get("confidence",0),reverse=True) source_lang = indian_langs[0]["language_code"]returnself.translate_with_sarvam(text, source_lang)else:# Fallback to primary languageif language_info["is_indian"]:returnself.translate_with_sarvam(text, language_info["language_code"])else:returnself.translate_with_google(text)else:# No English, no Indian languages - use Google for primary languagereturnself.translate_with_google(text)else:# Not mixed language - use standard approachif language_info["is_indian"]:# Use Sarvam AI for Indian languagesreturnself.translate_with_sarvam(text, language_info["language_code"])else:# Use Google for other languagesreturnself.translate_with_google(text)
This Translation Service is like a smart translator that knows how to:
Detect what language the text is written in,
Choose the best translation provider depending on the language (especially for Indian languages),
And then translate the text into English.
It supports mixed-language content (such as Hindi-English in one sentence) and uses either Google Translate or Sarvam AI, a translation service designed for Indian languages.
Now, let us understand the key methods in a step-by-step manner:
1. Translating Using Google Translate
deftranslate_with_google(...)
This function uses Google Translate:
It sends the text, asks for English as the target language, and gets a translation back.
It also detects the source language automatically.
If successful, it returns the translated text and the detected original language.
If there’s an error, it returns a message saying what went wrong.
Best For: Non-Indian languages (like Spanish, French, Chinese) and content that is not mixed with English.
2. Main Translation Logic
deftranslate(self,text,language_info)
This is the decision-maker. Here’s how it works:
Case 1: No Translation Needed
If the text is already in English or the language is unknown, it simply returns the original text.
Case 2: Mixed Language (e.g., Hindi + English)
If the text contains more than one language:
✅ If one part is English → use Google Translate (it’s good with mixed languages).
✅ If it includes Indian languages only → use Sarvam AI (better at handling Indian content).
✅ If it’s neither English nor Indian → use Google Translate.
The service checks how confident it is about each language in the mix and chooses the most likely one to translate from.
Case 3: Single Language
If the text is only in one language:
✅ If it’s an Indian language (like Bengali, Tamil, or Marathi), use Sarvam AI.
✅ If it’s any other language, use Google Translate.
So, we’ve done it.
I’ve included the complete working solutions for you in the GitHub Link.
We’ll cover the detailed performance testing, Optimized configurations & many other useful details in our next post.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
As we’re leaping more & more into the field of Generative AI, one of the frequent questions or challenges people are getting more & more is the performance & other evaluation factors. These factors will eventually bring the fruit of this technology; otherwise, you will end up in technical debt.
This post will discuss the key snippets of the monitoring app based on the Python-based AI app. But before that, let us first view the demo.
Isn’t it exciting?
Let us deep dive into it. But, here is the flow this solution will follow.
So, the current application will invoke the industry bigshots and some relatively unknown or new LLMs.
In this case, we’ll evaluate Anthropic, Open AI, DeepSeek, and Bharat GPT’s various models. However, Bharat GPT is open source, so we’ll use the Huggingface library and execute it locally against my MacBook Pro M4 Max.
The following are the KPIs we’re going to evaluate:
Package Installation:
Here are the lists of dependant python packages that is require to run this application –
clsComprehensiveLLMEvaluator.py (This is the main Python class that will apply all the logic to collect stats involving important KPIs. Note that we’re only going to discuss a few important functions here.)
reference: The correct or expected version of the text.
Calculating BERTScore:
Converts the generated and reference texts into numerical embeddings (mathematical representations) using a pre-trained model (self.sentence_model.encode).
Measures the similarity between the two embeddings using cosine similarity. This gives the bert_score, which ranges from -1 (completely different) to 1 (very similar).
Calculating BLEU Score:
Breaks the generated and reference texts into individual words (tokens) using word_tokenize.
Converts both texts to lowercase for consistent comparison.
Calculates the BLEU Score (sentence_bleu), which checks how many words or phrases in the generated text overlap with the reference. BLEU values range from 0 (no match) to 1 (perfect match).
Calculating METEOR Score:
Also uses the tokenized versions of generated and reference texts.
Calculates the METEOR Score (meteor_score), which considers exact matches, synonyms, and word order. Scores range from 0 (no match) to 1 (perfect match).
Returning the Results:
Combines the three scores into a dictionary with the keys 'bert_score', 'bleu_score', and 'meteor_score'.
Similarly, other functions are developed.
defrun_comprehensive_evaluation(self,evaluation_data: List[Dict]) ->pd.DataFrame:"""Run comprehensive evaluation on all metrics"""results= []foritemin evaluation_data:prompt=item['prompt']reference=item['reference']task_criteria=item.get('task_criteria',{})formodel_nameinself.model_configs.keys(): # Getmultipleresponsestoevaluatereliabilityresponses= [self.get_model_response(model_name,prompt)for_inrange(3) # Get3responsesforreliabilitytesting ] # Usethebestresponseforotherevaluationsbest_response=max(responses,key=lambdax: len(x.content) ifnotx.errorelse0)ifbest_response.error:logging.error(f"Error in model {model_name}: {best_response.error}")continue # Gatherallmetricsmetrics={'model':model_name,'prompt':prompt,'response':best_response.content, **self.evaluate_text_quality(best_response.content, reference), **self.evaluate_factual_accuracy(best_response.content, reference), **self.evaluate_task_performance(best_response.content, task_criteria), **self.evaluate_technical_performance(best_response), **self.evaluate_reliability(responses), **self.evaluate_safety(best_response.content)} # Addbusinessimpactmetricsusingtask performancemetrics.update(self.evaluate_business_impact(best_response,metrics['task_completion'] ))results.append(metrics)returnpd.DataFrame(results)
Input:
evaluation_data: A list of test cases, where each case is a dictionary containing:
prompt: The question or input to the AI model.
reference: The ideal or expected answer.
task_criteria (optional): Additional rules or requirements for the task.
Initialize Results:
An empty list results is created to store the evaluation metrics for each model and test case.
Iterate Through Test Cases:
For each item in the evaluation_data:
Extract the prompt, reference, and task_criteria.
Evaluate Each Model:
Loop through all available AI models (self.model_configs.keys()).
Generate three responses for each model to test reliability.
Select the Best Response:
Out of the three responses, pick the one with the most content (best_response), ignoring responses with errors.
Handle Errors:
If a response has an error, log the issue and skip further evaluation for that model.
Evaluate Metrics:
Using the best_response, calculate a variety of metrics, including:
Text Quality: How similar the response is to the reference.
Factual Accuracy: Whether the response is factually correct.
Task Performance: How well it meets task-specific criteria.
Technical Performance: Evaluate time, memory, or other system-related metrics.
Reliability: Check consistency across multiple responses.
Safety: Ensure the response is safe and appropriate.
Evaluate Business Impact:
Add metrics for business impact (e.g., how well the task was completed, using task_completion as a key factor).
Store Results:
Add the calculated metrics for this model and prompt to the results list.
Return Results as a DataFrame:
Convert the results list into a structured table (a pandas DataFrame) for easy analysis and visualization.
Great! So, now, we’ve explained the code.
Observation from the result:
Let us understand the final outcome of this run & what we can conclude from that.
BERT Score (Semantic Understanding):
GPT4 leads slightly at 0.8322 (83.22%)
Bharat-GPT close second at 0.8118 (81.18%)
Claude-3 at 0.8019 (80.19%)
DeepSeek-Chat at 0.7819 (78.19%) Think of this like a “comprehension score” – how well the models understand the context. All models show strong understanding, with only a 5% difference between best and worst.
BLEU Score (Word-for-Word Accuracy):
Bharat-GPT leads at 0.0567 (5.67%)
Claude-3 at 0.0344 (3.44%)
GPT4 at 0.0306 (3.06%)
DeepSeek-Chat lowest at 0.0189 (1.89%) These low scores suggest models use different wording than references, which isn’t necessarily bad.
METEOR Score (Meaning Preservation):
Bharat-GPT leads at 0.4684 (46.84%)
Claude-3 close second at 0.4507 (45.07%)
GPT4 at 0.2960 (29.60%)
DeepSeek-Chat at 0.2652 (26.52%) This shows how well models maintain meaning while using different words.
Response Time (Speed):
Claude-3 fastest: 4.40 seconds
Bharat-GPT: 6.35 seconds
GPT4: 6.43 seconds
DeepSeek-Chat slowest: 8.52 seconds
Safety and Reliability:
Error Rate: Perfect 0.0 for all models
Toxicity: All very safe (below 0.15%)
Claude-3 safest at 0.0007GPT4 at 0.0008Bharat-GPT at 0.0012
DeepSeek-Chat at 0.0014
Cost Efficiency:
Claude-3 most economical: $0.0019 per response
Bharat-GPT close: $0.0021
GPT4: $0.0038
DeepSeek-Chat highest: $0.0050
Key Takeaways by Model:
Claude-3: ✓ Fastest responses ✓ Most cost-effective ✓ Excellent meaning preservation ✓ Lowest toxicity
Bharat-GPT: ✓ Best BLEU and METEOR scores ✓ Strong semantic understanding ✓ Cost-effective ✗ Moderate response time
GPT4: ✓ Best semantic understanding ✓ Good safety metrics ✗ Higher cost ✗ Moderate response time
These statistics provide reliable comparative data but should be part of a broader decision-making process that includes your specific needs, budget, and use cases.
For the Bharat GPT model, we’ve tested this locally on my MacBook Pro 4 Max. And, the configuration is as follows –
I’ve tried the API version locally, & it provided a similar performance against the stats that we received by running locally. Unfortunately, they haven’t made the API version public yet.
So, apart from the Anthropic & Open AI, I’ll watch this new LLM (Bharat GPT) for overall stats in the coming days.
So, we’ve done it.
You can find the detailed code at the GitHub link.
I’ll bring some more exciting topics in the coming days from the Python verse.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
How does the RAG work better for various enterprise-level Gen AI use cases? What needs to be there to make the LLM model work more efficiently & able to check the response & validate their response, including the bias, hallucination & many more?
This is my post (after a slight GAP), which will capture and discuss some of the burning issues that many AI architects are trying to explore. In this post, I’ve considered a newly formed AI start-up from India, which developed an open-source framework that can easily evaluate all the challenges that one is facing with their LLMs & easily integrate with your existing models for better understanding including its limitations. You will get plenty of insights about it.
But, before we dig deep, why not see the demo first –
Isn’t it exciting? Let’s deep dive into the flow of events.
Architecture:
Let’s explore the broad-level architecture/flow –
Let us understand the steps of the above architecture. First, our Python application needs to trigger and enable the API, which will interact with the Open AI and UpTrain AI to fetch all the LLM KPIs based on the input from the React app named “Evaluation.”
Once the response is received from UpTrain AI, the Python application then organizes the results in a better readable manner without changing the core details coming out from their APIs & then shares that back with the react interface.
Let’s examine the react app’s sample inputs to better understand the input that will be passed to the Python-based API solution, which is wrapper capability to call multiple APIs from the UpTrain & then accumulate them under one response by parsing the data & reorganizing the data with the help of Open AI & sharing that back.
Highlighted in RED are some of the critical inputs you need to provide to get most of the KPIs. And, here are the sample text inputs for your reference –
Q. Enter input question. A. What are the four largest moons of Jupiter? Q. Enter the context document. A. Jupiter, the largest planet in our solar system, boasts a fascinating array of moons. Among these, the four largest are collectively known as the Galilean moons, named after the renowned astronomer Galileo Galilei, who first observed them in 1610. These four moons, Io, Europa, Ganymede, and Callisto, hold significant scientific interest due to their unique characteristics and diverse geological features. Q. Enter LLM response. A. The four largest moons of Jupiter, known as the Galilean moons, are Io, Europa, Ganymede, and Marshmello. Q. Enter the persona response. A. strict and methodical teacher Q. Enter the guideline. A. Response shouldn’t contain any specific numbers Q. Enter the ground truth. A. The Jupiter is the largest & gaseous planet in the solar system. Q. Choose the evaluation method. A. llm
Once you fill in the App should look like this –
Once you fill in, the app should look like the below screenshot –
Package Installation:
Let us understand the sample packages that are required for this task.
1. app.py (This script will consume real-time streaming data coming out from a hosted API source using another popular third-party service named Ably. Ably mimics the pub sub-streaming concept, which might be extremely useful for any start-up. This will then translate into many meaningful KPIs in a streamlit-based dashboard app.)
Note that, we’re not going to discuss the entire script here. Only those parts are relevant. However, you can get the complete scripts in the GitHub repository.
This function will ask the supplied questions with contexts or it will supply the UpTrain results to summarize the JSON into more easily readable plain texts. For our test, we’ve used “gpt-3.5-turbo”.
The above methods initiate the model from UpTrain to get all the stats, which will be helpful for your LLM response. In this post, we’ve captured the following KPIs –
The above method parsed the initial data from UpTrain before sending it to OpenAI for a better summary without changing any text returned by it.
@app.route('/evaluate',methods=['POST'])defevaluate():data=request.jsonifnot data:return{jsonify({'error':'No data provided'}),400} # Extractinginputdataforprocessing (justanexampleofloggingreceiveddata)question=data.get('question','')context=data.get('context','')llmResponse=''personaResponse=data.get('personaResponse','')guideline=data.get('guideline','')groundTruth=data.get('groundTruth','')evaluationMethod=data.get('evaluationMethod','')print('question:')print(question)llmResponse=askFeluda(context,question)print('='*200)print('Response from Feluda::')print(llmResponse)print('='*200) # GettingContextLLMcLLM=evalContextRelevance(question,context,llmResponse,personaResponse)print('&'*200)print('cLLM:')print(cLLM)print(type(cLLM))print('&'*200)results=extractPrintedData(cLLM)print('JSON::')print(results)resJson=jsonify(results)returnresJson
The above function is the main method, which first receives all the input parameters from the react app & then invokes one-by-one functions to get the LLM response, and LLM performance & finally summarizes them before sending it to react-app.
For any other scripts, please refer to the above-mentioned GitHub link.
Run:
Let us see some of the screenshots of the test run –
So, we’ve done it.
I’ll bring some more exciting topics in the coming days from the Python verse.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
This new solution will evaluate the power of Stable Defussion, which is created solutions as we progress & refine our prompt from scratch by using Stable Defussion & Python. This post opens new opportunities for IT companies & business start-ups looking to deliver solutions & have better performance compared to the paid version of Stable Defussion AI’s API performance. This project is for the advanced Python, Stable Defussion for data Science Newbies & AI evangelists.
In a series of posts, I’ll explain and focus on the Stable Defussion API and custom solution using the Python-based SDK of Stable Defussion.
But, before that, let us view the video that it generates from the prompt by using the third-party API:
Prompt to Video
And, let us understand the prompt that we supplied to create the above video –
Lighthouse on a cliff overlooking the ocean, dynamic ocean waves crashing against rocks, dramatic clouds moving across sky, photorealistic water movement, mist and ocean spray, wind-driven waves, atmospheric sky motion, natural fluid dynamics, realistic, detailed, 8k. Do not change the size & shape of the lighthouse & the field on top of which the Lighthouse built.
Isn’t it exciting?
However, I want to stress this point: the video generated by the Stable Defusion (Stability AI) API was able to partially apply the animation effect. Even though the animation applies to the cloud, It doesn’t apply the animation to the wave. But, I must admit, the quality of the video is quite good.
Let us understand the code and how we run the solution, and then we can try to understand its performance along with the other solutions later in the subsequent series.
As you know, we’re exploring the code base of the third-party API, which will actually execute a series of API calls that create a video out of the prompt.
CODE:
Let us understand some of the important snippet –
classclsStabilityAIAPI:def__init__(self, STABLE_DIFF_API_KEY, OUT_DIR_PATH, FILE_NM, VID_FILE_NM):self.STABLE_DIFF_API_KEY = STABLE_DIFF_API_KEYself.OUT_DIR_PATH = OUT_DIR_PATHself.FILE_NM = FILE_NMself.VID_FILE_NM = VID_FILE_NMdefdelFile(self, fileName):try: # Deletingtheintermediateimageos.remove(fileName)return 0 exceptExceptionase:x = str(e)print('Error: ', x)return 1defgenerateText2Image(self, inputDescription):try:STABLE_DIFF_API_KEY = self.STABLE_DIFF_API_KEYfullFileName = self.OUT_DIR_PATH + self.FILE_NMifSTABLE_DIFF_API_KEYisNone:raiseException("MissingStabilityAPIkey.")response = requests.post(f"{api_host}/v1/generation/{engine_id}/text-to-image",headers={"Content-Type":"application/json","Accept":"application/json","Authorization":f"Bearer {STABLE_DIFF_API_KEY}"},json={"text_prompts": [{"text":inputDescription}],"cfg_scale":7,"height":1024,"width":576,"samples":1,"steps":30,},)ifresponse.status_code!=200:raiseException("Non-200 response: "+str(response.text))data=response.json()fori,imageinenumerate(data["artifacts"]):withopen(fullFileName,"wb") as f:f.write(base64.b64decode(image["base64"])) returnfullFileNameexceptExceptionas e:x=str(e)print('Error: ',x)return'N/A'defimage2VideoPassOne(self,imgNameWithPath):try:STABLE_DIFF_API_KEY=self.STABLE_DIFF_API_KEYresponse=requests.post(f"https://api.stability.ai/v2beta/image-to-video",headers={"authorization":f"Bearer {STABLE_DIFF_API_KEY}"},files={"image":open(imgNameWithPath,"rb")},data={"seed":0,"cfg_scale":1.8,"motion_bucket_id":127}, )print('First Pass Response:')print(str(response.text))genID=response.json().get('id')returngenIDexceptExceptionas e:x=str(e)print('Error: ',x)return'N/A'defimage2VideoPassTwo(self,genId):try:generation_id=genIdSTABLE_DIFF_API_KEY=self.STABLE_DIFF_API_KEYfullVideoFileName=self.OUT_DIR_PATH+self.VID_FILE_NMresponse=requests.request("GET",f"https://api.stability.ai/v2beta/image-to-video/result/{generation_id}",headers={'accept':"video/*", # Use 'application/json' to receive base64 encoded JSON'authorization':f"Bearer {STABLE_DIFF_API_KEY}"},) print('Retrieve Status Code: ',str(response.status_code))ifresponse.status_code==202:print("Generation in-progress, try again in 10 seconds.")return5elifresponse.status_code==200:print("Generation complete!")withopen(fullVideoFileName,'wb') as file:file.write(response.content)print("Successfully Retrieved the video file!")return0else:raiseException(str(response.json()))exceptExceptionas e:x=str(e)print('Error: ',x)return1
Now, let us understand the code –
1. CLASS INSTANTIATION
This function is called when an object of the class is created. It initializes four properties:
STABLE_DIFF_API_KEY: the API key for Stability AI services.
OUT_DIR_PATH: the folder path to save files.
FILE_NM: the name of the generated image file.
VID_FILE_NM: the name of the generated video file.
2. delFile(fileName)
This function deletes a file specified by fileName.
If successful, it returns 0.
If an error occurs, it logs the error and returns 1.
3. generateText2Image(inputDescription)
This function generates an image based on a text description:
Sends a request to the Stability AI text-to-image endpoint using the API key.
Saves the resulting image to a file.
Returns the file’s path on success or 'N/A' if an error occurs.
4. image2VideoPassOne(imgNameWithPath)
This function uploads an image to create a video in its first phase:
Sends the image to Stability AI’s image-to-video endpoint.
Logs the response and extracts the id (generation ID) for the next phase.
Returns the id if successful or 'N/A' on failure.
5. image2VideoPassTwo(genId)
This function retrieves the video created in the second phase using the genId:
Checks the video generation status from the Stability AI endpoint.
If complete, saves the video file and returns 0.
If still processing, returns 5.
Logs and returns 1 for any errors.
As you can see, the code is pretty simple to understand & we’ve taken all the necessary actions in case of any unforeseen network issues or even if the video is not ready after our job submission in the following lines of the main calling script (generateText2VideoAPI.py) –
Please let me know your feedback after reviewing all the posts! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
Today, I’ll be publishing a series of posts on LLM agents and how they can help you improve your delivery capabilities for various tasks.
Also, we’re providing the demo here –
Isn’t it exciting?
Process Flow:
The application will interact with the AutoGen agents, use underlying Open AI APIs to follow the instructions, generate the steps, and then follow that path to generate the desired code. Finally, it will execute the generated scripts if the first outcome of the demo satisfies users.
Function: Sets the logging level to only capture error messages to avoid cluttering the output.
Role: Helps in debugging by capturing and displaying error messages.
Defining the buildAndPlay Method:
defbuildAndPlay(self,inputPrompt):try: user_proxy.initiate_chat( assistant,message=f"We need to solve the following problem: {inputPrompt}. ""Please coordinate with the admin, engineer, game_designer, planner and critic to provide a comprehensive solution. ")return0exceptExceptionas e: x =str(e)print('Error: <<Real-time Translation>>: ', x)return1
Purpose: Defines a method to initiate the problem-solving process.
Function:
Parameters: Takes inputPrompt, which is the problem to be solved.
Action:
Calls user_proxy.initiate_chat() to start a conversation between the user proxy agent and the assistant agent.
Sends a message requesting coordination among all agents to provide a comprehensive solution to the problem.
Error Handling: If an exception occurs, it prints an error message and returns 1.
Role: Initiates collaboration among all agents to solve the provided problem.
Summary of the Workflow:
Agents Setup: Multiple agents with specialized roles are created. Initiating Conversation: The buildAndPlay method starts a conversation, asking agents to collaborate. Problem Solving: Agents communicate and coordinate to provide a comprehensive solution to the input problem. Error Handling: The system captures and logs any errors that occur during execution.
We’ll continue to discuss this topic in the upcoming post.
I’ll bring some more exciting topics in the coming days from the Python verse.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. There is always room for improvement in this kind of model & the solution associated with it. I’ve shown the basic ways to achieve the same for educational purposes only.
At the recent Argyle AI Summit, a prestigious event in the AI industry, I had the honor of participating as a speaker alongside esteemed professionals like Misha Leybovich from Google Labs. The summit, coordinated by Sylvia Das Chagas, a former senior AI conversation designer at CVS Health, provided an enlightening platform to discuss the evolving role of AI in talent management. Our session focused on the theme “Driving Talent with AI,” addressing some of the most pressing questions in the field. Frequently, relevant use cases were shared in detail to support these threads.
To view the actual page, please click the following link.
Impact of AI on Talent Management
One of the critical topics we explored was AI’s impact on talent management in the upcoming year. AI’s influence in hiring and retention is becoming increasingly significant. For example, AI-powered tools can now analyze vast amounts of data to identify the best candidates for a role, going beyond traditional resume screening. In retention, AI is instrumental in identifying patterns that indicate an employee’s likelihood to leave, enabling proactive measures.
Dispelling Fears Around AI Replacing Jobs
A burning question in AI is how leaders address fears that AI might replace manual jobs. We discussed the importance of leaders framing AI as a complement to human skills rather than a replacement. AI enhances employee capabilities by automating mundane tasks, allowing employees to focus on more creative and strategic work.
Innovative AI Tools for Organizations
Regarding new AI tools that organizations should watch out for, the conversation highlighted tools that enhance remote collaboration and workplace inclusivity. Tools like virtual meeting assistants that can transcribe, translate, and summarize meetings in real time are becoming invaluable in today’s global work environment.
AI in Boosting Employee Motivation and Productivity
AI’s role in boosting employee motivation and productivity was another focal point. We discussed how AI-driven career development programs can offer personalized learning paths, helping employees grow and stay motivated.
Incorporating Multilingual Capabilities in AI Tools
Incorporating multiple languages in tools like ChatGPT was highlighted as a critical step towards inclusivity. This expansion allows a broader range of employees to interact with AI tools in their native language, fostering a more inclusive workplace environment.
Addressing Reluctance to Change
Lastly, we tackled the challenge of addressing employees’ reluctance to change. Emphasizing the importance of transparent communication and education about AI’s benefits was identified as key. Organizations can alleviate fears and encourage a more accepting attitude towards AI by involving employees in the AI implementation process and providing training.
Conclusion
The Argyle AI Summit offered a compelling glimpse into the future of AI in talent management. The session provided valuable insights for leaders looking to harness AI’s potential to enhance talent management strategies by discussing real-world examples and strategies. To gain more in-depth knowledge and perspectives shared during this summit, I encourage interested parties to visit the recorded session link for a more comprehensive understanding.
Or, you can directly view it from here –
Feedback Request
I would greatly appreciate your feedback on the insights shared during the summit. Your thoughts and perspectives are invaluable as we continue to explore and navigate the evolving landscape of AI in the workplace.
Note: Video content hosted at a third-party site by the summit organizer & not by me.
Today, I’ll be presenting another exciting capability of architecture in the world of LLMs, where you need to answer one crucial point & that is how valid the response generated by these LLMs is against your data. This response is critical when discussing business growth & need to take the right action at the right time.
Why not view the demo before going through it?
Demo
Isn’t it exciting? Great! Let us understand this in detail.
Flow of Architecture:
The first dotted box (extreme-left) represents the area that talks about the data ingestion from different sources, including third-party PDFs. It is expected that organizations should have ready-to-digest data sources. Examples: Data Lake, Data Mart, One Lake, or any other equivalent platforms. Those PDFs will provide additional insights beyond the conventional advanced analytics.
You need to have some kind of OCR solution that will extract all the relevant information in the form of text from the documents.
The next important part is how you define the chunking & embedding of data chunks into Vector DB. Chunking & indexing strategies, along with the overlapping chain, play a crucial importance in tying that segregated piece of context into a single context that will be fed into the source for your preferred LLMs.
This system employs a vector similarity search to browse through unstructured information and concurrently accesses the database to retrieve the context, ensuring that the responses are not only comprehensive but also anchored in validated knowledge.
This approach is particularly vital for addressing multi-hop questions, where a single query can be broken down into multiple sub-questions and may require information from numerous documents to generate an accurate answer.
clsFeedVectorDB.py (This is the main class that will invoke the Faiss framework to contextualize the docs inside the vector DB with the source file name to validate the answer from Gen AI using Globe.6B embedding models.)
Let us understand some of the key snippets from the above script (Full scripts will be available in the GitHub Repo) –
# Samplefunctiontoconverttexttoavectordeftext2Vector(self,text): # Encode the text using the tokenizerwords = [wordforwordintext.lower().split()ifwordinself.model] # Ifnowordsinthemodel, returnazerovectorifnot words:returnnp.zeros(self.model.vector_size) # Computetheaverageofthewordvectorsvector=np.mean([self.model[word] forwordinwords],axis=0)returnvector.reshape(1,-1)
This code is for a function called “text2Vector” that takes some text as input and converts it into a numerical vector. Let me break it down step by step:
It starts by taking some text as input, and this text is expected to be a sentence or a piece of text.
The text is then split into individual words, and each word is converted to lowercase.
It checks if each word is present in a pre-trained language model (probably a word embedding model like Word2Vec or GloVe). If a word is not in the model, it’s ignored.
If none of the words from the input text are found in the model, the function returns a vector filled with zeros. This vector has the same size as the word vectors in the model.
If there are words from the input text in the model, the function calculates the average vector of these words. It does this by taking the word vectors for each word found in the model and computing their mean (average). This results in a single vector that represents the input text.
Finally, the function reshapes this vector into a 2D array with one row and as many columns as there are elements in the vector. The reason for this reshaping is often related to compatibility with other parts of the code or libraries used in the project.
So, in simple terms, this function takes a piece of text, looks up the word vectors for the words in that text, and calculates the average of those vectors to create a single numerical representation of the text. If none of the words are found in the model, it returns a vector of zeros.
defgenData(self):try:basePath=self.basePathmodelFileName=self.modelFileNamevectorDBPath=self.vectorDBPathvectorDBFileName=self.vectorDBFileName # CreateaFAISSindexdimension=int(cf.conf['NO_OF_MODEL_DIM']) # Assuming100-dimensionalvectorsindex=faiss.IndexFlatL2(dimension)print('*'*240)print('Vector Index Your Data for Retrieval:')print('*'*240)FullVectorDBname=vectorDBPath+vectorDBFileNameindexFile=str(vectorDBPath) +str(vectorDBFileName) +'.index'print('File: ',str(indexFile))data={} # Listallfilesinthespecifieddirectoryfiles=os.listdir(basePath) # Filteroutfilesthatarenottextfilestext_files= [fileforfileinfilesiffile.endswith('.txt')] # Readeachtextfileforfilein text_files:file_path=os.path.join(basePath,file)print('*'*240)print('Processing File:')print(str(file_path))try: # Attempttoopenwithutf-8encodingwithopen(file_path,'r',encoding='utf-8') as file:forline_number,lineinenumerate(file,start=1): # Assumeeachlineisaseparatedocumentvector=self.text2Vector(line)vector=vector.reshape(-1)index_id=index.ntotalindex.add(np.array([vector])) # Addingthevectortotheindexdata[index_id] ={'text':line,'line_number':line_number,'file_name':file_path} # Storingthelineandfilenameexcept UnicodeDecodeError: # Ifutf-8fails,tryadifferentencodingtry:withopen(file_path,'r',encoding='ISO-8859-1') as file:forline_number,lineinenumerate(file,start=1): # Assumeeachlineisaseparatedocumentvector=self.text2Vector(line)vector=vector.reshape(-1)index_id=index.ntotalindex.add(np.array([vector])) # Addingthevectortotheindexdata[index_id] ={'text':line,'line_number':line_number,'file_name':file_path} # StoringthelineandfilenameexceptExceptionas e:print(f"Could not read file {file}: {e}")continueprint('*'*240) # SavethedatadictionaryusingpickledataCache=vectorDBPath+modelFileNamewithopen(dataCache,'wb') as f:pickle.dump(data,f) # Savetheindexanddataforlaterusefaiss.write_index(index,indexFile)print('*'*240)return0exceptExceptionas e:x=str(e)print('Error: ',x)return1
This code defines a function called genData, and its purpose is to prepare and store data for later retrieval using a FAISS index. Let’s break down what it does step by step:
It starts by assigning several variables, such as basePath, modelFileName, vectorDBPath, and vectorDBFileName. These variables likely contain file paths and configuration settings.
It creates a FAISS index with a specified dimension (assuming 100-dimensional vectors in this case) using faiss.IndexFlatL2. FAISS is a library for efficient similarity search and clustering of high-dimensional data.
It prints the file name and lines where the index will be stored. It initializes an empty dictionary called data to store information about the processed text data.
It lists all the files in a directory specified by basePath. It filters out only the files that have a “.txt” extension as text files.
It then reads each of these text files one by one. For each file:
It attempts to open the file with UTF-8 encoding.
It reads the file line by line.
For each line, it calls a function text2Vector to convert the text into a numerical vector representation. This vector is added to the FAISS index.
It also stores some information about the line, such as the line number and the file name, in the data dictionary.
If there is an issue with UTF-8 encoding, it tries to open the file with a different encoding, “ISO-8859-1”. The same process of reading and storing data continues.
If there are any exceptions (errors) during this process, it prints an error message but continues processing other files.
Once all the files are processed, it saves the data dictionary using the pickle library to a file specified by dataCache.
It also saves the FAISS index to a file specified by indexFile.
Finally, it returns 0 if the process completes successfully or 1 if there was an error during execution.
In summary, this function reads text files, converts their contents into numerical vectors, and builds a FAISS index for efficient similarity search. It also saves the processed data and the index for later use. If there are any issues during the process, it prints error messages but continues processing other files.
clsRAGOpenAI.py (This is the main class that will invoke the RAG class, which will get the contexts with references including source files, line numbers, and source texts. This will help the customer to validate the source against the OpenAI response to understand & control the data bias & other potential critical issues.)
Let us understand some of the key snippets from the above script (Full scripts will be available in the GitHub Repo) –
defragAnswerWithHaystackAndGPT3(self,queryVector,k,question):modelName=self.modelNamemaxToken=self.maxTokentemp=self.temp # AssuminggetTopKContextsisamethodthatreturnsthetopKcontextscontexts=self.getTopKContexts(queryVector,k)messages= [] # Addcontextsas system messagesforfile_name,line_number,textin contexts:messages.append({"role":"system","content":f"Document: {file_name} \nLine Number: {line_number} \nContent: {text}"})prompt=self.generateOpenaiPrompt(queryVector,k)prompt=prompt+"Question: "+str(question) +". \n Answer based on the above documents." # Adduserquestionmessages.append({"role":"user","content":prompt}) # Createchatcompletioncompletion=client.chat.completions.create(model=modelName,messages=messages,temperature=temp,max_tokens=maxToken ) # Assumingthelastmessageintheresponseistheanswerlast_response=completion.choices[0].message.contentsource_refernces= ['FileName: '+str(context[0]) +' - Line Numbers: '+str(context[1]) +' - Source Text (Reference): '+str(context[2]) forcontextincontexts]returnlast_response,source_refernces
This code defines a function called ragAnswerWithHaystackAndGPT3. Its purpose is to use a combination of the Haystack search method and OpenAI’s GPT-3 model to generate an answer to a user’s question. Let’s break down what it does step by step:
It starts by assigning several variables, such as modelName, maxToken, and temp. These variables likely contain model-specific information and settings for GPT-3.
It calls a method getTopKContexts to retrieve the top K contexts (which are likely documents or pieces of text) related to the user’s query. These contexts are stored in the contexts variable.
It initializes an empty list called messages to store messages that will be used in the conversation with the GPT-3 model.
It iterates through each context and adds them as system messages to the messages list. These system messages provide information about the documents or sources being used in the conversation.
It creates a prompt that combines the query, retrieved contexts, and the user’s question. This prompt is then added as a user message to the messages list. It effectively sets up the conversation for GPT-3, where the user’s question is followed by context.
It makes a request to the GPT-3 model using the client.chat.completions.create method, passing in the model name, the constructed messages, and other settings such as temperature and maximum tokens.
After receiving a response from GPT-3, it assumes that the last message in the response contains the answer generated by the model.
It also constructs source_references, which is a list of references to the documents or sources used in generating the answer. This information includes the file name, line numbers, and source text for each context.
Finally, it returns the generated answer (last_response) and the source references to the caller.
In summary, this function takes a user’s query, retrieves relevant contexts or documents, sets up a conversation with GPT-3 that includes the query and contexts, and then uses GPT-3 to generate an answer. It also provides references to the sources used in generating the answer.
This code defines a function called getTopKContexts. Its purpose is to retrieve the top K relevant contexts or pieces of information from a pre-built index based on a query vector. Here’s a breakdown of what it does:
It takes two parameters as input: queryVector, which is a numerical vector representing a query, and k, which specifies how many relevant contexts to retrieve.
Inside a try-except block, it attempts the following steps:
It uses the index.search method to find the top K closest contexts to the given queryVector. This method returns two arrays: distances (measuring how similar the contexts are to the query) and indices (indicating the positions of the closest contexts in the data).
It creates a list called “resDict", which contains tuples for each of the top K contexts. Each tuple contains three pieces of information: the file name (file_name), the line number (line_number), and the text content (text) of the context. These details are extracted from a data dictionary.
If the process completes successfully, it returns the list of top K contexts (resDict) to the caller.
If there’s an exception (an error) during this process, it captures the error message as a string (x), prints the error message, and then returns the error message itself.
In summary, this function takes a query vector and finds the K most relevant contexts or pieces of information based on their similarity to the query. It returns these contexts as a list of tuples containing file names, line numbers, and text content. If there’s an error, it prints an error message and returns the error message string.
defgenerateOpenaiPrompt(self,queryVector,k):contexts=self.getTopKContexts(queryVector,k)template=ct.templateVal_1prompt=templateforfile_name,line_number,textin contexts:prompt+=f"Document: {file_name}\n Line Number: {line_number} \n Content: {text}\n\n"returnprompt
This code defines a function called generateOpenaiPrompt. Its purpose is to create a prompt or a piece of text that combines a template with information from the top K relevant contexts retrieved earlier. Let’s break down what it does:
It starts by calling the getTopKContexts function to obtain the top K relevant contexts based on a given queryVector.
It initializes a variable called template with a predefined template value (likely defined elsewhere in the code).
It sets the prompt variable to the initial template.
Then, it enters a loop where it iterates through each of the relevant contexts retrieved earlier (contexts are typically documents or text snippets).
For each context, it appends information to the prompt. Specifically, it adds lines to the prompt that include:
The document’s file name (Document: [file_name]).
The line number within the document (Line Number: [line_number]).
The content of the context itself (Content: [text]).
It adds some extra spacing (newlines) between each context to ensure readability.
Finally, it returns the complete – prompt, which is a combination of the template and information from the relevant contexts.
In summary, this function takes a query vector, retrieves relevant contexts, and creates a prompt by combining a template with information from these contexts. This prompt can then be used as input for an AI model or system, likely for generating responses or answers based on the provided context.
Let us understand the directory structure of this entire application –
To learn more about this package, please visit the following GitHub link.
So, finally, we’ve done it. I know that this post is relatively smaller than my earlier post. But, I think, you can get a good hack to improve some of your long-running jobs by applying this trick.
I’ll bring some more exciting topics in the coming days from the Python verse. Please share & subscribe to my post & let me know your feedback.
Till then, Happy Avenging! 🙂
Note: All the data & scenarios posted here are representational data & scenarios & available over the internet & for educational purposes only. Some of the images (except my photo) we’ve used are available over the net. We don’t claim ownership of these images. There is always room for improvement & especially in the prediction quality.


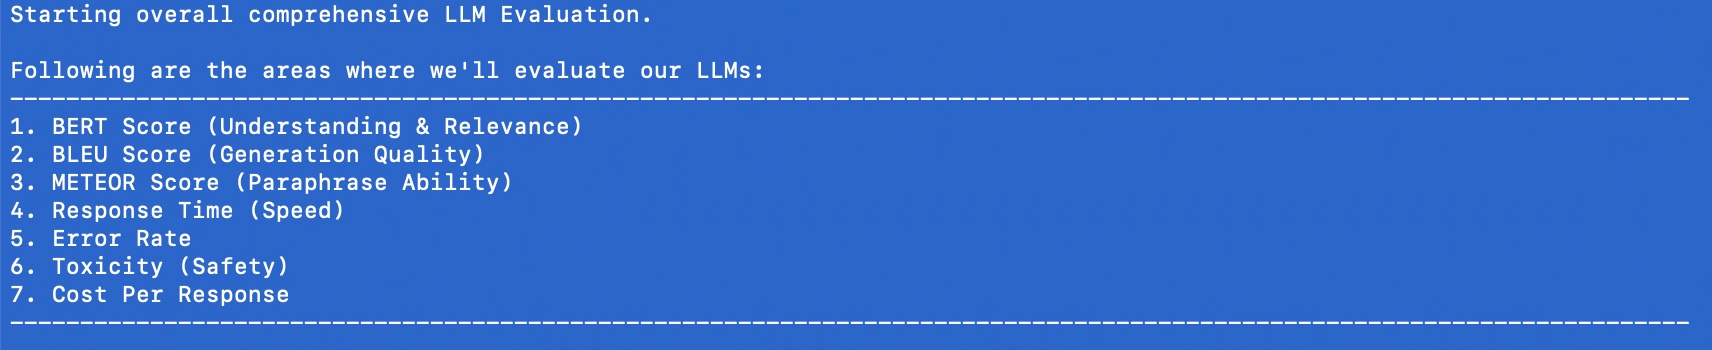




You must be logged in to post a comment.